Category: Embedded

  • 2026’s Hottest Cars Under ₹15 Lakh :Which One Should You Pick ?

    Looking for the best car under ₹15 lakh in 2026? Discover the hottest compact SUVs, hatchbacks, and sedans that combine style, features, and affordability. Find out which one suits your lifestyle!

    If you’re planning to buy a car in 2026 and your budget is under ₹15 lakh, you’re in luck! The upcoming year is packed with exciting launches and refreshed models that combine style, performance, and modern features without breaking the bank. From compact SUVs to sedans, there’s something for everyone. Let’s dive into the top options that promise a perfect blend of technology, comfort, and value.

    1. Tata Punch – Compact Yet Powerful

    The Tata Punch has already made waves in the Indian market as a compact SUV with a bold design and rugged appeal. In 2026, Tata is expected to introduce upgraded variants with enhanced infotainment systems, improved safety features, and slightly more powerful engines.
    Why buy it:

    • Tall stance and SUV-like design make it ideal for city and highway driving.
    • Multiple driving modes for a versatile experience.
    • Advanced safety features including ABS, airbags, and ESP in top variants.

    If you want a small SUV that stands out in traffic, the Tata Punch is a strong contender under ₹15 lakh.

    2. Hyundai i20 – Premium Hatchback Experience

    The Hyundai i20 has been a favorite among urban buyers who want style and sophistication. The 2026 edition promises upgraded tech features like larger touchscreen displays, wireless Apple CarPlay and Android Auto, and connected car features for a smarter drive.
    Why buy it:

    • Stylish exterior with a premium feel inside.
    • Smooth driving experience with refined petrol and diesel options.
    • Top-notch infotainment system with multiple connectivity options.

    For those who love hatchbacks but crave a premium experience, the i20 continues to impress without stretching your budget.

    3. Kia Sonet – The Compact SUV That Packs Punch

    The Kia Sonet remains one of the most popular compact SUVs in India, and 2026 will see new trims with enhanced design tweaks and connected car technology. It’s perfect for buyers who want SUV looks, practicality, and modern features in a sub-₹15 lakh price bracket.
    Why buy it:

    • Bold design with sleek LED lights and floating roof option.
    • Turbocharged petrol options for spirited drives.
    • Connected car features and touchscreen infotainment with navigation.

    Its combination of style, features, and performance makes it a fun yet practical choice for young buyers.

    4. Maruti Suzuki Baleno – Reliable and Efficient

    Maruti Suzuki Baleno has been a top seller for years due to its reliability and fuel efficiency. In 2026, expect subtle cosmetic updates, better interiors, and tech upgrades to keep it competitive.
    Why buy it:

    • Low maintenance cost and excellent fuel efficiency.
    • Spacious cabin suitable for small families.
    • SmartPlay Studio infotainment system for easy connectivity.

    For those who prioritize a hassle-free ownership experience and proven reliability, the Baleno remains unbeatable under ₹15 lakh.

    5. Hyundai Creta – Small Yet Mighty SUV

    Although the Creta usually touches higher price points, certain base and mid-variants are expected to fall under ₹15 lakh in 2026. It’s ideal if you want a slightly bigger SUV with modern features and a comfortable ride.
    Why buy it:

    • Premium styling with a commanding road presence.
    • Smooth automatic and manual transmission options.
    • Feature-rich cabin with connected car technology.

    If you’re looking to upgrade to a bigger SUV without exceeding ₹15 lakh, the Creta could be the ultimate choice.

    Final Verdict – What’s the Best Pick?

    Choosing the best car under ₹15 lakh in 2026 depends on your priorities:

    • Style & Tech: Kia Sonet or Hyundai i20
    • Urban-Friendly SUV: Tata Punch
    • Reliability & Efficiency: Maruti Suzuki Baleno
    • Premium Small SUV: Hyundai Creta

    Each of these options brings something unique to the table. If you love SUV vibes on a city budget, Tata Punch and Kia Sonet are hard to beat. If comfort, efficiency, and proven reliability matter most, Baleno and i20 will not disappoint. For a slightly bigger SUV experience, Creta offers premium feel without overshooting your budget.

    Quick Tip: Always test-drive the car, check feature variants, and compare long-term running costs before making a decision. The right choice is the one that matches your lifestyle, not just your budget.

    FAQ – Cars Under ₹15 Lakh in 2026

    1. Which is the best car under ₹15 lakh in 2026?
    The best choice depends on your priorities. For style and tech, consider the Kia Sonet or Hyundai i20. For urban-friendly SUVs, Tata Punch is ideal. For reliability and efficiency, Maruti Suzuki Baleno stands out, while Hyundai Creta offers a premium small SUV experience.

    2. Are SUVs available under ₹15 lakh in 2026?
    Yes! Compact SUVs like Tata Punch, Kia Sonet, and certain variants of Hyundai Creta are expected to be under ₹15 lakh, offering SUV styling, good ground clearance, and modern features.

    3. Which car is most fuel-efficient under ₹15 lakh?
    Maruti Suzuki Baleno and Hyundai i20 are among the most fuel-efficient options in this price range, making them ideal for city commuting and long drives.

    4. Should I buy a hatchback or SUV under ₹15 lakh?
    If you want easier maneuverability and lower running costs, hatchbacks like i20 or Baleno are great. If you prefer a commanding road presence, rugged looks, and slightly higher seating, compact SUVs like Tata Punch or Kia Sonet are better.

    5. Will these cars have modern tech features in 2026?
    Absolutely. Expect touchscreen infotainment, connected car features, LED lighting, multiple driving modes, and safety systems like ABS, airbags, and ESP in top variants.

    6. How do I choose the right variant under ₹15 lakh?
    Consider your priorities: budget, features, fuel type, and usage. Test drive your shortlisted cars and compare long-term running costs before making a decision.

  • Nvidia’s $20B Groq AI Deal — A Game-Changer for AI Chips and Investors

    Nvidia’s $20B deal with Groq AI could reshape the AI chip market, impact Groq stock, and redefine real-time AI performance. Learn what this means for investors and technology

    Breaking news: Nvidia has made headlines with a massive $20 billion deal involving Groq, the AI chip startup. This strategic move is already sending ripples through the tech world, investors, and AI enthusiasts alike. Here’s why this matters to everyone — from casual tech users to market watchers.

    The Deal That Shook the AI World

    Nvidia will license Groq’s AI chip technology and bring key founders, including Jonathan Ross and Sunny Madra, onto its team. This arrangement strengthens Nvidia’s AI portfolio without fully acquiring Groq, allowing the startup to continue its operations independently.

    The deal is valued at roughly $20 billion, a landmark figure that could reshape Nvidia’s future in real-time AI and inference technology.

    Why Groq AI Tech Is a Big Deal

    Groq builds high-speed AI inference chips, designed to process real-time workloads like large language models (LLMs) faster than traditional GPUs.

    • Speed and efficiency: Groq chips handle AI predictions at lightning speed.
    • Real-time AI: Perfect for applications like chatbots, recommendation engines, and autonomous systems.
    • Strategic fit: Nvidia already dominates AI training. Groq adds power in the inference stage — a key growth area.

    This combination positions Nvidia to dominate the full AI lifecycle, from training to deployment.

    What Investors Are Watching

    The market is buzzing over Groq stock and valuation implications. The $20B deal represents a massive premium over Groq’s previous valuation, highlighting strong confidence in the startup’s technology and potential.

    Investors are closely tracking:

    • Groq stock future: How independent operations will continue.
    • Nvidia stock reaction: Short-term dips may occur, but long-term growth potential is promising.
    • AI market competition: Other companies may accelerate development to compete with Nvidia + Groq synergy.

    Broader Industry Impact

    This move signals a new era for AI hardware:

    • Inference-focused competition: Nvidia strengthens its position against other chipmakers in real-time AI.
    • Talent acquisition: Bringing Groq’s founders into Nvidia ensures knowledge transfer and innovation continuity.
    • Tech adoption acceleration: Faster inference chips could spur adoption of AI tools in businesses and everyday life.

    Bottom Line

    Nvidia’s $20B Groq AI deal is more than just a financial headline — it’s a strategic play that could redefine the AI chip market. For investors, tech fans, and developers, this deal marks a critical step toward faster, smarter, and more efficient AI.

    Whether you follow AI, investing, or tech trends, Nvidia + Groq is a story that’s impossible to ignore.

    FAQ : Nvidia & Groq AI Deal

    Q1: What is the Nvidia and Groq AI deal about?

    A1: Nvidia is licensing Groq’s high-speed AI inference technology and bringing key founders onto its team. The deal is valued at around $20 billion and strengthens Nvidia’s position in real-time AI chips.

    Q2: Will Groq continue operating independently?

    A2: Yes. Groq remains an independent startup, focusing on its AI chip roadmap, cloud services, and future innovations.

    Q3: How does this deal affect Nvidia’s AI strategy?

    A3: Nvidia already leads in AI training GPUs. Groq’s chips specialize in real-time inference, making Nvidia strong across the full AI lifecycle from training to deployment.

    Q4: What does this mean for Groq stock?

    A4: The deal represents a massive premium over Groq’s previous valuation. Investors are watching closely, as the startup will continue operating independently while contributing technology to Nvidia.

    Q5: Why should tech enthusiasts care about this deal?

    A5: Groq’s chips enable faster AI processing for applications like chatbots, autonomous systems, and recommendation engines. The deal could accelerate AI adoption globally.

    Q6: Is this good news for AI innovation?

    A6: Absolutely. By combining Nvidia’s market reach with Groq’s inference expertise, the deal could speed up the development and deployment of cutting-edge AI applications.
  • 7 Master Reasons Why Is Yocto Used Rather Than Directly Using a Linux OS

    Why is Yocto used instead of a traditional Linux OS? Learn how Yocto builds custom embedded Linux systems and why it beats Ubuntu or Debian for devices.

    If Linux is already powerful, flexible, and open source, a very natural question comes up for anyone entering embedded systems:

    Why is Yocto used rather than directly using a Linux OS?

    Why not just install Ubuntu, Debian, or some other Linux distribution and move on?

    This question is asked by beginners, debated by intermediate developers, and still carefully considered by experienced embedded Linux engineers. The short answer is simple: embedded systems have very different requirements than desktop or server Linux. The long answer is what this article is about.

    Let’s break it down calmly, honestly, and practically

    What is the Yocto Project in simple terms?

    Before comparing yocto vs linux os, let’s clear up one major confusion.

    Yocto is NOT an operating system.
    Yocto is NOT a Linux distribution.

    The Yocto Project is a build system and framework that helps you create your own custom Linux distribution specifically for embedded devices.

    Think of Yocto as:

    • A factory, not the product
    • A kitchen, not the meal
    • A toolchain for building Linux, not Linux itself

    Using Yocto, you define:

    • Which kernel to use
    • Which drivers are included
    • Which libraries exist
    • Which services start at boot
    • How big the final image should be
    • How updates and security patches are handled

    This is why people often ask:

    • Is Yocto a Linux distribution? No.
    • Is Yocto an operating system? No.

    Yocto builds a custom Linux OS tailored exactly for your hardware and product.

    What does “using Linux directly” mean in embedded systems?

    When people say “just use Linux directly,” they usually mean:

    • Installing Ubuntu
    • Using Debian
    • Using Fedora
    • Using Red Hat
    • Using Ubuntu Core

    These are general-purpose Linux distributions. They are designed for:

    • PCs
    • Laptops
    • Servers
    • Cloud environments

    They assume:

    • Plenty of RAM
    • Large storage
    • Keyboard, mouse, display
    • Frequent package updates
    • Human interaction

    Embedded systems are different.

    An embedded device might have:

    • 128 MB RAM
    • 256 MB flash
    • No display
    • No keyboard
    • Boot time requirements
    • Real-time constraints
    • A product lifecycle of 10 to 15 years

    This difference is the root of yocto vs linux debates.

    Yocto vs Linux OS: the fundamental difference

    Here is the core idea:

    Linux is a kernel.
    Ubuntu, Debian, Red Hat are distributions.
    Yocto is a build system to create distributions.

    When you use Ubuntu:

    • You adapt your product to the OS

    When you use Yocto:

    • You adapt the OS to your product

    That single difference explains why Yocto dominates embedded Linux.

    Yocto vs Ubuntu for embedded systems

    Let’s talk about the most common comparison: yocto vs ubuntu.

    Ubuntu is great when:

    • You want fast prototyping
    • You have powerful hardware
    • You want quick access to packages
    • Storage and RAM are not critical

    Ubuntu struggles when:

    • You need a minimal image
    • You need full control over boot
    • You need reproducible builds
    • You need long-term maintenance without surprise updates

    With Yocto:

    • You decide exactly what goes into the root filesystem
    • You remove everything unnecessary
    • You control every dependency
    • You rebuild the same image years later

    This is why yocto linux vs ubuntu strongly favors Yocto for production devices.

    Yocto vs Debian

    Debian is stable, reliable, and loved by many engineers. So why not Debian?

    In a yocto vs debian comparison:

    Debian:

    • Uses prebuilt binary packages
    • Assumes general-purpose hardware
    • Pulls in many indirect dependencies
    • Is harder to strip down safely

    Yocto:

    • Builds everything from source
    • Creates a minimal root filesystem
    • Avoids unused packages entirely
    • Ensures deterministic builds

    Debian works well for development boards. Yocto works better for shipping products.

    Yocto vs Red Hat

    Red Hat focuses on:

    • Enterprise servers
    • Certified hardware
    • Subscription-based support
    • Long-term enterprise updates

    In yocto vs redhat, the difference is simple:

    • Red Hat is not designed for deeply embedded devices
    • Yocto is built specifically for embedded use cases

    Most embedded hardware vendors provide Yocto-based BSPs, not Red Hat images.

    Yocto vs Ubuntu Core

    Ubuntu Core is Canonical’s answer to embedded Linux.

    In yocto vs ubuntu core:

    • Ubuntu Core uses snap packages
    • Updates are transactional
    • It works well for IoT gateways

    But Ubuntu Core:

    • Still limits deep customization
    • Locks you into Canonical tooling
    • Is less flexible at low-level system design

    Yocto gives you:

    • Complete architectural freedom
    • No vendor lock-in
    • Full control over system behavior

    Customization: where Yocto wins clearly

    Customization is the biggest reason why Yocto is used rather than directly using a Linux OS.

    With Yocto, you control:

    • Kernel configuration
    • Device tree
    • Init system
    • Filesystem layout
    • Boot scripts
    • Package versions
    • Compiler flags

    This is done using:

    • Recipes
    • Layers
    • BitBake
    • BSPs
    • Images

    Nothing is hidden. Nothing is forced.

    With standard Linux distros, customization often means fighting defaults.

    Performance and footprint

    Embedded systems care deeply about:

    • Boot time
    • Memory usage
    • Storage footprint

    Ubuntu or Debian images often:

    • Include unused services
    • Include extra libraries
    • Consume more RAM
    • Increase attack surface

    Yocto images:

    • Include only what you need
    • Boot faster
    • Use less memory
    • Fit into small flash sizes

    This alone explains many yocto vs linux os decisions.

    Security and long-term maintenance

    Security is not just about patches. It’s about control.

    Yocto enables:

    • Known package versions
    • Controlled updates
    • CVE tracking
    • Rebuilding images with fixes
    • Long-term maintenance strategies

    Embedded products often live in the field for a decade. Yocto supports that reality better than rolling Linux distributions.

    Real-world use cases where Yocto dominates

    Automotive

    • Infotainment systems
    • Instrument clusters
    • ADAS platforms

    Automotive Linux almost always uses Yocto.

    Industrial devices

    • PLCs
    • HMIs
    • Control systems

    These systems demand stability and long lifecycles.

    Medical devices

    • Strict certification
    • Controlled software environments
    • Predictable updates

    IoT and edge devices

    • Gateways
    • Sensors
    • Smart controllers

    This is why Yocto is everywhere in production embedded Linux.

    Common beginner doubts and myths about Yocto

    “Yocto is too complex”

    Yes, there is a learning curve. But complexity exists because embedded systems are complex.

    “Yocto is slow”

    Initial builds are slow. Incremental builds are fast and reliable.

    “Yocto replaces Linux”

    No. Yocto builds Linux-based systems.

    “Yocto is only for experts”

    Beginners use Yocto every day. They just learn it step by step.

    When Yocto is NOT the right choice

    Yocto is powerful, but not always needed.

    Avoid Yocto if:

    • You are doing quick demos
    • Hardware is powerful
    • Product lifespan is short
    • You want fast experimentation

    In these cases, Ubuntu or Debian may be better.

    Advantages and disadvantages of Yocto (text table)

    Advantages

    • Full system customization
    • Minimal footprint
    • Reproducible builds
    • Long-term maintenance
    • Industry standard for embedded

    Disadvantages

    • Steep learning curve
    • Longer initial setup
    • Build time can be high
    • Requires discipline and structure

    Yocto Linux versions explained

    A common question is about yocto linux versions.

    Yocto releases:

    • Are named after characters
    • Follow predictable release cycles
    • Offer Long Term Support versions

    Yocto tracks kernel versions but does not lock you into one. You choose your kernel.

    Frequently Asked Questions

    Is Yocto a Linux distribution?

    No. Yocto builds Linux distributions.

    Is Yocto an operating system?

    No. The OS is what Yocto creates.

    Can Yocto replace Ubuntu?

    Yocto does not replace Ubuntu. It serves a different purpose.

    Do I need Yocto for embedded Linux?

    Not always. But for production systems, usually yes.

    Why do companies prefer Yocto?

    Control, stability, customization, and long-term support.

    Final conclusion: Why is Yocto used rather than directly using a Linux OS?

    So, let’s come back to the core question:

    Why is Yocto used rather than directly using a Linux OS?

    • Because embedded systems are not desktops.
    • Because products need control, not convenience.
    • Because long-term stability matters more than quick installs.
    • Because hardware-specific customization is non-negotiable.
    • Because reproducibility and maintainability define success.
    • Standard Linux distributions are excellent tools.
    • Yocto exists for when those tools are no longer enough.

    If you are building an embedded product that must run reliably for years, Yocto is not overkill. It is the right tool.

    That is why Yocto is used.

    Many engineers start understanding why Yocto is used rather than directly using a Linux OS when they face real interview scenarios. Going through practical Yocto interview questions for professionals helps connect theory with industry expectations.
    https://embeddedprep.com/yocto-interview-questions-for-professionals/

  • Master QNX Resource Managers for Beginners and Embedded Engineers (2026)

    Learn QNX Resource Managers step by step with real examples. Understand IPC, message passing, drivers, and how QNX services work in practice.

    Introduction of QNX Resource Managers

    If you are working with real-time systems, safety-critical software, or automotive platforms, you will eventually run into QNX. And when you do, one topic comes up again and again: Writing Device Drivers and Resource Managers in QNX.

    This is where many engineers get confused.

    Linux developers often expect kernel modules. Beginners expect something similar to microcontroller firmware. QNX does neither in the traditional way. Instead, QNX takes a very different approach that feels strange at first but makes a lot of sense once it clicks. If you are new to QNX, you will understand the basics without feeling overwhelmed.
    If you already have experience with embedded Linux or RTOS systems, you will understand why QNX does things differently and how to work with it confidently. We will cover device drivers, resource managers, QNX Neutrino IPC, and message passing step by step.

    By the end, Writing Device Drivers and Resource Managers in QNX will feel logical instead of mysterious.

    What Makes QNX Different from Linux Driver Models

    The biggest mental shift when moving to QNX is accepting that the kernel is not the center of everything.

    Microkernel philosophy

    Linux uses a monolithic kernel. Most drivers live inside the kernel space. If a driver crashes, the system usually goes down with it.

    QNX uses a microkernel. The kernel does very little:

    • Scheduling
    • Interrupt handling
    • Low-level IPC
    • Basic memory management

    Everything else runs in user space.

    Why drivers run in user space

    In QNX, most device drivers and all resource managers are user-space processes. This gives you:

    • Fault isolation
    • Easier debugging
    • Ability to restart drivers without rebooting
    • Better system stability

    If a QNX driver crashes, the kernel stays alive. You can restart the driver like a normal process.

    Real-world advantages

    This design is one of the main reasons QNX is used in:

    • Automotive infotainment
    • ADAS systems
    • Medical devices
    • Industrial controllers

    Safety certification becomes more realistic when one faulty component cannot crash the whole system.

    Understanding QNX Neutrino Architecture

    Before you write a single line of code, you must understand how QNX Neutrino is structured.

    Microkernel at the center

    The QNX Neutrino microkernel is tiny and deterministic. It does not know about filesystems, drivers, or networking. Those are all separate processes.

    Processes vs threads

    • Process: Has its own address space
    • Thread: Runs inside a process and shares memory

    Most QNX drivers are single processes with one or more threads.

    IPC fundamentals

    Everything in QNX talks through IPC. This is not optional. It is the backbone of the system.

    This is where QNX Neutrino IPC becomes critical. Instead of shared memory hacks or kernel callbacks, QNX relies on message passing.

    Once you understand IPC, device drivers and resource managers start to feel natural.

    What Is a QNX Device Driver

    A QNX device driver is a program that controls hardware and exposes it to user applications.

    Where drivers live

    Unlike Linux kernel modules:

    • QNX drivers are user-space processes
    • They can be started and stopped like normal programs
    • They often live under /dev

    QNX character driver explained

    Most beginners start with a QNX character driver. These drivers:

    • Handle byte streams
    • Look like files
    • Support open, read, write, close

    Examples:

    • UART drivers
    • I2C device access
    • Simple GPIO interfaces

    Driver vs resource manager

    This is important:

    • Device driver: Talks directly to hardware
    • Resource manager: Presents a file-like interface to applications

    Often, a driver is implemented as a resource manager. This is why beginners get confused. In QNX, these concepts overlap by design.

    Resource Managers Explained Like You’ve Never Heard Before

    Think of a resource manager as a translator.

    What they are

    A resource manager:

    • Registers a pathname like /dev/mydevice
    • Waits for client requests
    • Handles read, write, ioctl, open, close
    • Responds using IPC

    Why they exist

    QNX treats everything as a resource. Files, devices, services. A resource manager lets your service behave like a file.

    Applications do not care if they are talking to:

    • A real file
    • A hardware device
    • A software service

    Feels like files, acts like services

    This is the magic.

    You can open() a device, but behind the scenes, a message is sent to your process. You handle it in your own code.

    A simple QNX resource manager example could expose a temperature sensor as /dev/temp0. Applications just read it like a file.

    QNX Message Passing and IPC Deep Dive

    This section is the heart of QNX.

    Why message passing matters

    Everything depends on it:

    • Drivers
    • Resource managers
    • Filesystems
    • Networking

    Understanding QNX message passing is more important than memorizing APIs.

    Core IPC calls

    • MsgSend()
    • MsgReceive()
    • MsgReply()

    Flow:

    1. Client sends a message
    2. Server receives it
    3. Server replies
    4. Client unblocks

    This is synchronous and deterministic.

    Pulses

    Pulses are lightweight messages:

    • No reply needed
    • Used for events and notifications
    • Very fast

    Drivers use pulses for interrupts, timers, and signals.

    Why this model works

    • No shared memory races
    • Clear ownership
    • Predictable timing
    • Easier debugging

    Once you embrace this, QNX starts to feel clean and intentional.

    Step-by-Step: Writing a Simple QNX Character Driver

    This is a QNX device driver tutorial at a conceptual level. Enough to understand the flow without drowning in boilerplate.

    High-level flow

    1. Initialize hardware
    2. Create a dispatch structure
    3. Attach a resource manager
    4. Enter dispatch loop
    5. Handle read and write requests

    Key structures

    • dispatch_t
    • resmgr_attr_t
    • resmgr_connect_funcs_t
    • resmgr_io_funcs_t

    These structures tell QNX how to route messages to your code.

    Data flow explained simply

    • User app calls read()
    • Kernel converts it to a message
    • Message arrives at your driver
    • Your io_read() function runs
    • You copy data to client buffer
    • Reply is sent automatically

    No kernel hacking. No syscall tables.

    Step-by-Step: Writing a Simple Resource Manager

    A resource manager is often easier than a full driver.

    Dispatch loop

    The dispatch loop waits for messages and routes them:

    dispatch_block()
    dispatch_handler()
    

    resmgr_attach

    This registers your path:

    • /dev/myresource
    • Sets permissions
    • Connects handlers

    io_read and io_write

    These functions do the real work:

    • Validate request
    • Copy data
    • Update offsets

    This model scales from simple demos to production systems.

    User Application Interaction

    From the application side, everything looks familiar.

    File I/O model

    Applications use:

    • open()
    • read()
    • write()
    • ioctl()

    They do not need to know about IPC.

    Message passing directly

    Advanced apps can use:

    • MsgSend()
    • Pulses
    • Shared memory

    This is useful for high-performance or control-heavy systems.

    Real example

    An automotive audio service may:

    • Use file I/O for control
    • Use message passing for real-time events
    • Use shared memory for audio buffers

    QNX lets you mix models cleanly.

    Debugging Tips for QNX Drivers and Resource Managers

    Debugging is easier than Linux if you know how to think.

    Common mistakes

    • Forgetting to reply to messages
    • Blocking inside handlers
    • Incorrect permissions
    • Bad offset handling

    Debugging mindset

    Think in terms of messages, not function calls.

    Ask:

    • Who sent this message?
    • Why is the client blocked?
    • Did I reply correctly?

    Useful tools

    • slog2
    • pidin
    • on -f
    • gdb

    Logs and process inspection go a long way.

    Performance, Safety, and Reliability Considerations

    This is why QNX exists.

    Automotive focus

    QNX dominates automotive because:

    • Fault isolation is real
    • Determinism is predictable
    • Certification is practical

    Fault containment

    If your driver crashes:

    • Kernel survives
    • Other services survive
    • System can recover

    Real-time behavior

    Message passing is deterministic. No hidden kernel locks. This matters for safety systems.

    Common Beginner Mistakes

    • Treating QNX like Linux
    • Ignoring IPC fundamentals
    • Blocking inside resource manager callbacks
    • Overusing shared memory
    • Forgetting permission settings
    • Not handling offsets correctly
    • Mixing driver logic with application logic

    Real-World Use Cases

    Automotive

    • Audio routing services
    • CAN and Ethernet gateways
    • Sensor abstraction layers

    Medical

    • Patient monitoring devices
    • Imaging systems
    • Safety-certified controllers

    Industrial

    • PLC communication
    • Fieldbus interfaces
    • Motion control systems

    Frequently Asked Questions of QNX Resource Managers

    What is the difference between a device driver and a resource manager in QNX?

    A driver controls hardware. A resource manager exposes services using a file-like interface. Many drivers are implemented as resource managers.

    Is kernel programming required in QNX?

    No. Most drivers run in user space.

    Why does QNX use message passing instead of shared memory?

    Message passing is deterministic, safe, and easier to reason about in real-time systems.

    Can Linux developers learn QNX easily?

    Yes, but they must unlearn kernel-centric thinking.

    What is QNX Neutrino IPC used for?

    All communication between processes, including drivers and applications.

    Are QNX character drivers similar to Linux character drivers?

    Conceptually yes, but implementation is completely different.

    Can I restart a crashed driver without rebooting?

    Yes. This is a core advantage of QNX.

    How are interrupts handled?

    Interrupts are delivered as pulses or messages to user-space drivers.

    Is QNX suitable for high-performance systems?

    Yes. Many production automotive systems use it today.

    How do applications talk to resource managers?

    Using standard POSIX file I/O or direct message passing.

    Is QNX harder than Linux?

    Different, not harder. Once IPC clicks, it feels simpler.

    Do I need to write resource managers for everything?

    No. Only when you want a file-like interface.

    Conclusion

    Writing Device Drivers and Resource Managers in QNX is not about learning obscure APIs. It is about understanding a philosophy.

    QNX is built around isolation, message passing, and clarity. Drivers are not special kernel magic. They are well-behaved user processes that communicate through clean IPC.

    Once you understand QNX Neutrino IPC, message passing, and the role of resource managers, the system becomes predictable and powerful.

    If you are serious about automotive, safety-critical, or real-time systems, mastering Writing Device Drivers and Resource Managers in QNX is one of the most valuable skills you can develop.

    Practice small examples. Read the messages. Think in terms of services, not kernels. That is how real QNX systems are built.

    Recommended Resource: Expand Your ESP32 Knowledge

    If you’re enjoying this project and want to explore more powerful sensor integrations, make sure to check out my detailed guide on using the ESP32 with the DS18B20 temperature sensor. It’s a beginner-friendly, real-world tutorial that shows how to measure temperature with high accuracy and integrate the data into IoT dashboards, automation systems, or cloud servers. You can read the full step-by-step guide here: ESP with DS18b20

    This resource pairs perfectly with your ESP32 with RFID setup—together, you can build advanced smart home systems, environmental monitoring tools, or complete multi-sensor IoT projects.

  • Top 7 FreeRTOS Bugs That Crash Devices After 2–3 Days of Runtime

    FreeRTOS Bugs often cause devices to crash after days of uptime due to task, queue, interrupt, and memory issues. Learn real causes and proven fixes.

    FreeRTOS systems often run perfectly for hours or even days before suddenly crashing, hanging, or resetting without warning. These failures are rarely caused by obvious bugs. Instead, they come from subtle FreeRTOS issues that only appear after long runtime, real workloads, and unpredictable timing between tasks, interrupts, and memory.

    In this deep-dive article, a senior embedded systems engineer with over 10 years of real-world FreeRTOS debugging experience breaks down the top 7 FreeRTOS bugs that crash devices after 2–3 days of runtime. This is not a beginner tutorial or academic theory. Every bug discussed here is based on real production failures seen in automotive, industrial, and IoT devices.

    You will learn why common FreeRTOS bugs stay hidden during testing, how scheduling and heap behavior change over time, and why interrupt timing and task interaction are the real culprits behind long-runtime crashes. The article explains stack overflows that do not crash immediately, queue misuse involving QueueHandle_t, busy wait loops that slowly starve the scheduler, incorrect interrupt priorities, memory corruption caused by missing memory barriers, event group misuse, and CAN bus deadlocks under load.

    Each bug includes a real-world scenario, why it passes initial testing, the exact failure mechanism, how it leads to a hard fault, hang, or watchdog reset, and how both beginners and experienced developers accidentally introduce it. You will also learn practical detection techniques using FreeRTOS backtrace analysis, coredumps, GDB, Segger Embedded Studio, tracing tools, and debugger workflows that actually work in production environments.

    This article is written for real developers who debug real systems. If you are dealing with unexplained FreeRTOS crashes, long-term stability issues, or devices that fail only after days of uptime, this guide will help you recognize the patterns, confirm the root cause, and fix the problem correctly without guesswork.

    Introduction

    If you have worked with FreeRTOS long enough, you have seen this pattern.

    The device boots fine.
    Runs all tests.
    Survives stress testing.
    Customer deploys it.
    Two or three days later, it locks up, resets, or goes silent.

    Logs show nothing useful.
    Watchdog resets keep happening.
    Reboot fixes it… temporarily.

    These are not beginner mistakes like forgetting to start the scheduler. These are long-runtime FreeRTOS bugs, and they are brutal to debug.

    Why?

    Because:

    • They depend on timing
    • They depend on task interaction
    • They depend on memory behavior over time
    • They almost never show up in short tests

    I have debugged these issues on industrial controllers, automotive gateways, medical devices, and IoT hardware. The same patterns keep repeating.

    This article is for:

    • Beginners who want to avoid future pain
    • Intermediate devs stuck chasing random resets
    • Experienced engineers who want a clean freertos bug list they can cross-check against their system

    Everything here comes from real debugging sessions, real post-mortems, and real devices sitting on my desk at 3 AM.

    Why Long-Runtime Bugs Are Different in FreeRTOS

    Scheduling hides problems

    FreeRTOS is extremely forgiving at first.

    Tasks run.
    Queues pass data.
    Events fire.
    Interrupts work.

    But scheduling creates time-based behavior, not immediate behavior. A task might run fine for 10,000 iterations before it finally collides with another task at just the wrong moment.

    Heap behavior changes over time

    Even if you never call pvPortMalloc() after startup, fragmentation can still happen indirectly.

    Message buffers.
    Timers.
    Deferred interrupts.
    Drivers doing hidden allocations.

    Heap corruption rarely crashes immediately. It poisons memory slowly until something important gets overwritten.

    Interrupt timing is never stable

    What worked at low traffic fails under real load.

    CAN bursts.
    Button spam.
    GPIO storms.
    DDS or sensor interrupts firing faster than expected.

    That is why debugging FreeRTOS issues always requires thinking in timelines, not just code paths.

    Top 7 FreeRTOS Bugs That Crash Devices After 2–3 Days

    🐞 Bug #1: Stack Overflow That Does Not Crash Immediately

    Real-world scenario

    A task handles protocol parsing. It has a local buffer, some structs, maybe a JSON decode. Everything works.

    After two days, device resets with a freertos hardfault.

    Why it passes initial testing

    • Stack usage is almost enough
    • Typical test messages are smaller
    • Worst-case path is rare

    FreeRTOS does not magically know your worst execution path.

    Failure mechanism

    Stack grows slowly over time.
    Eventually it overwrites:

    • Task control block
    • Queue structures
    • Event group memory

    Now the scheduler trips over corrupted data.

    Result

    • Random reset
    • Silent hang
    • Hard fault inside the kernel

    When you finally capture it, the freertos backtrace looks meaningless.

    Beginner mistake

    Assuming default stack sizes are fine.

    Experienced mistake

    Adding “just a bit more stack” without measuring.

    How to detect it

    • Enable stack overflow checking
    • Use uxTaskGetStackHighWaterMark
    • Inspect task stacks in freertos gdb or freertos segger embedded studio

    If you ever use freertos+trace, stack usage spikes become obvious.

    How to fix it

    • Measure worst-case stack usage
    • Avoid large local arrays
    • Move buffers to static memory

    This alone eliminates a shocking number of freertos bugs.

    🐞 Bug #2: Queue Misuse with QueueHandle_t

    Real-world scenario

    You use queues everywhere. Sensor task pushes data. Processing task pulls it. Clean design.

    Two days later, tasks stop responding.

    Why it passes initial testing

    Queues hide errors extremely well.

    Sending to a deleted queue.
    Using a stale freertos queuehandle_t.
    Sending from ISR without the ISR-safe API.

    All of these may work… until timing shifts.

    Failure mechanism

    Queue internal structures get corrupted.
    Eventually scheduler walks invalid memory.
    Boom.

    Result

    • Deadlock
    • Kernel assert
    • Hard fault

    Often shows up as corrupted lists during debugging FreeRTOS.

    Beginner mistake

    Not checking return values from xQueueSend.

    Experienced mistake

    Passing queue handles across modules with no ownership rules.

    How to detect it

    • Enable asserts
    • Validate queue handles
    • Capture freertos coredump and inspect queue internals

    How to fix it

    • One owner per queue
    • Clear lifecycle rules
    • Use ISR APIs correctly

    Queues are powerful, but they are not magic.

    🐞 Bug #3: Busy Wait Instead of Proper Blocking

    Real-world scenario

    A task waits for hardware.

    So someone writes:

    while(!flag) {}
    

    Classic freertos busy wait.

    Why it passes initial testing

    CPU is fast.
    Load is low.
    It “works”.

    Failure mechanism

    Busy wait:

    • Starves lower priority tasks
    • Prevents idle task from running
    • Blocks memory cleanup
    • Delays timers

    Over days, timing drift builds up.

    Result

    • Watchdog resets
    • Tasks never unblock
    • System slowly degrades

    Beginner mistake

    Not understanding freertos blocking APIs.

    Experienced mistake

    Using busy wait to “optimize latency”.

    How to detect it

    • CPU usage stuck near 100%
    • Idle task not running
    • Trace shows starvation

    How to fix it

    Use:

    • vTaskDelay
    • xQueueReceive
    • freertos wait for event

    FreeRTOS is event-driven. Fight that and it fights back.

    🐞 Bug #4: Incorrect Interrupt Priorities

    Real-world scenario

    GPIO interrupt fires on button press. CAN interrupt fires on bus traffic. Everything works.

    After heavy load, system crashes.

    Why it passes initial testing

    Interrupt timing is light.
    No nesting issues.

    Failure mechanism

    Wrong priority interrupts calling FreeRTOS APIs.

    This violates kernel rules and corrupts internal state.

    Result

    • Scheduler corruption
    • Random asserts
    • freertos hardfault

    Often blamed on hardware.

    Beginner mistake

    Ignoring priority rules in interrupts FreeRTOS.

    Experienced mistake

    Porting code from another RTOS without rechecking priorities.

    How to detect it

    • Audit ISR priorities
    • Check which ISRs call RTOS APIs
    • Debug with freertos debugger

    How to fix it

    • Follow max syscall interrupt priority rules
    • Separate pure hardware ISRs from RTOS-aware ISRs

    This bug alone explains many “it crashes only under load” cases.

    🐞 Bug #5: Missing Memory Barriers

    Real-world scenario

    Shared data between ISR and task. Flags look correct. Logic is sound.

    Still fails.

    Why it passes initial testing

    Compiler optimizations are minimal.
    Timing is lucky.

    Failure mechanism

    Without a freertos memory barrier, compiler or CPU reorders memory access.

    Task sees stale data.
    ISR thinks task handled it.

    Result

    • Missed events
    • Deadlocks
    • Random behavior

    Very hard to reproduce.

    Beginner mistake

    Not understanding memory ordering.

    Experienced mistake

    Assuming volatile is enough.

    How to detect it

    • Review shared variables
    • Look for lock-free code
    • Inspect assembly in freertos gdb

    How to fix it

    • Use FreeRTOS synchronization primitives
    • Insert memory barriers where required
    • Avoid lock-free sharing unless necessary

    This is one of the sneakiest freertos bugs.

    🐞 Bug #6: Event Group Misuse

    Real-world scenario

    Multiple tasks wait on events. Button interrupt sets a flag. Processing task waits.

    Using freertos events everywhere feels elegant.

    Why it passes initial testing

    Low contention.
    Clear logic.

    Failure mechanism

    • Event bits cleared too early
    • Tasks waiting incorrectly with freertos wait for event
    • Missed signals

    Eventually tasks block forever.

    Result

    • Silent hang
    • System appears alive but does nothing

    Beginner mistake

    Using events like queues.

    Experienced mistake

    Over-clever event bit combinations.

    How to detect it

    • Log event transitions
    • Use trace tools
    • Inspect blocked task lists

    How to fix it

    • Use events only for signaling
    • Use queues for data
    • Keep event logic simple

    🐞 Bug #7: CAN Bus Deadlocks

    Real-world scenario

    CAN RX interrupt pushes frames. Processing task sends responses.

    Works fine until bus traffic spikes.

    Why it passes initial testing

    Test traffic is clean.
    No overload.

    Failure mechanism

    • RX ISR blocks indirectly
    • TX queue fills
    • Tasks wait on each other

    Classic freertos can bus deadlock.

    Result

    • Bus silence
    • Tasks blocked forever
    • Watchdog reset

    Beginner mistake

    Doing too much inside CAN ISR.

    Experienced mistake

    Ignoring backpressure handling.

    How to detect it

    • Monitor queue depth
    • Log ISR execution time
    • Inspect blocked tasks

    How to fix it

    • Minimal ISR work
    • Dedicated CAN worker task
    • Proper flow control

    Final Thoughts

    If you are chasing a crash that happens after days, it is not random.

    It is almost always:

    • Stack
    • Queues
    • Interrupts
    • Blocking
    • Memory ordering
    • Events
    • Bus contention

    Every single item in this freertos bug list has caused real devices to fail in the field.

    If you take one thing from this article, let it be this:

    FreeRTOS does exactly what you tell it to do.
    Even when that destroys your system slowly.

    Debug patiently.
    Trace behavior over time.
    Trust evidence, not assumptions.

    And next time someone suggests a freertos bug bounty, you will know exactly where to look first.

    FAQ on FreeRTOS Bugs

    1. Why do FreeRTOS devices crash after 2–3 days of runtime?

    Most long-runtime crashes are caused by hidden FreeRTOS Bugs such as slow stack overflows, queue misuse, interrupt priority mistakes, or memory corruption that only appears after repeated task execution and timing drift.

    2. What are the most common FreeRTOS Bugs in production systems?

    The most common FreeRTOS Bugs include task stack overflows, incorrect QueueHandle_t usage, busy wait loops instead of proper blocking, wrong interrupt priorities, event group misuse, and CAN bus deadlocks under load.

    3. How can a stack overflow crash a FreeRTOS system without an immediate fault?

    In FreeRTOS, a stack overflow often overwrites nearby kernel data instead of crashing instantly. The system keeps running until the scheduler or queue logic touches corrupted memory, leading to a delayed hard fault or reset.

    4. How do I detect FreeRTOS Bugs that only happen after long uptime?

    Enable stack overflow checks, use runtime stats, capture coredumps, and analyze task states with a FreeRTOS debugger. Long-runtime bugs usually require observing behavior over time, not just single execution paths.

    5. Why is busy wait dangerous in FreeRTOS?

    Busy wait loops prevent the scheduler and idle task from running properly. Over time, this starves lower-priority tasks, delays timers, increases CPU load, and eventually causes system instability or watchdog resets.

    6. What happens if interrupt priorities are wrong in FreeRTOS?

    If interrupts call FreeRTOS APIs from invalid priority levels, the kernel’s internal data structures can become corrupted. This often leads to random crashes, asserts, or hard faults that are very difficult to reproduce.

    7. Can QueueHandle_t misuse really crash a FreeRTOS system?

    Yes. Using invalid or stale QueueHandle_t values, sending to deleted queues, or using non-ISR-safe APIs inside interrupts can corrupt queue memory and eventually crash the scheduler.

    8. How do FreeRTOS event groups cause deadlocks?

    Event groups can cause deadlocks when bits are cleared too early, multiple tasks wait on the same event incorrectly, or events are used to pass data instead of just signals. This leads to tasks blocking forever.

    9. Why do CAN bus issues appear after days in FreeRTOS systems?

    Under heavy traffic, CAN receive interrupts, transmit queues, and processing tasks can block each other. Without proper flow control, FreeRTOS CAN bus handling can deadlock and silently stop communication.

    10. What tools are best for debugging FreeRTOS Bugs?

    GDB, Segger Embedded Studio, FreeRTOS trace tools, and coredump analysis are the most effective. These tools help inspect task states, backtraces, stack usage, and scheduler behavior over long runtimes.

    11. Are FreeRTOS memory barriers really necessary?

    Yes. Missing memory barriers can cause the compiler or CPU to reorder memory access between tasks and interrupts. This leads to subtle, timing-dependent bugs that appear only under real workloads.

    12. Why do FreeRTOS Bugs pass testing but fail in the field?

    Lab tests rarely reproduce real timing, interrupt frequency, bus load, or long-term memory behavior. FreeRTOS Bugs often depend on rare timing windows that only occur in real deployments.

    13. Can FreeRTOS coredumps help with long-runtime crashes?

    Absolutely. A FreeRTOS coredump allows you to inspect task stacks, queue states, and scheduler data at the moment of failure, which is critical for diagnosing crashes that happen after days.

    Recommended Resource: Expand Your ESP32 Knowledge

    If you’re enjoying this project and want to explore more powerful sensor integrations, make sure to check out my detailed guide on using the ESP32 with the DS18B20 temperature sensor. It’s a beginner-friendly, real-world tutorial that shows how to measure temperature with high accuracy and integrate the data into IoT dashboards, automation systems, or cloud servers. You can read the full step-by-step guide here: ESP with DS18b20

    This resource pairs perfectly with your ESP32 with RFID setup—together, you can build advanced smart home systems, environmental monitoring tools, or complete multi-sensor IoT projects.

  • Zephyr vs FreeRTOS: Master Beginner to Advanced Tutorial (2026)

    Zephyr vs FreeRTOS explained clearly for beginners to pros. Compare performance, STM32, ESP32, IoT use cases, and real code differences.

    If you’re working with microcontrollers and real-time systems, sooner or later you’ll face the Zephyr vs FreeRTOS question. It comes up whether you’re blinking LEDs on an STM32, building an ESP32-based IoT device, or designing something more serious like an industrial controller. Both Zephyr OS and FreeRTOS are excellent real-time operating systems, but they solve problems in very different ways.

    FreeRTOS is often the first RTOS engineers learn. It’s small, fast, and easy to understand. You create tasks, use queues and semaphores, and you’re productive quickly. That’s why it’s so popular on platforms like STM32 and ESP32. In many STM32 Zephyr vs FreeRTOS discussions, FreeRTOS wins for simple projects because of its low memory usage and minimal setup. If you want full control and don’t mind managing configuration yourself, FreeRTOS feels comfortable and predictable.

    Zephyr OS takes a more structured approach. Instead of giving you just a kernel, it provides a full embedded operating system with drivers, networking, security features, and a modern build system. When people talk about Zephyr OS vs FreeRTOS, they’re usually comparing simplicity with scalability. Zephyr has a steeper learning curve, but once you understand its device tree, Kconfig system, and modular design, it becomes much easier to manage large and long-term projects.

    Performance is another common concern. In real benchmarks, Zephyr vs FreeRTOS performance differences are usually small. FreeRTOS has slightly lower overhead, while Zephyr trades a bit of raw speed for cleaner architecture and portability. On boards like ESP32, the ESP32 Zephyr vs FreeRTOS choice often depends more on ecosystem and tooling than speed.

    When compared with other RTOS options like ThreadX vs FreeRTOS vs Zephyr, NuttX vs FreeRTOS vs Zephyr, or even Azure RTOS vs FreeRTOS vs Zephyr, the pattern stays the same. FreeRTOS is lean and beginner-friendly. Zephyr is modern, scalable, and better suited for complex IoT systems. Compared to Zephyr vs Embedded Linux, Zephyr clearly targets microcontrollers where real-time behavior and low resource usage matter.

    In short, FreeRTOS is ideal for learning and lightweight products, while Zephyr is a strong choice for future-proof, production-grade embedded systems.

    If you work with microcontrollers long enough, one question always comes up:

    Should I use Zephyr or FreeRTOS?

    And the truth is, there’s no single right answer. But there is a right answer for your use case.

    In this in-depth Zephyr vs FreeRTOS tutorial, we’ll break everything down step by step:

    • What each RTOS actually is
    • How they differ in real projects
    • Performance, memory, and hardware support
    • STM32, ESP32, and real-world comparisons
    • How Zephyr compares with ThreadX, NuttX, Azure RTOS, and even Embedded Linux

    By the end, you’ll know exactly which RTOS fits your goals.

    What Is an RTOS (Quick Refresher)

    An RTOS, or Real-Time Operating System, helps your embedded system:

    • Run multiple tasks
    • Meet timing deadlines
    • Handle interrupts cleanly
    • Scale beyond a simple while(1) loop

    If you’re blinking LEDs, bare metal is fine.
    If you’re building IoT devices, automotive ECUs, industrial controllers, or connected products, an RTOS becomes essential.

    What Is FreeRTOS?

    FreeRTOS is the most widely used RTOS in the world.

    It’s:

    • Lightweight
    • Simple
    • Easy to learn
    • Extremely well documented

    FreeRTOS was designed with one core idea:

    Give developers just enough OS, without getting in the way.

    Key Characteristics of FreeRTOS

    • Small memory footprint
    • Manual configuration using header files
    • Simple task, queue, semaphore model
    • Runs almost anywhere

    This is why FreeRTOS dominates beginner projects and commercial products alike.

    What Is Zephyr OS?

    Zephyr OS is newer, more ambitious, and more structured.

    Think of Zephyr not as “just an RTOS”, but as:

    A full embedded operating system with modern tooling.

    Zephyr was created for scalable, secure, connected devices.

    Key Characteristics of Zephyr OS

    • Modular kernel
    • Device tree-based hardware description
    • Built-in networking stacks
    • Strong security model
    • Excellent multi-board support

    When people say Zephyr OS vs FreeRTOS, they’re often comparing simplicity vs structure.

    Zephyr RTOS vs FreeRTOS: Core Philosophy

    This is the most important difference.

    FreeRTOS Philosophy

    • You control everything
    • Minimal abstraction
    • Easy to break things if you’re careless
    • Perfect for small teams and simple products

    Zephyr OS Philosophy

    • Strong defaults
    • Clear separation of hardware and software
    • Harder to misuse
    • Designed for large, long-term projects

    This single difference affects learning curve, debugging, and scalability.

    Zephyr vs FreeRTOS Performance

    Let’s talk about performance, because this question comes up constantly.

    Raw Performance

    • FreeRTOS has very low context switch overhead
    • Zephyr has slightly more overhead due to abstraction layers

    In most real-world projects:

    You will not notice a performance difference.

    Deterministic Behavior

    • FreeRTOS is extremely deterministic
    • Zephyr is also deterministic but depends more on configuration

    If you are building hard real-time systems, both are capable when configured correctly.

    Memory Footprint Comparison

    This is where FreeRTOS shines.

    FreeRTOS Memory Usage

    • Kernel can be under 10 KB
    • You include only what you need
    • Perfect for low-RAM MCUs

    Zephyr Memory Usage

    • Larger baseline footprint
    • Kernel + drivers + subsystems add up
    • Better suited for MCUs with more Flash and RAM

    If memory is extremely tight, FreeRTOS usually wins.

    STM32: Zephyr vs FreeRTOS

    The STM32 Zephyr vs FreeRTOS debate is very common.

    STM32 with FreeRTOS

    • Excellent CubeMX integration
    • Huge community support
    • Very fast to get running
    • Ideal for beginners

    STM32 with Zephyr

    • Cleaner hardware abstraction
    • Easier board portability
    • More structured project layout

    If you’re learning embedded systems:

    • Start with FreeRTOS on STM32
    • Move to Zephyr when projects grow

    ESP32: Zephyr vs FreeRTOS

    ESP32 deserves special attention.

    ESP32 and FreeRTOS

    • ESP-IDF is built on FreeRTOS
    • Rock-solid support
    • Massive ecosystem

    ESP32 Zephyr vs FreeRTOS

    • Zephyr supports ESP32 well
    • Better portability across vendors
    • Slightly steeper learning curve

    For ESP32:

    FreeRTOS is still the easiest path, but Zephyr is catching up fast.

    Zephyr OS vs FreeRTOS for IoT

    This is where Zephyr really starts to shine.

    FreeRTOS for IoT

    • Requires extra libraries
    • Networking is add-on based
    • AWS integration via FreeRTOS libraries

    Zephyr for IoT

    • Built-in networking stacks
    • Native Bluetooth, Thread, and IPv6
    • Designed for connected devices

    For modern IoT products:

    Zephyr OS vs FreeRTOS is less about speed and more about architecture.

    Zephyr vs Embedded Linux

    This is a very important comparison.

    Zephyr

    • Runs on microcontrollers
    • No MMU required
    • Real-time by design

    Embedded Linux

    • Requires MPU or MMU
    • Huge memory footprint
    • Not hard real-time by default

    Use Zephyr instead of Embedded Linux when:

    • Boot time matters
    • Memory is limited
    • Determinism is required

    Zephyr vs FreeRTOS vs Mbed

    Mbed OS used to be popular, but it’s fading.

    • FreeRTOS is simpler and more mature
    • Zephyr is more future-proof
    • Mbed is no longer actively growing

    In most cases today:

    Choose FreeRTOS or Zephyr, not Mbed.

    ThreadX vs FreeRTOS vs Zephyr

    Let’s compare all three.

    ThreadX

    • Very fast
    • Commercial roots
    • Now part of Azure RTOS

    FreeRTOS

    • Open source
    • Massive community
    • Easy to learn

    Zephyr

    • Modern architecture
    • Strong ecosystem
    • Long-term scalability

    If licensing and ecosystem matter:

    • FreeRTOS and Zephyr win

    Azure RTOS vs FreeRTOS vs Zephyr

    Azure RTOS is powerful but enterprise-focused.

    • Azure RTOS is excellent for Microsoft ecosystems
    • FreeRTOS has broader adoption
    • Zephyr is more vendor-neutral

    Most independent developers prefer FreeRTOS or Zephyr.

    NuttX vs FreeRTOS vs Zephyr

    NuttX sits somewhere between Zephyr and Linux.

    • POSIX-like APIs
    • Steeper learning curve
    • Less beginner-friendly

    For most users:

    FreeRTOS for simplicity, Zephyr for structure

    SafeRTOS vs FreeRTOS

    This one matters in safety-critical systems.

    • SafeRTOS is certified
    • FreeRTOS is not certified by default
    • Zephyr is working toward certifications

    If you’re in automotive or aerospace:

    • Certification matters more than popularity

    Zephyr vs FreeRTOS Reddit Opinions

    If you browse Zephyr vs FreeRTOS Reddit threads, you’ll notice a pattern:

    • Beginners love FreeRTOS
    • Experienced teams appreciate Zephyr
    • Nobody says one is “bad”

    That’s usually a good sign.

    Zephyr FreeRTOS Comparison Table (Conceptual)

    Instead of a boring table, here’s the takeaway:

    • Want fast results? FreeRTOS
    • Want clean architecture? Zephyr
    • Want tiny footprint? FreeRTOS
    • Want scalable IoT? Zephyr

    Learning Curve: Which Is Easier?

    FreeRTOS

    • Easier for beginners
    • Straightforward APIs
    • Less tooling complexity

    Zephyr

    • More concepts upfront
    • Better habits long-term
    • Strong build system (CMake + west)

    If you’re new:

    Start with FreeRTOS, then graduate to Zephyr.

    Real-World Project Suitability

    Choose FreeRTOS if:

    • You’re working on STM32 or ESP32
    • Memory is limited
    • You want quick results
    • You’re learning RTOS concepts

    Choose Zephyr if:

    • Your project will grow
    • You want hardware portability
    • You need networking and security
    • You’re building production-grade IoT

    Final Verdict: Zephyr vs FreeRTOS

    Here’s the honest truth:

    FreeRTOS is the best RTOS to learn first.
    Zephyr is the best RTOS to grow into.

    They are not enemies. They are tools for different stages of your journey.

    If you master both:

    You become extremely valuable as an embedded engineer.

    Zephyr vs FreeRTOS: Code Wise Comparison (Real Examples)

    Let’s compare how the same basic RTOS tasks are written in FreeRTOS and Zephyr OS.

    We’ll cover:

    1. Task / thread creation
    2. Delay and timing
    3. Inter-task communication (queue/message queue)
    4. Synchronization (mutex)
    5. Hardware access (GPIO example)

    1. Task vs Thread Creation

    FreeRTOS Code

    #include "FreeRTOS.h"
    #include "task.h"
    
    void led_task(void *param)
    {
        while (1)
        {
            // Do something
            vTaskDelay(pdMS_TO_TICKS(1000));
        }
    }
    
    int main(void)
    {
        xTaskCreate(
            led_task,
            "LED_Task",
            256,
            NULL,
            2,
            NULL
        );
    
        vTaskStartScheduler();
    
        while (1);
    }
    

    Zephyr Code

    #include <zephyr/kernel.h>
    
    void led_thread(void)
    {
        while (1)
        {
            // Do something
            k_sleep(K_SECONDS(1));
        }
    }
    
    K_THREAD_DEFINE(
        led_tid,
        1024,
        led_thread,
        NULL, NULL, NULL,
        2,
        0,
        0
    );
    

    Key Difference

    • FreeRTOS creates tasks at runtime
    • Zephyr defines threads at compile time
    • Zephyr encourages static system design
    • FreeRTOS is more flexible but easier to misuse

    2. Delay and Timing

    FreeRTOS

    vTaskDelay(pdMS_TO_TICKS(500));
    

    Zephyr

    k_sleep(K_MSEC(500));
    

    Insight

    • Zephyr time macros are more readable
    • FreeRTOS requires manual tick conversion
    • Both are equally accurate

    3. Queue vs Message Queue

    FreeRTOS Queue Example

    QueueHandle_t queue;
    
    queue = xQueueCreate(5, sizeof(int));
    
    int value = 10;
    xQueueSend(queue, &value, portMAX_DELAY);
    
    xQueueReceive(queue, &value, portMAX_DELAY);
    

    Zephyr Message Queue

    K_MSGQ_DEFINE(my_msgq, sizeof(int), 5, 4);
    
    int value = 10;
    k_msgq_put(&my_msgq, &value, K_FOREVER);
    
    k_msgq_get(&my_msgq, &value, K_FOREVER);
    

    Key Difference

    • FreeRTOS queues are dynamic
    • Zephyr message queues are static
    • Zephyr avoids heap usage by design

    4. Mutex / Synchronization

    FreeRTOS Mutex

    SemaphoreHandle_t mutex;
    
    mutex = xSemaphoreCreateMutex();
    
    xSemaphoreTake(mutex, portMAX_DELAY);
    // Critical section
    xSemaphoreGive(mutex);
    

    Zephyr Mutex

    struct k_mutex my_mutex;
    
    k_mutex_init(&my_mutex);
    
    k_mutex_lock(&my_mutex, K_FOREVER);
    // Critical section
    k_mutex_unlock(&my_mutex);
    

    Insight

    • Zephyr mutexes are simple structs
    • FreeRTOS uses handles and dynamic memory
    • Zephyr code is more explicit and predictable

    5. GPIO Example (LED Toggle)

    FreeRTOS (STM32 / ESP32 style)

    while (1)
    {
        HAL_GPIO_TogglePin(GPIOA, GPIO_PIN_5);
        vTaskDelay(pdMS_TO_TICKS(1000));
    }
    

    Zephyr GPIO (Device Tree Based)

    #include <zephyr/drivers/gpio.h>
    
    #define LED_NODE DT_ALIAS(led0)
    
    static const struct gpio_dt_spec led =
        GPIO_DT_SPEC_GET(LED_NODE, gpios);
    
    void main(void)
    {
        gpio_pin_configure_dt(&led, GPIO_OUTPUT_ACTIVE);
    
        while (1)
        {
            gpio_pin_toggle_dt(&led);
            k_sleep(K_SECONDS(1));
        }
    }
    

    Key Difference

    • FreeRTOS depends on vendor HAL
    • Zephyr uses device tree for portability
    • Same code works across multiple boards

    Code Philosophy Summary

    AspectFreeRTOSZephyr
    MemoryDynamicMostly static
    StyleSimple C APIsStructured OS APIs
    HardwareVendor HALDevice Tree
    SafetyDeveloper responsibilitySafer defaults
    ScalingManualBuilt-in

    When Code Feels Better in Each RTOS

    FreeRTOS Code Feels Better When:

    • Writing small applications
    • Rapid prototyping
    • Learning RTOS basics
    • Working directly with HAL

    Zephyr Code Feels Better When:

    • Building large projects
    • Supporting many boards
    • Writing clean, reusable drivers
    • Working on IoT products

    Key Takeaways

    • Zephyr RTOS vs FreeRTOS is about structure vs simplicity
    • Performance differences rarely matter in practice
    • STM32 and ESP32 work great with both
    • Zephyr competes well with ThreadX, NuttX, and Azure RTOS
    • Embedded Linux is a different class altogether

    FAQ of Zephyr vs FreeRTOS

    1. What is the main difference between Zephyr and FreeRTOS?

    The main difference in Zephyr vs FreeRTOS is philosophy. FreeRTOS is a lightweight real-time kernel that gives you full control with minimal abstraction. Zephyr OS is a complete embedded operating system with a kernel, device drivers, networking stacks, and security features built in. FreeRTOS focuses on simplicity and speed, while Zephyr focuses on structure, scalability, and long-term maintainability.

    2. Which is better for beginners: Zephyr or FreeRTOS?

    For beginners, FreeRTOS is usually easier to start with. You can understand tasks, queues, and semaphores quickly and see results fast. Zephyr has a steeper learning curve because of concepts like device tree, Kconfig, and its build system. That said, once you understand Zephyr, it often feels cleaner and more organized for larger projects.

    3. Is Zephyr faster than FreeRTOS?

    In most real applications, Zephyr vs FreeRTOS performance differences are small. FreeRTOS has slightly lower overhead and faster context switching in very constrained systems. Zephyr trades a bit of raw performance for better abstraction and portability. For STM32 and ESP32 projects, performance is rarely the deciding factor.

    4. Should I use Zephyr or FreeRTOS on STM32?

    In STM32 Zephyr vs FreeRTOS, both work very well. FreeRTOS integrates smoothly with STM32CubeMX and is ideal for quick development. Zephyr provides cleaner hardware abstraction and easier board portability. For learning and small products, FreeRTOS is often preferred. For long-term or multi-board projects, Zephyr can be a better choice.

    5. Is Zephyr supported on ESP32?

    Yes. ESP32 Zephyr vs FreeRTOS is a common comparison. FreeRTOS is deeply integrated into ESP-IDF and remains the easiest option. Zephyr also supports ESP32 and offers better portability across vendors, though setup is slightly more complex.

    6. How does Zephyr compare to Embedded Linux?

    Zephyr vs Embedded Linux is not a direct competition. Zephyr runs on microcontrollers without an MMU and is designed for real-time behavior. Embedded Linux requires more memory, boots slower, and is not hard real-time by default. If you need deterministic timing and low resource usage, Zephyr is the better fit.

    7. Zephyr vs FreeRTOS vs ThreadX: which should I choose?

    In ThreadX vs FreeRTOS vs Zephyr, FreeRTOS is the simplest and most popular. ThreadX is fast and polished but more enterprise-focused. Zephyr is modern, open, and scalable. Most independent developers choose FreeRTOS or Zephyr based on project complexity.

    8. How does Zephyr compare with NuttX?

    In NuttX vs FreeRTOS vs Zephyr, NuttX offers POSIX-like APIs and feels closer to Linux. Zephyr focuses more on embedded-first design and modern tooling. FreeRTOS remains the simplest. For most users, Zephyr offers a better balance than NuttX.

    9. Is FreeRTOS still relevant in 2026?

    Absolutely. FreeRTOS is widely used in production systems and continues to evolve. It remains a strong choice for small to medium embedded projects and is often the first RTOS engineers learn before moving to Zephyr.

    10. Can Zephyr replace FreeRTOS?

    Zephyr can replace FreeRTOS in many projects, especially IoT and connected devices. However, FreeRTOS is still better for very small systems with tight memory constraints. It’s not about replacement; it’s about choosing the right tool.

    11. What do developers say on Zephyr vs FreeRTOS Reddit threads?

    On Zephyr vs FreeRTOS Reddit discussions, most developers agree that FreeRTOS is easier to start with, while Zephyr is better for structured, long-term projects. Very few consider either option a bad choice.

    12. Which RTOS should I learn for jobs?

    If your goal is employability, start with FreeRTOS because it’s everywhere. Then learn Zephyr to show you can handle modern, scalable embedded systems. Knowing both gives you a strong advantage.

    13. Is Zephyr better for IoT than FreeRTOS?

    Yes, in many cases. Zephyr has built-in networking, security, and device management features. For connected products, Zephyr OS often reduces development effort compared to FreeRTOS.

    If you’re enjoying this project and want to explore more powerful sensor integrations, make sure to check out my detailed guide on using the ESP32 with the DS18B20 temperature sensor. It’s a beginner-friendly, real-world tutorial that shows how to measure temperature with high accuracy and integrate the data into IoT dashboards, automation systems, or cloud servers. You can read the full step-by-step guide here: ESP with DS18b20

    This resource pairs perfectly with your ESP32 with RFID setup together, you can build advanced smart home systems, environmental monitoring tools, or complete multi-sensor IoT projects.

  • FPU Warning Fix & FPU Errors: Complete Beginner-Friendly Guide (2026)

    FPU Warning Fix & FPU Errors :Fix FPU warnings and floating-point errors easily. Learn causes, solutions, and how to resolve “FPU is not initialized” in this simple beginner-friendly guide.

    Understand, Diagnose, and Fix Floating Point Unit Problems Like a Pro

    If you’ve ever written embedded code, worked with a microcontroller, or compiled software for an ARM system, you’ve probably run into strange messages that look like this:

    • FPU warning fix required
    • FPU errors during execution
    • warning “FPU is not initialized”

    At first, they feel scary. You see words like “FPU” and instantly think something major is broken. But don’t worry. These warnings are more common than you think, and they’re usually easy to fix once you understand what’s going on.

    So let’s grab a coffee and debugging code together.

    What Is the FPU and Why It Matters

    Before we talk about fpu errors or a proper fpu warning fix, you need a simple picture of what the FPU is.

    FPU = Floating Point Unit
    It’s a tiny hardware block inside your processor that performs:

    • floating-point calculations
    • mathematical operations like division or square root
    • DSP-style computations
    • audio, sensor, and graphics-related math

    In short, any time your program uses:

    float
    double
    sin()
    exp()
    pow()
    0.1 + 4.5
    

    …the FPU is involved.

    If the FPU isn’t enabled, isn’t initialized, or your build settings don’t match your CPU, you’ll see fpu errors or warnings like:

    warning “FPU is not initialized”

    This is your system telling you:
    “Hey, I’m trying to run floating-point stuff, but I’m not set up for it.”

    How to Solve FPU Errors in STM32CubeIDE (Step-by-Step Guide)

    If you’re working with STM32 microcontrollers, especially Cortex-M4 or Cortex-M7 devices, you may often see warnings like:

    • FPU not enabled
    • warning “FPU is not initialized”
    • FPU instructions generated but FPU not present
    • floating point instructions cause HardFault

    These usually appear in STM32CubeIDE when your compiler flags, MCU configuration, or startup code are not aligned.
    Here’s the simplest, beginner-friendly guide to fixing all fpu errors in STM32CubeIDE.

    1. Enable FPU in STM32CubeMX (Device Configuration Tool)

    Step 1: Open Your Project in CubeMX inside STM32CubeIDE

    Go to:
    Project > Open in CubeMX

    Step 2: Enable FPU in “System Core → Cortex-Mx”

    Navigate to:
    System Core → Cortex-Mx

    Under FPU Settings, choose:

    • “Hardware Floating Point (single precision)” for Cortex-M4F
    • “Hardware Floating Point (single precision)” for Cortex-M7

    Make sure FPU = Enabled.

    Step 3: Save and Regenerate Code

    CubeMX automatically updates:

    • startup code
    • system initialization
    • compiler flags

    This alone fixes 80% of FPU warnings.

    2. Verify Compiler Settings in STM32CubeIDE

    Even if CubeMX enables the FPU, sometimes the IDE still uses incorrect compiler flags.
    Check them manually.

    Step 1: Right-click Your Project → Properties

    Step 2: Go to

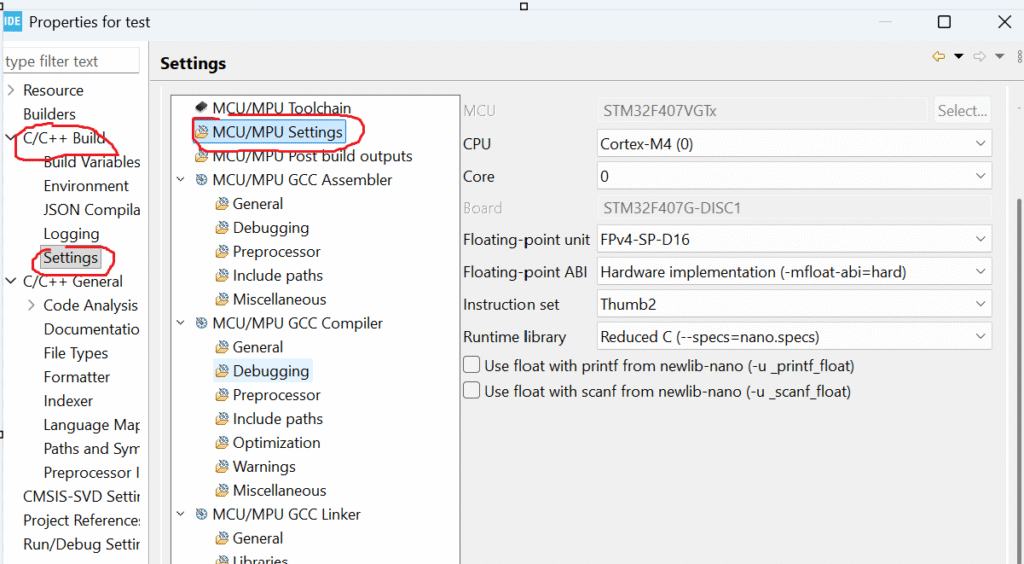
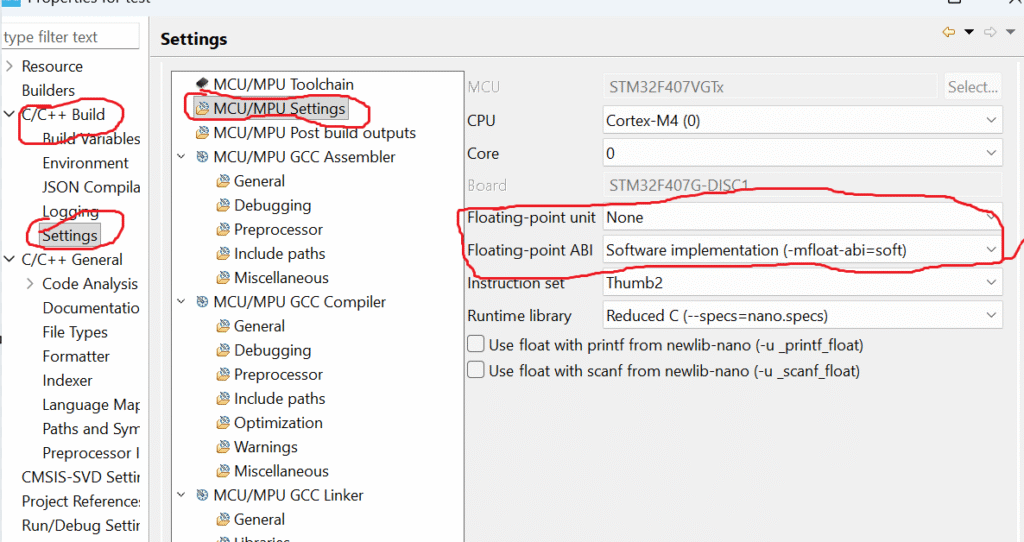
    C/C++ Build → Settings → MCU Settings
    

    Make sure these settings are correct:

    • Floating Point Unit: FPv4-SP-D16 (for Cortex-M4)
    • Floating Point ABI: Hard

    Internal flags that must appear automatically:

    -mfpu=fpv4-sp-d16
    -mfloat-abi=hard
    

    If you’re using Cortex-M7, expect:

    -mfpu=fpv5-sp-d16
    -mfloat-abi=hard
    

    If these are wrong…

    You will get typical fpu errors like:

    • unexpected NaN
    • wrong floating-value output
    • HardFault on floating math
    • slow float performance

    Fixing the flags eliminates these issues instantly.

    3. Ensure FPU Is Enabled in system_stm32xxxx.c

    Even if CubeMX should do this automatically, it sometimes doesn’t.

    Open:

    system_stm32f4xx.c
    system_stm32f7xx.c
    system_stm32h7xx.c
    

    Look for:

    SCB->CPACR |= (0xF << 20);   // Enable CP10 + CP11
    

    If it’s missing, add this line inside SystemInit() before calling HAL functions.

    This prevents the common error:

    warning “FPU is not initialized”

    4. Avoid Using Floats Before SystemInit()

    Many beginners accidentally use float operations inside:

    • constructor of a global object
    • static initializers
    • early Reset_Handler code
    • before HAL_Init()

    This leads to runtime fpu errors.

    Fix:

    Make sure floating-point math happens after:

    HAL_Init();
    SystemClock_Config();
    

    5. Fix HardFault from Floating Point Use in FreeRTOS

    If you’re using FreeRTOS with STM32, you must enable FPU support for tasks.

    Add:

    configUSE_TASK_FPU_SUPPORT 2
    

    Or create tasks with:

    xTaskCreate(taskFunc, "task", stack, NULL, priority, &handle);
    

    FreeRTOS will automatically:

    • save/restore FPU registers
    • prevent task-switch corruption
    • avoid NaN randomness

    Without this, multiple tasks fight for the same FPU, causing floating-point bugs.

    6. Clean and Rebuild Your Project

    After enabling FPU:

    • Project → Clean
    • Project → Build

    STM32CubeIDE sometimes keeps old flags; a full clean ensures the new settings apply.

    7. Test Floating Point Output

    Add a simple test:

    float a = 10.5f;
    float b = 3.2f;
    float c = a * b;
    
    printf("FPU Test: %f\n", c);
    

    If output is correct and no warning appears, you’ve solved the issue.

    Why you see the warning (short):

    The compiler is telling you that your project is set to use the processor’s hardware FPU, but your code never enables (initializes) it. If you run floating-point code before the FPU is enabled, the CPU can raise a fault.

    Quick step-by-step fix (STM32CubeIDE):

    1. Right-click your project → Properties.
    2. Open C/C++ Build → Settings.
    3. Under Tool Settings, find MCU Settings.
    4. Set Floating Point Unit to the correct hardware FPU for your MCU.
    5. Set Floating Point ABI to the matching ABI (usually hard when you use the hardware FPU).
    6. Click Apply and Close.
    7. Do Project → Clean (or clean the build).
    8. Rebuild the project.

    After these steps, either the IDE will add proper FPU init code for you or you’ll know to enable the FPU at startup in your SystemInit() (e.g. by setting CPACR on Cortex-M) before any floating-point operations run.

    Fixing FPU Errors in STM32CubeIDE
    Fixing FPU Errors in STM32CubeIDE

    Common Causes of FPU Errors

    Let’s break down the real reasons behind fpu warning fix requirements.

    1. FPU not enabled in the microcontroller startup code

    On Cortex-M4, M7, R5, or A-series processors, the FPU must be manually enabled.

    If not, you’ll see:

    • weird computation results
    • hard faults
    • NaN values
    • compiler warnings
    • runtime messages like warning “FPU is not initialized”

    2. Compiler flags mismatch

    On embedded systems, these flags matter:

    -mfpu=fpv4-sp-d16
    -mfloat-abi=hard
    

    If you compile with FPU support but the hardware lacks it, the program crashes.
    If the hardware supports FPU but compiler doesn’t use it, you get slow code or warnings.

    3. OS not initializing FPU during context switching

    In RTOS systems like:

    • FreeRTOS
    • QNX
    • ThreadX
    • Zephyr

    …each task must save/restore FPU registers.
    If not, FPU corruption occurs.

    4. Using floating values before startup completes

    Some developers accidentally call floating functions inside:

    • early boot
    • before system init
    • inside interrupts

    That leads to fpu errors.

    5. Incorrect exception or lazy stacking settings

    For example, on ARM:

    • enabling lazy FPU stacking incorrectly
    • disabling automatic FP context saving

    …triggers random crashes.

    Signs That You’re Facing FPU Problems

    Here’s how you know you need an fpu warning fix:

    • your program runs but produces incorrect float values
    • occasional crashes when using math functions
    • system gives warning “FPU is not initialized”
    • compiler prints FPU mismatch warnings
    • enabling or disabling FPU changes program behavior
    • DSP code runs extremely slow

    If any of these sound familiar, the next sections will help you fix it.

    How to Fix FPU Warnings (Step by Step)

    Let’s walk through the most common fpu warning fix steps.

    This works for ARM Cortex (M0+, M3, M4, M7, A-series) and most embedded platforms.

    1. Enable FPU in Startup Code

    For most ARM Cortex-M4/M7 microcontrollers, add this:

    SCB->CPACR |= (0xF << 20);    // Enable CP10 and CP11 (FPU)
    

    This registers block controls the CPU’s FPU access.

    After enabling:

    • flush caches
    • set CONTROL register if needed
    • call SystemInit()

    If this isn’t done, you’ll keep seeing warning “FPU is not initialized”.

    2. Fix Compiler Flags

    For Cortex-M4F or M7F:

    -mfpu=fpv4-sp-d16
    -mfloat-abi=hard
    

    For Cortex-A processors:

    -mfpu=neon-fp-armv8
    -mfloat-abi=hard
    

    If you choose the wrong option, GCC throws:

    • “FPU not supported on this architecture”
    • “FPU instructions generated but target does not support FPU”

    Quick rule:

    HardwareCompiler Flag
    Cortex-M0/M3No FPU; disable FPU
    Cortex-M4Ffpv4-sp-d16
    Cortex-M7Ffpv5-sp-d16
    Cortex-Aneon-fp

    3. OS/RTOS Must Manage FPU Context

    In systems like FreeRTOS:

    You must enable:

    configUSE_TASK_FPU_SUPPORT
    

    Otherwise:

    • tasks overwrite each other’s float registers
    • random NaN values appear
    • fpu errors show up under load

    4. Do Not Use Float in Early Boot

    The FPU is usually disabled before system startup.

    Avoid using floating point in:

    • Reset handler
    • Early init functions
    • Bare-metal interrupt handlers

    If you must use it, initialize the FPU first.

    5. Disable or Adjust Lazy FPU Stacking

    Lazy stacking is a power optimization.
    But on some MCUs, it triggers weird issues.

    To disable:

    FPU->FPCCR &= ~(FPU_FPCCR_LSPEN_Msk);
    

    If you experience random hard faults, try toggling lazy stacking.

    FPU Errors During Runtime: What They Really Mean

    Even after initialization, you may face runtime fpu errors like:

    • invalid operation
    • divide by zero
    • underflow
    • overflow
    • inexact result

    These are normal floating-point exceptions.

    Example:

    float x = 1.0 / 0.0;   // Inf
    float y = 0.0 / 0.0;   // NaN
    

    How to debug:

    • print float values
    • check stack corruption
    • inspect FPU registers (S0–S31)
    • check your ABI settings

    Practical Example: Eliminating the FPU Initialization Warning

    Let’s fix the exact error:

    warning “FPU is not initialized”

    Cause:
    Code uses floats before FPU is enabled.

    Fix:
    Enable FPU at the very start of SystemInit.

    void SystemInit(void)
    {
        SCB->CPACR |= (0xF << 20);    // FPU enable
        __DSB();
        __ISB();
    }
    

    Now the warning disappears.
    And your float math becomes faster, correct, and stable.

    FPU Warning Fix in Linux / QNX / Android Systems

    Sometimes the warning comes not from bare metal, but from OS logs.

    Why it happens:

    • kernel doesn’t initialize thread FP state
    • user-space app uses floating point before kernel setup
    • context switching issues

    Fix:

    On QNX or Linux, ensure your thread creates an FP context:

    pthread_attr_setfp(regs, PTHREAD_FP_ENABLE);
    

    Some OSes call it “VFP context” instead of FPU.

    How to Avoid FPU Errors in the Future

    Here are practical tips:

    Always match your toolchain flags to your CPU

    Check the datasheet.

    Enable FPU before using floats

    Do it in SystemInit.

    Avoid floats in interrupts

    Use fixed-point instead.

    Test with edge cases

    Division by zero
    Very small numbers
    Very large numbers

    Keep RTOS FPU context switching enabled

    This prevents cross-task corruption.

    Beginner vs. Experienced Developer Understanding

    Here’s how different developers see the issue.

    Beginners

    • see the warning
    • google it
    • try random fixes
    • still face errors

    Experienced developers

    • check CPU architecture
    • verify compiler flags
    • check startup code
    • inspect context switching

    But now, after this guide, you’ll think like the second group.

    FPU Warning Fix & FPU Errors

    Q1. What is the simplest fix for “warning FPU is not initialized”?
    Enable the FPU in startup code using CPACR.

    Q2. Will enabling FPU break anything?
    No. If your CPU has an FPU, enabling it only improves performance.

    Q3. Why do I get FPU errors only sometimes?
    Usually due to RTOS tasks not saving/restoring FPU registers.

    Q4. Why does float computation produce random values?
    Because FPU registers were overwritten by another task or interrupt.

    Q5. Can an MCU run without FPU enabled?
    Yes, but float operations become slow and warnings appear.

    Q6. Why does enabling lazy stacking cause random crashes?
    Some MCUs have silicon bugs related to it.

    Q7. Do Cortex-M0/M3 have FPU?
    No. Never compile them with FPU flags.

    Q8. What causes floating-point divide-by-zero errors?
    Normal IEEE-754 behavior; not a hardware issue.

    Q9. My compiler shows FPU mismatch warnings. What now?
    Fix your -mfpu and -mfloat-abi flags.

    Q10. Can I completely avoid FPU errors?
    Yes, by initializing FPU properly and using correct compiler flags.

    If you’re learning C programming and want to strengthen your fundamentals before practicing Structures and Unions Interview Questions, you should explore this detailed beginner-friendly guide on structures: Structures in C – Complete Guide
    It explains structure syntax, memory layout, padding, nesting, and real-world examples in a very simple way. Reading this will give you a strong foundation before jumping into advanced interview questions.

    Conclusion: You Can Now Fix Any FPU Warning

    You now understand:

    • what the FPU is
    • why fpu errors appear
    • how to solve fpu warning fix issues
    • how to fix warning “FPU is not initialized”
    • how to configure compiler flags
    • how to avoid problems in RTOS

    Whether you’re a beginner or an experienced embedded developer, this guide covers everything you need to solve floating-point issues confidently.

    FAQ : PU Warning Fix & FPU Errors

    1. What does “FPU Warning Fix” actually mean in STM32 or embedded projects?

    FPU Warning Fix simply means your compiler is alerting you that hardware floating-point instructions are enabled, but your startup code has not initialized the FPU yet. If you use floating-point operations without enabling the FPU, your MCU can crash due to a UsageFault.

    2. Why do FPU errors happen in ARM Cortex-M processors?

    FPU errors occur when:
    FPU hardware is enabled in project settings
    But FPU is not activated in CPACR register
    Or floating-point ABI does not match compiler flags
    This mismatch leads to NOCP faults, crashes, or undefined behavior.

    3. How do I fix FPU warnings in STM32CubeIDE?

    You can solve the warning by:
    Enabling the correct FPU type (e.g., FPv4-SP-D16).
    Selecting the correct floating-point ABI (Hard or SoftFP).
    Initializing CP10/CP11 in SystemInit() before using floats.
    Cleaning and rebuilding the project.

    4. Do I need to enable the FPU manually in code?

    Yes if your startup file does not handle it automatically.
    You must set CPACR bits for CP10 and CP11. Without this, the processor cannot execute any floating-point instructions, causing exceptions.

    5. Why does my project crash when using float or double?

    This happens when FPU instructions are generated, but the processor does not have permission to execute them. The CPU then raises a UsageFault, commonly due to:
    FPU not initialized
    Wrong ABI
    Wrong compiler flags
    RTOS not handling FPU context switching

    6. What FPU settings should I select in STM32CubeIDE?

    For most Cortex-M4/M7 MCUs:
    Floating Point Unit: FPv4-SP-D16 / FPv5
    Floating Point ABI: Hard (recommended)
    SoftFP can be used, but code will be slower.

    7. How does improper FPU configuration affect performance?

    Incorrect FPU setup forces the compiler to use software-based emulation for floating-point operations. This increases CPU cycles drastically, slows application performance, and can create unexpected delays.

    8. Can RTOS users face FPU errors more often?

    Yes. RTOS switches context between tasks.
    If the RTOS does not save/restore FPU registers correctly, tasks using floating-point variables may corrupt the FPU state, causing random crashes or hard faults.

    9. What is the best way to avoid FPU errors in new projects?

    Follow this checklist:
    Choose correct FPU + ABI settings
    Initialize CPACR early
    Avoid floating-point operations inside ISRs
    Verify your RTOS supports FPU context switching
    Test float operations under debugger

    10. How do I verify my FPU is working correctly?

    You can debug by checking:
    CPACR register (CP10 & CP11 bits = 0xF)
    No NOCP bit set in UsageFault Status Register
    Simple float operations execute without exception
    If all checks pass, your FPU is fully enabled and stable.
  • Microprocessor 8085 Complete Guide: Master 8085 From Zero to Expert

    Learn Microprocessor 8085 from beginner to advanced: interview questions, programming, architecture, and FAQs for students & embedded engineers.

    If you ever wanted a simple, clear, and genuinely explanation of the Microprocessor 8085, this is your complete guide. Think of this as a friendly conversation where we go from basics to advanced topics without jargon or confusion.

    Whether you’re a student preparing for your microprocessor exam, an engineer revising concepts, or someone exploring old-school tech out of curiosity, this Microprocessor 8085 complete guide covers everything.

    What Is Microprocessor 8085?

    The 8085 microprocessor is an 8-bit general-purpose processor developed by Intel in 1977. It became extremely popular in India because of its simple design, instruction set, and availability of kits in engineering labs.

    Definition (Easy to remember):

    A microprocessor 8085 is a programmable digital IC that fetches, decodes, and executes instructions to perform tasks like arithmetic, logic, controlling hardware, and data handling.

    Designed by:

    Intel engineer Federico Faggin

    Used in:

    – Calculators
    – Early computers
    – Embedded controllers
    – Measurement systems
    – Teaching labs (the most common use today)

    History of Microprocessor 8085

    The history of microprocessor 8085 starts with Intel’s earlier processors:

    • 4004 → First commercial microprocessor
    • 8080 → Widely used
    • 8085 → Improved version of 8080 with fewer external components
    • 8086 → Actual father of modern x86 architecture

    Features of Microprocessor 8085

    The most important features of microprocessor 8085 include:

    • 8-bit processor: handles 8-bit data at a time
    • 16-bit address bus: can address 64 KB memory
    • 5 interrupts: TRAP, RST7.5, RST6.5, RST5.5, INTR
    • Machine cycle: 8 control signals
    • Clock frequency: 3.072 MHz
    • Single +5V supply
    • 74 instructions and 246 opcodes

    Microprocessor 8085 Architecture

    This is the heart of the Microprocessor 8085 complete guide.

    When we talk about the architecture of microprocessor 8085, we discuss how all internal blocks work together—like ALU, registers, buses, and timing circuits.

    Important Blocks in the 8085

    • ALU – Performs arithmetic + logic
    • Registers – Temporary data storage
    • Accumulator – Most important register
    • Instruction Register + Decoder
    • Control Unit – Controls everything
    • Interrupt Control
    • Serial I/O Control
    • Timing and Control Unit
    • Address Buffer and Data Buffer

    Block Diagram of Microprocessor 8085

    Let’s explain the block diagram of microprocessor 8085 in the simplest way.

    What the block diagram includes:

    • ALU
    • Register array (B, C, D, E, H, L, A)
    • Program Counter
    • Stack Pointer
    • Temporary registers
    • Interrupts
    • Internal data bus
    • Timing and control circuits

    Why this matters?

    Every exam question like “draw the architecture of microprocessor 8085” or “functional block diagram of microprocessor 8085” is based on this.

    Pin Diagram of Microprocessor 8085

    The pin configuration of microprocessor 8085 has 40 pins, and understanding these pins is mandatory for interfacing.

    Important pins include:

    • A0–A15 → 16 address pins
    • AD0–AD7 → Multiplexed (Address/Data)
    • ALE → Address Latch Enable
    • RD, WR → Read/Write
    • IO/M → Selects memory or I/O
    • READY, HOLD, HLDA → DMA control
    • TRAP, RST7.5, RST6.5, RST5.5, INTR → Interrupts

    Instruction Set of 8085

    Learning the microprocessor 8085 instruction set is the biggest part of programming. The instruction set includes:

    • Data Transfer Instructions (MOV, MVI, LDA)
    • Arithmetic Instructions (ADD, ADI, SUB)
    • Logical Instructions (ANA, ORA, CMA)
    • Branching Instructions (JMP, JC, JNZ)
    • Stack Instructions (PUSH, POP)
    • I/O Instructions (IN, OUT)

    Working of Microprocessor 8085

    If someone asks How does 8085 microprocessor work?, the simplest answer is:

    1. Fetch the instruction
    2. Decode the instruction
    3. Execute the instruction

    These are called Machine cycles, and each machine cycle has T-states.

    Memory in Microprocessor 8085

    8085 uses a 16-bit address bus, so:

    Total memory it can address:

    2ⁱ⁶ = 65536 bytes = 64 KB

    Types of memory used:

    • ROM → Stores programs
    • RAM → Temporary data
    • Stack memory → LIFO storage

    Registers of Microprocessor 8085

    8085 contains:

    General Purpose Registers (GPRs):

    B, C
    D, E
    H, L

    Special registers:

    • Accumulator
    • Program Counter
    • Stack Pointer
    • Temporary registers
    • Instruction register
    • Flag register

    Flag Register in Microprocessor 8085

    The flag register (also called the status register) is an 8-bit register that shows the outcome of ALU operations.
    Whenever the 8085 performs addition, subtraction, compare, or logic operation—these flags automatically update.

    The 5 Flags Are:

    1. S – Sign Flag
    2. Z – Zero Flag
    3. AC – Auxiliary Carry Flag
    4. P – Parity Flag
    5. CY – Carry Flag

    Why flags matter?

    Every conditional instruction (JC, JNC, JZ, JNZ, JP, JM) depends on these flags.
    Without flags, the microprocessor cannot make decisions.

    Interrupts in Microprocessor 8085

    Interrupts allow the microprocessor to stop the current work and respond to an urgent request.

    Types of Interrupts

    8085 has five hardware interrupts:

    InterruptTypePriorityMaskable?
    TRAPNon-maskableHighestNo
    RST 7.5MaskableHighYes
    RST 6.5MaskableMediumYes
    RST 5.5MaskableLowYes
    INTRGeneralLowestYes

    Key Terms:

    • INTR full form → Interrupt Request
    • INTR’s sequence → Acknowledged through INTA’ signal
    • Interrupt vector table → Stores service routines

    Timing, Control and Machine Cycles

    To understand how instructions execute, you must know the machine cycle of microprocessor 8085.

    What is a Machine Cycle?

    A set of T-states required to complete one operation like memory read, memory write, instruction fetch, etc.

    Common Machine Cycles:

    • Opcode Fetch Cycle
    • Memory Read Cycle
    • Memory Write Cycle
    • I/O Read Cycle
    • I/O Write Cycle
    • Interrupt Acknowledge Cycle

    Example:
    Opcode Fetch = 4 T-states
    Memory Read = 3 T-states

    Addressing Modes of Microprocessor 8085

    Addressing modes tell the processor where to find data.

    8085 Has 5 Addressing Modes:

    1. Immediate Addressing
    2. Register Addressing
    3. Direct Addressing
    4. Indirect Addressing
    5. Implied (Implicit) Addressing

    Example:

    • MVI A, 32H → Immediate
    • MOV A, B → Register
    • LDA 2050H → Direct
    • MOV A, M → Indirect

    Instruction Format of Microprocessor 8085

    Every instruction in 8085 follows one of the following formats:

    Three instruction formats:

    • 1-byte instruction
    • 2-byte instruction
    • 3-byte instruction

    Examples

    • 1-byte → MOV A,B
    • 2-byte → MVI A,32H
    • 3-byte → STA 5000H

    Assembly Language Programming in Microprocessor 8085

    If you want to become confident in 8085, this part is important.

    Simple 8085 Programs

    1) Program to Add Two Numbers

    MVI A, 25H
    MVI B, 30H
    ADD B
    HLT
    

    2) Program for Subtraction

    MVI A, 90H
    MVI B, 40H
    SUB B
    HLT
    

    3) Program for Multiplication (Loop Method)

    8085 has no MUL instruction, so we add in a loop.

    Stack and Subroutines

    Stack Pointer in 8085

    • A 16-bit register
    • Follows LIFO
    • Important for PUSH, POP, CALL, RET instructions

    Subroutine

    A small block of code used repeatedly.

    Example:

    CALL 2000H
    ...
    RET
    

    Memory Interfacing in Microprocessor 8085

    To connect RAM/ROM to the microprocessor, you must understand:

    Key Signals Used in Memory Interfacing:

    • RD’ → Read
    • WR’ → Write
    • IO/M’ → Select I/O or Memory
    • ALE → Latch lower address

    Memory Mapping Steps:

    1. Decide memory size
    2. Assign address range
    3. Connect address lines
    4. Connect control signals
    5. Test with instructions

    I/O Interfacing in Microprocessor 8085

    The microprocessor communicates with external devices using:

    Two types of I/O addressing:

    1. Isolated I/O (IN, OUT instructions)
    2. Memory-mapped I/O

    Common Interfacing ICs Used:

    • 8255 PPI
    • 8253 Timer
    • 8279 Keyboard/Display
    • 8251 USART

    Difference Between 8085 and 8086

    Here is the simplest interview-style comparison:

    Feature80858086
    Data Bus8-bit16-bit
    Address Bus16-bit20-bit
    Memory64 KB1 MB
    Supply Voltage+5V+5V
    Instructions246256+
    Year19771978

    Applications of Microprocessor 8085

    The application of microprocessor 8085 includes:

    • Traffic light control
    • Washing machines (old models)
    • Measurement systems
    • Stepper motor control
    • Data acquisition
    • Simple embedded projects
    • Educational use

    Advantages and Disadvantages of Microprocessor 8085

    Advantages

    • Simple architecture
    • Easy to program
    • Requires only +5V
    • Beginner-friendly
    • Cost-effective

    Disadvantages

    • Limited memory (64KB)
    • No multiplication/division instruction
    • Slow compared to modern processors
    • No pipeline

    8085 Flag Register

    The Flag Register in 8085 is an 8-bit special purpose register that indicates the status of the ALU operation. Out of 8 bits, five are active flags and the remaining are unused.

    Active Flags

    FlagMeaningWhen it is SET
    S – Sign FlagIndicates sign of resultResult MSB = 1 (negative)
    Z – Zero FlagResult becomes zeroResult = 0
    AC – Auxiliary CarryBCD operationsCarry from bit 3 → bit 4
    P – Parity FlagEven/Odd parityEven number of 1s
    CY – Carry FlagBorrow/CarryCarry out from D7

    Understanding with Example

    Instruction: MVI A, 0xFF then ADI 0x01

    • Result = 00
    • Z flag = 1
    • CY flag = 1
    • P flag = 1
    • S flag = 0

    This is classic interview question material!

    8085 Timing Diagrams

    What is a Timing Diagram?

    It’s a visual representation of how control signals change during instruction execution.

    Why Important?

    8085 is used heavily in interviews because timing diagrams show:

    • T-states
    • Machine cycles
    • Instruction cycles
    • Memory Read/Write behavior

    Example : Opcode Fetch Cycle

    SignalsDescription
    ALEHigh → Low (latches address)
    RDLow during reading
    IO/MLow (means memory access)
    Address BusPuts PC address
    Data BusReceives Opcode

    Example : Memory Read Timing

    • T1: Address from PC is put on bus
    • T2: RD = 0
    • T3: Data from memory placed on data bus

    These diagrams show hardware-level understanding very useful in embedded interviews.

    Interrupt System of 8085 (Full Breakdown)

    8085 has 5 hardware interrupts:

    InterruptTypeVector AddressPriority
    TRAPNon-maskable0024HHighest
    RST 7.5Maskable003CH2nd
    RST 6.5Maskable0034H3rd
    RST 5.5Maskable002CH4th
    INTRMaskableExternalLowest

    TRAP

    • Cannot be disabled
    • Edge + level triggered
    • Used in emergency situations

    RST 7.5

    • Highest priority maskable interrupt
    • Edge-triggered
    • Must be acknowledged

    RST 6.5 & 5.5

    • Level-triggered
    • Medium priority

    INTR

    • Completely programmable
    • Requires INTA cycle for vector

    This table is gold for interviews.

    Interrupt Enable/Disable Instructions

    InstructionPurpose
    EIEnable all maskable interrupts
    DIDisable all maskable interrupts
    SIMSet Interrupt Mask
    RIMRead Interrupt Mask

    Example:

    EI     ; enable interrupts
    MVI A, 0x20
    SIM    ; mask RST 5.5
    

    Serial Communication in 8085 (SID & SOD)

    8085 has simple 1-bit serial I/O pins:

    SID : Serial Input Data

    Reads one bit at a time.

    SOD : Serial Output Data

    Writes one bit at a time.

    Used with SIM/RIM.

    Example:

    MVI A, 01H  
    SIM    ; send 1 bit through SOD
    

    Though old, this concept is foundational for UART learning.

    Addressing Modes (Expert Level)

    8085 supports five addressing modes:

    ModeExampleMeaning
    ImmediateMVI A, 32HData is inside the instruction
    RegisterMOV A, BData in CPU register
    DirectLDA 2050HAccess memory by address
    IndirectMOV A, MUse HL as pointer
    ImpliedCMAOperation already known

    Why important?

    Interviewers ask to convert C code to 8085 assembly → you must choose correct addressing mode.

    8085 Instruction Set

    Data Transfer Instructions

    MOV, MVI, LXI, LDA, STA, LDAX, STAX

    Arithmetic Instructions

    ADD, ADI, SUB, INR, DCR, INX, DCX

    Logical Instructions

    ANA, ORA, XRA, CMA, RLC, RRC

    Branch Instructions

    JMP, JZ, JNZ, JC, JNC, CALL, RET

    Machine Control

    HLT, EI, DI, NOP, SIM, RIM

    Each group serves different use cases — an easy way to remember.

    8085 Memory Organization

    8085 can address:

    • 64 KB of memory total
    • Separate I/O address space (256 bytes)

    Memory Map Example:

    RangeUse
    0000H–0FFFHMonitor Program (ROM)
    1000H–7FFFHRAM
    8000H–FFFFHUser Program

    Useful for designing embedded boards.

    8085 Assembly Language Programs (With Explanation)

    Program 1 : Add Two Numbers

    MVI A, 25H
    MVI B, 30H
    ADD B
    STA 3000H
    HLT
    

    Output: 55H stored at 3000H.

    Program 2 : Find Largest Number in Array

    LXI H, 2050H
    MOV C, M
    INX H
    DCR C
    MOV A, M
    LOOP: INX H
    CMP M
    JNC NEXT
    MOV A, M
    NEXT: DCR C
    JNZ LOOP
    STA 3000H
    HLT
    

    Program 3 : BCD to Binary Conversion

    Used in industrial control applications.

    MVI A, 45H
    ANI 0FH
    MOV B, A
    MVI A, 45H
    ANI F0H
    RRC
    RRC
    RRC
    RRC
    MVI C, 0AH
    MUL: DCR C
    JNZ MUL
    ADD B
    HLT
    

    8085-Based System Design (Practical Guide)

    Components you can interface:

    • RAM (6264)
    • ROM (2764)
    • 8255 (Parallel Port)
    • 8279 (Keyboard/Display Controller)
    • 8251 (USART)
    • 8253 (Timer)

    Steps in System Design

    1. Decide memory map
    2. Connect address/data bus
    3. Use 74LS373 latch for lower address
    4. Connect ALE → latch
    5. Use RD, WR, IO/M for decoding
    6. Use address decoder (74LS138)
    7. Interface peripherals

    This is real embedded hardware knowledge.

    Microprocessor 8085 Interview Questions

    BEGINNER LEVEL 8085 INTERVIEW QUESTIONS

    1. What is a microprocessor?
    2. What is the 8085 microprocessor?
    3. Why is it called 8085?
    4. How many pins are available in 8085?
    5. What is the clock frequency of 8085?
    6. How many address lines does 8085 have?
    7. How many data lines are in 8085?
    8. What is the size of the data bus of 8085?
    9. Name all general-purpose registers in 8085.
    10. What is the accumulator in 8085?
    11. What is the Program Counter (PC)?
    12. What is the Stack Pointer (SP)?
    13. What is the Flag Register in 8085?
    14. Name all the flags in 8085.
    15. What is the purpose of ALE (Address Latch Enable)?
    16. What is the READY pin used for?
    17. What is the HOLD signal used for?
    18. What are SID and SOD pins?
    19. What is the function of IO/M̅?
    20. What is the purpose of the RESET IN pin?

    INTERMEDIATE LEVEL 8085 INTERVIEW QUESTIONS

    1. Draw and explain the architecture of 8085.
    2. What is a multiplexed address/data bus?
    3. Why are AD0–AD7 multiplexed in 8085?
    4. What is a machine cycle?
    5. What is a T-state?
    6. Explain the opcode fetch cycle.
    7. List all interrupt pins in 8085.
    8. Which interrupt has the highest priority?
    9. Which interrupt is non-maskable?
    10. What is the difference between INTR and INTA?
    11. What is SIM instruction?
    12. What is RIM instruction?
    13. What are the different addressing modes in 8085?
    14. What is the function of HL pair?
    15. What are the types of instructions in 8085?
    16. What is the difference between CALL and RET?
    17. What is the difference between JMP and JNZ?
    18. What is the role of SP during PUSH and POP?
    19. What is the purpose of the stack?
    20. How many types of instruction lengths are in 8085?
    21. What is the purpose of X1 and X2 pins?
    22. What is meant by vector address?
    23. What is the difference between IO-mapped and memory-mapped I/O?
    24. What is the difference between MOV M, A and MOV A, M?
    25. What is the function of RST instructions?
    26. What are software interrupts?
    27. What is the difference between EI and DI?
    28. What is the purpose of the HOLD and HLDA signals?
    29. Explain the READY signal in interfacing.
    30. What are wait states?

    ADVANCED LEVEL 8085 INTERVIEW QUESTIONS

    1. What is the full interrupt priority structure of 8085?
    2. What is TRAP and how does it work?
    3. What is the difference between edge-triggered and level-triggered interrupts?
    4. Explain instruction pipelining in 8085.
    5. What are vectored interrupts?
    6. What is bus contention?
    7. What is bus idle state?
    8. Explain the timing diagram of memory read cycle.
    9. Explain the timing diagram of memory write cycle.
    10. Explain the timing diagram of I/O read cycle.
    11. Explain the timing diagram of I/O write cycle.
    12. What is the purpose of the control signals RD̅ and WR̅?
    13. What is the difference between STC and CMC?
    14. What is the role of the ALU in 8085?
    15. What is the function of the internal clock generator?
    16. Explain the function of RESET OUT.
    17. What is the serial communication capability of 8085?
    18. How is the stack implemented in 8085?
    19. What is the difference between RAL and RAR?
    20. What is the difference between CMA and CMC?
    21. Explain the flags affected during arithmetic instructions.
    22. How does a conditional jump work internally?
    23. What is meant by branching delay?
    24. What is the function of DAD instruction?
    25. What is program memory and data memory in 8085 context?

    EXPERT LEVEL 8085 INTERVIEW QUESTIONS

    1. How does 8085 support interrupt masking?
    2. How does RST 7.5 differ from RST 6.5 and RST 5.5?
    3. How is memory mapped in 8085?
    4. How does 8085 communicate with peripheral chips?
    5. Explain the hardware required to interface RAM with 8085.
    6. How does 8085 store 16-bit data using an 8-bit bus?
    7. Explain 8085 bus cycles in detail.
    8. What is memory segmentation in 8085?
    9. Describe the operation of the HOLD signal in DMA.
    10. How is data transferred using DMA with 8085?
    11. Describe the internal data flow of 8085 during an addition operation.
    12. Explain how subroutine nesting works in 8085.
    13. What are the advantages of vectored interrupts over polling?
    14. How does 8085 differentiate between memory and I/O operations?
    15. Explain the purpose of interrupt vector table.
    16. How does 8085 fetch 3-byte instructions?
    17. What is the use of PSW (Program Status Word)?
    18. What is an instruction cycle and how is it composed?
    19. Explain the difference between logical, arithmetic, and branching instructions.
    20. What is the purpose of the accumulator during logical operations?
    21. How does a carry propagate in multi-byte addition?
    22. What is the role of temporary registers inside 8085?
    23. Explain the concept of stack overflow and underflow in 8085.
    24. How is memory decoding done for 8085?
    25. Explain the complete 8085 reset sequence.

    8085 Coding/Programming Interview Questions

    BEGINNER-LEVEL 8085 CODING QUESTIONS

    1. Write an 8085 program to add two 8-bit numbers.
    2. Write an 8085 program to subtract two 8-bit numbers.
    3. Write an 8085 program to add two 16-bit numbers.
    4. Write an 8085 program to find 1’s complement of a number.
    5. Write an 8085 program to find 2’s complement of a number.
    6. Write an 8085 program to move data from one memory location to another.
    7. Write an 8085 program to exchange the contents of H-L pair and D-E pair.
    8. Write a program to increment a number stored in memory.
    9. Write a program to decrement a number stored in memory.
    10. Write an 8085 program to clear the accumulator.
    11. Write a program to load immediate data into registers.
    12. Write an 8085 program to implement a delay loop.
    13. Write an 8085 program to copy a block of data from one location to another.
    14. Write an 8085 program to compare two numbers.
    15. Write a program to check if a number is positive or negative.
    16. Write a program to mask upper nibble of accumulator.
    17. Write a program to mask lower nibble of accumulator.
    18. Write an 8085 program to rotate accumulator left (RAL).
    19. Write an 8085 program to rotate accumulator right (RAR).
    20. Write a program to swap nibbles of accumulator.

    INTERMEDIATE-LEVEL 8085 CODING QUESTIONS

    1. Write a program to find the largest number in an array.
    2. Write a program to find the smallest number in an array.
    3. Write a program to sort an array in ascending order.
    4. Write a program to sort an array in descending order.
    5. Write a program to count the number of positive numbers in an array.
    6. Write a program to count the number of negative numbers in an array.
    7. Write a program to reverse an array.
    8. Write a program to search for an element in an array (linear search).
    9. Write a program to calculate the sum of N numbers.
    10. Write a program to calculate the average of N numbers.
    11. Write an 8085 program to generate Fibonacci series.
    12. Write an 8085 program to check whether a number is even or odd.
    13. Write a program to multiply two 8-bit numbers (using repeated addition).
    14. Write a program to divide two 8-bit numbers (repeated subtraction).
    15. Write a program to convert BCD to binary.
    16. Write a program to convert binary to BCD.
    17. Write a program for binary to ASCII conversion.
    18. Write a program for ASCII to binary conversion.
    19. Write an 8085 program to find square of a number (lookup table).
    20. Write a program to implement left shift operation.
    21. Write a program to implement right shift operation.
    22. Write an 8085 program to count number of 1s in a binary number (bit count).
    23. Write a program to check palindrome number.
    24. Write a program to check if two numbers are equal.
    25. Write a program to transfer block of N bytes.

    ADVANCED-LEVEL 8085 CODING QUESTIONS

    1. Write an 8085 program to multiply two 16-bit numbers.
    2. Write an 8085 program to divide a 16-bit number by an 8-bit number.
    3. Write an 8085 program to perform 16-bit subtraction with borrow.
    4. Write an 8085 program to perform 16-bit addition with carry.
    5. Write a program to find factorial of a number.
    6. Write an 8085 program to check for prime number.
    7. Write an 8085 program to generate prime numbers within a range.
    8. Write a program to find GCD of two numbers.
    9. Write a program to find LCM of two numbers.
    10. Write a program to generate delay of 1 second using loops.
    11. Write a program to generate square wave using SOD line.
    12. Write a program for keyboard interfacing using RIM/SIM.
    13. Write an 8085 program to interface 7-segment display.
    14. Write a program to display 0–9 continuously on 7-segment.
    15. Write a program to interface 8255 PPI with 8085.
    16. Write a program to read a byte from port A and output it to port B.
    17. Write a program to control LEDs connected to 8255.
    18. Write a program to scan a matrix keypad using 8255.
    19. Write a program to read analog value through 8251 USART.
    20. Write a program to generate waveform on DAC using 8085.
    21. Write a program to perform block transfer using DMA.
    22. Write a program to store data at consecutive memory locations until 00H is found.
    23. Write an 8085 program to implement binary search.
    24. Write an 8085 program to convert 2-digit hex to decimal.
    25. Write a program to test specific bits of a number.

    EXPERT-LEVEL 8085 CODING QUESTIONS

    1. Write an 8085 program to perform floating-point addition.
    2. Write an 8085 program to perform floating-point multiplication.
    3. Write a program to implement software delay with precise calculation.
    4. Write a program to simulate stack operations using memory.
    5. Write a program to implement queue data structure in 8085.
    6. Write a program to implement stack data structure in 8085.
    7. Write an 8085 program to evaluate an arithmetic expression.
    8. Write an 8085 program to implement CRC calculation.
    9. Write an 8085 program to compute checksum of a data block.
    10. Write a program to encrypt data using XOR key.
    11. Write a program to decrypt XOR-encrypted data.
    12. Write a program to calculate 16-bit checksum (Internet checksum style).
    13. Write an 8085 routine to handle TRAP interrupt.
    14. Write a program to create custom software interrupt using RST instruction.
    15. Write a program to interface ADC0808 with 8085.
    16. Write a program to read temperature sensor data using ADC.
    17. Write a program for real-time clock simulation.
    18. Write an 8085 program to implement PWM using delay loops.
    19. Write a program to detect key debounce in keyboard input.
    20. Write an 8085 bootloader (memory copy from ROM to RAM).
    21. Write a program for bubble sort on 16-bit numbers.
    22. Write a program for insertion sort on 16-bit numbers.
    23. Write a program for quick sort using recursion (stack-based).
    24. Write a program to simulate UART transmission.
    25. Write a program to simulate UART reception.
    26. Write a program to generate a ramp waveform using DAC.
    27. Write a program to generate a sine wave using lookup table.
    28. Write a program to compute square root of a number.
    29. Write a recursive program for Fibonacci series.
    30. Write an 8085 interrupt-driven data acquisition program.

    Microprocessor 8085 FAQ

    What is a Microprocessor 8085?

    The Microprocessor 8085 is an 8-bit microprocessor developed by Intel. It can perform arithmetic, logical, and control operations, making it the heart of many early computer and embedded systems. It is widely used in academics because of its simple architecture and easy instruction set.

    Why is it called 8085?

    The name 8085 comes from Intel’s naming pattern:
    80 → Microprocessor family
    85 → Version or model number
    It also supports instructions similar to its predecessor 8080, but with improvements.

    What is the clock speed of 8085?

    The 8085 microprocessor uses a 6 MHz crystal, but the internal clock frequency becomes 3 MHz due to divide-by-2 circuitry.
    This speed controls how fast instructions are executed.

    What is the size of the data bus in 8085?

    8085 has an 8-bit data bus, meaning it can process 8 bits of data at a time.
    This is why it is known as an 8-bit microprocessor.

    How many address lines are in the 8085 microprocessor?

    8085 has 16 address lines (A0–A15).
    This allows it to access 2¹⁶ = 64 KB of memory, which includes RAM and ROM space.

    What are the main registers in 8085?

    The primary registers of 8085 include:
    Accumulator (A)
    B, C
    D, E
    H, L
    Program Counter (PC)
    Stack Pointer (SP)
    Flag Register
    These registers store temporary data and addresses during program execution.

    What is the role of the Accumulator (A register)?

    The Accumulator is the most important register in 8085.
    It stores data for arithmetic and logical operations and holds the final output of many instructions.

    What are flags in the 8085 microprocessor?

    Flags are status indicators that change after every arithmetic or logical operation.
    The five important flags are:
    Sign Flag (S)
    Zero Flag (Z)
    Auxiliary Carry (AC)
    Parity Flag (P)
    Carry Flag (CY)
    These help in decision-making instructions like JZ, JC, JNZ etc.

    What are interrupts in 8085?

    Interrupts temporarily pause the main program to execute an urgent task.
    8085 supports five hardware interrupts:
    TRAP (highest priority, non-maskable)
    RST 7.5
    RST 6.5
    RST 5.5
    INTR
    Interrupts improve real-time system performance.

    What is the difference between 8285 and 8085?

    Nothing there is no 8285 microprocessor.
    The correct Intel microprocessors in the family are 8080, 8085, 8086, 8088 etc.
    Many beginners confuse the names.

    What is the significance of ALE (Address Latch Enable)?

    ALE is used to demultiplex the lower 8 bits of the address and data bus.
    Since AD0–AD7 are multiplexed, ALE helps separate address and data during bus operations.

    What programming language is used in 8085?

    8085 uses Assembly Language, which consists of:
    Mnemonics (MOV, MVI, ADD, SUB, JMP)
    Operands (data/register/memory)
    Higher-level languages do not directly run on 8085.

    What is the maximum memory 8085 can access?

    8085 can access a total of 64 KB of memory due to its 16-bit address bus.
    This memory is divided into:
    ROM
    RAM
    I/O memory (in I/O-mapped mode)

    Why is 8085 still taught today?

    8085 is still widely taught because:
    The architecture is simple and easy to understand
    Excellent for learning registers, memory, opcodes, and addressing modes
    Helps students understand the fundamentals of microprocessors
    Ideal for academic labs and learning assembly language

    When it comes to mastering ESP microcontrollers, developers often struggle to find a single place where everything—from basics to advanced real-world projects—is explained clearly.
    That’s why resources like Embedded Prep Master have become extremely valuable for students, embedded engineers, and hobbyists.

    One of the best guides available today is:

    Complete ESP Tutorials (Beginner to Advanced) : ESP32 Tutorials

    This guide is a complete gateway for anyone who wants to learn ESP32, ESP8266, IoT development, sensor interfacing, Wi-Fi programming, and real embedded-system projects.

  • Where Do I Find Core Dump in Linux, and Master How Do I View and Analyze the Backtrace (Stack Trace 2026)

    If you’ve ever written a C, C++, Python, Java, or even a system-level application in Linux, chances are you’ve heard the term core dump. And if you’re reading this, you’ve probably also run into a frustrating crash where your program simply vanished with a cryptic message like Segmentation fault (core dumped).

    What Exactly Is a Core Dump in Linux?

    Let’s keep this simple.

    A core dump in Linux is a snapshot of your program’s memory at the exact moment it crashed.

    Think of it like taking a picture of a crime scene.
    You get:

    • The values of variables
    • The state of the stack
    • The content of memory
    • The instruction pointer location
    • Which function called which (stack trace)
    • And why the crash happened

    This is extremely useful for debugging crashes that are hard to reproduce.

    Developers use core dumps to figure out:

    • segmentation faults
    • illegal memory access
    • null pointer dereferences
    • stack corruption
    • out-of-bounds access
    • runtime exceptions

    If you ever wondered why your program crashed, the core dump is your truth-teller.

    How to Check if Core Dump Is Enabled in Linux

    Before you can view or analyze core dumps, you must check whether they’re even enabled.

    Run:

    ulimit -c
    

    You’ll get one of two results:

    0 → Core dumps are disabled

    This is the most common default.

    Unlimited → Core dumps are enabled

    This means the system will generate a core dump whenever an application crashes.

    How to Enable Core Dump in Linux (Temporary & Permanent Methods)

    If ulimit -c returns 0, your system won’t generate core files.

    Let’s fix that.

    1. Enable Core Dump Temporarily (For Current Session)

    Use:

    ulimit -c unlimited
    

    To verify:

    ulimit -c
    

    Now it should show:

    unlimited
    

    This lasts only for the current terminal session.

    2. Enable Core Dump Permanently (System-Wide)

    Edit /etc/security/limits.conf

    Add these lines:

    * soft core unlimited
    * hard core unlimited
    

    This ensures core dumps remain enabled for all users.

    3. Set Core Dump File Location and Format

    Linux stores core files based on kernel.core_pattern.

    Check its current value:

    cat /proc/sys/kernel/core_pattern
    

    You might see something like:

    core
    

    or

    core.%e.%p.%t
    

    or even:

    |/usr/share/apport/apport %p %s %c %P %u %g %t %e
    

    To store core dumps in a specific location, set:

    sudo bash -c 'echo "/var/core/core.%e.%p" > /proc/sys/kernel/core_pattern'
    

    This creates files like:

    core.myapp.1234
    

    Now you know exactly where to find them.

    Where to Find the Core Dump in Linux

    This depends on three things:

    1. Whether core dumps are enabled
    2. The value of kernel.core_pattern
    3. Your current working directory

    Here are the most common locations:

    1. The same directory from where the program was executed

    Example:

    ./myprogram
    Segmentation fault (core dumped)
    

    You might get:

    core
    

    2. /var/core/ directory (if configured by admin)

    Check using:

    ls /var/core/
    

    3. Custom directory defined by your core_pattern

    Example:

    /tmp/core.%e.%p
    

    4. Systemd-coredump service (Arch Linux, Fedora, Ubuntu newer versions)

    If you’re using Arch Linux, Fedora, or any distro using systemd, core dumps may not appear as files at all.

    Instead, they are stored in the system journal.

    Check them with:

    coredumpctl list
    

    To extract:

    coredumpctl dump > core.dump
    

    Or analyze directly:

    coredumpctl gdb
    

    This is why many people struggle finding core dump in Arch Linux—systemd stores them differently.

    How to Generate Core Dump in Linux (Manually)

    Sometimes your program won’t crash automatically, but you still want a core dump.

    Use this command:

    gcore <PID>
    

    Example:

    gcore 1532
    

    This creates:

    core.1532
    

    This is the easiest command to generate core dump in Linux.

    How to Collect Core Dump in Linux

    If you’re debugging servers or background processes, use:

    kill -SIGSEGV <PID>
    

    This forces the program to crash and generate a core dump.

    How to Read Core Dump in Linux

    To read a core dump, we use:

    GDB — the GNU Debugger

    Install it:

    sudo apt install gdb
    

    or on Arch:

    sudo pacman -S gdb
    

    GDB Core Dump Analysis in Linux: Step-by-Step

    Run:

    gdb <executable> <core-file>
    

    Example:

    gdb ./myapp core.1234
    

    GDB will open and show the reason for the crash.

    Then type:

    bt
    

    This gives the backtrace (stack trace).

    You’ll see something like:

    #0  0x00007ffff7a543d7 in strcpy () from /lib64/libc.so.6
    #1  0x000000000040113d in main () at main.c:12
    

    This tells you:

    • exact line number where crash happened
    • which function caused it
    • how the call chain reached there

    This is the heart of core dump Linux analysis.

    Read Full Tutorial about GDB here : GDB GNU Debugger

    Understanding the Backtrace (Stack Trace)

    Let’s decode what the backtrace is telling you.

    Every line usually shows:

    #frame_number  memory_address in function_name (args) at file:line
    

    Example Breakdown

    #0  0x00007ffff7a543d7 in strcpy () from /lib64/libc.so.6
    

    Meaning:

    • Frame #0 → This is where the crash occurred
    • strcpy() → Crashed inside a standard library function
    • You passed invalid memory to strcpy → likely a buffer overflow

    Next line:

    #1  0x000000000040113d in main () at main.c:12
    

    This tells you your own app called strcpy in a wrong way at line 12.

    This gives you a clear direction to fix the crash.

    How to Analyse Core Dump in Linux Using GDB (Deeper Walkthrough)

    Inside GDB, here are essential commands:

    1. Print the crash reason

    info signals
    

    2. Print local variables

    info locals
    

    3. Print function arguments

    info args
    

    4. Move up and down stack frames

    up
    down
    

    5. Print a variable

    print var
    

    6. Disassemble crashing function

    disassemble
    

    7. Show source code

    list
    

    This is the core of crash dump analysis in Linux.

    Memory Dump Analyzer Linux Tools (Extra Useful Tools)

    Other than GDB, Linux developers often use:

    1. valgrind

    To detect memory corruption.

    valgrind ./myapp
    

    2. addr2line

    Convert addresses to line numbers.

    addr2line -e myapp 0x40113d
    

    3. readelf / objdump

    View symbol tables.

    4. systemd-coredump (Arch, Fedora)

    Handles central core dump storage.

    Common Reasons Why Core Dump Is Not Generated

    If you can’t find a core dump, check:

    1. ulimit -c is 0

    Core dumps disabled.

    2. Application is setuid

    Linux blocks core dumps for security.

    3. No write permission

    Directory not writable.

    4. systemd storing core dumps

    Run:

    coredumpctl list
    

    5. core_pattern is piped

    Example:

    |/usr/share/apport/apport %p %s %c %P %u %g %t %e
    

    Means it’s handled by a crash reporter.

    Full Example: From Crash to Debugging

    Let’s say your C program crashes with:

    Segmentation fault (core dumped)
    

    Step 1: Check for core dump

    ls core*
    

    Step 2: Open in GDB

    gdb ./a.out core
    

    Step 3: View backtrace

    bt
    

    Output:

    #0  main.c:14
    

    Step 4: Inspect variables

    info locals
    

    You’ll immediately see the reason.

    This is the simplest form of core dump in Linux debugging.

    Core Dump on Arch Linux

    Since many Arch Linux users ask specifically about this:

    • Arch uses systemd-coredump
    • Core files are stored in journal, not filesystem

    Check:

    coredumpctl list
    

    Analyze:

    coredumpctl gdb
    

    This is why many newcomers can’t find the actual core file in Arch Linux.

    Commands Summary (Quick Cheat Sheet)

    Check if core dumps are enabled

    ulimit -c
    

    Enable core dumps

    ulimit -c unlimited
    

    Set core dump location

    echo "/var/core/core.%e.%p" | sudo tee /proc/sys/kernel/core_pattern
    

    Force a core dump

    gcore <PID>
    

    Analyze using GDB

    gdb <exe> <core>
    bt
    

    Arch Linux

    coredumpctl list
    coredumpctl gdb
    

    Why Every Developer Should Know Core Dumps

    Whether you’re a beginner or an experienced engineer, knowing how to analyze core dump in Linux gives you superpowers.

    Core dumps help you:

    • Debug crashes even when you can’t reproduce them
    • Understand memory corruption
    • Debug server crashes after the fact
    • Reverse-engineer program behavior
    • Fix production bugs quickly

    It’s one of the most important skills in systems programming.

    Below is a complete real-world C++ example where we:

    1. Write a buggy C++ program
    2. Compile it
    3. Enable + generate a core dump
    4. Analyze the core dump using GDB (step-by-step)
    5. Show the exact backtrace + explanation

    1. C++ Program That Intentionally Crashes (Bug Inside)

    Save this file as: crash.cpp

    #include <iostream>
    #include <cstring>
    
    void copyString(const char* src) {
        char buffer[5];  // BUG: buffer too small
        std::strcpy(buffer, src);  // This will overflow
        std::cout << "Copied: " << buffer << std::endl;
    }
    
    int main() {
        const char* text = "HelloWorld";  // 10 characters → overflow
        copyString(text);
        return 0;
    }
    

    Why this crashes?

    buffer can hold only 5 bytes, but HelloWorld is 10 bytes, causing a buffer overflow → segmentation fault → core dumped.

    2. Compile the Program (with debug symbols)

    g++ -g crash.cpp -o crash
    

    -g is important — it helps GDB show exact line numbers.

    3. Enable Core Dump in Linux

    Check first:

    ulimit -c
    

    If result is 0, enable core dump:

    ulimit -c unlimited
    

    4. Run the Program to Generate Core Dump

    ./crash
    

    You will get:

    Segmentation fault (core dumped)
    

    Now list core file:

    ls -l core*
    

    You may see:

    core
    

    or

    core.12345
    

    5. Analyze the Core Dump Using GDB

    Run:

    gdb ./crash core
    

    Now GDB opens the crash snapshot.

    6. Get the Stack Trace (Backtrace)

    Inside gdb, type:

    bt
    

    You will see output similar to:

    #0  0x00007ffff7a543d7 in __strcpy_sse2_unaligned () from /lib64/libc.so.6
    #1  0x0000000000401178 in copyString (src=0x400804 "HelloWorld") at crash.cpp:7
    #2  0x000000000040119f in main () at crash.cpp:13
    

    7. Understanding the Backtrace (Line-by-Line Analysis)

    Let’s break this down like a human:

    Frame #0

    #0  __strcpy_sse2_unaligned
    

    This tells us the actual crash happened inside the C library’s strcpy() function.

    strcpy() crashed because it tried writing beyond buffer limits.

    Frame #1

    copyString (src="HelloWorld") at crash.cpp:7
    

    Line 7 in crash.cpp:

    std::strcpy(buffer, src);
    

    This is the exact buggy line.

    Frame #2

    main () at crash.cpp:13
    

    Line 13:

    copyString(text);
    

    This shows the call chain:

    main → copyString → strcpy → crash
    

    This is the exact purpose of core dump analysis in Linux — finding how and where your program died.

    8. Inspect Variables at Time of Crash

    Inside gdb:

    See local variables:

    info locals
    

    You may see:

    buffer = "Hello"   (truncated)
    src = 0x400804 "HelloWorld"
    

    This tells you:

    • buffer was too small
    • src was a long string
    • strcpy overflowed and crashed

    9. Inspect Function Arguments

    info args
    

    Output:

    src = 0x400804 "HelloWorld"
    

    Perfect — now you know what was passed to the crashing function.

    10. View the Source Code in GDB

    list
    

    You’ll see the source around the crash location.

    Final Crash Explanation (Human-Friendly)

    Your C++ program crashed because:

    • You created a tiny 5-byte buffer
    • You used strcpy which does no size-checking
    • You copied a 10-byte string
    • Memory overflowed → segmentation fault
    • Linux created a core dump
    • GDB helped you view the exact line that caused the crash

    This is exactly how developers perform core dump analysis in Linux.

    FAQ: Core Dump in Linux

    1. What is a core dump in Linux, and why is it created?

    A core dump in Linux is a snapshot of a program’s memory at the exact moment it crashes.
    It helps developers understand what went wrong—like a crime-scene photo of your software.

    The core file contains:

    • Registers
    • Stack memory
    • Heap memory
    • Function call history (backtrace)
    • Values of variables

    This is why crash dump analysis in Linux is essential while debugging segmentation faults, buffer overflows, or memory corruption bugs.

    2. How do I check if core dump is enabled in Linux?

    You can verify this using:

    ulimit -c
    
    • If you see 0, core dumps are disabled.
    • If you see unlimited, core dumps are enabled.

    This is the simplest way for how to check if core dump is enabled in Linux.

    3. How do I enable core dump in Linux permanently?

    To enable core dump in Linux, you can either do it temporarily or permanently.

    For permanent enablement, edit:

    /etc/security/limits.conf
    

    Add:

    * soft core unlimited
    * hard core unlimited
    

    Then configure where the system stores core files:

    echo "/var/core/core.%e.%p" | sudo tee /proc/sys/kernel/core_pattern
    

    Now core dumps will always be generated and saved predictably.

    4. Where do I find the core dump in Linux?

    Core dumps may appear in different places depending on settings.

    Common locations:

    1. Current working directory (core or core.PID)
    2. /var/core (if configured with core_pattern)
    3. /tmp
    4. Using systemd-coredumpctl on modern distros like Arch Linux, Fedora, Ubuntu

    If you use Arch, the core file will not appear on disk. Instead, use:

    coredumpctl list
    

    This is why people struggle with core dump Arch Linux behavior.

    5. How do I read a core dump in Linux?

    You use the GDB debugger.

    Example:

    gdb ./myapp core
    

    Then get the backtrace:

    bt
    

    This shows:

    • where the crash occurred
    • which function caused it
    • the entire call stack

    This is called gdb core dump analysis in Linux, the standard method used by professionals.

    6. How do I analyze core dump in Linux using GDB step-by-step?

    Here’s the exact workflow for how to analyse core dump in Linux using gdb:

    gdb <executable> <core-file>
    

    Inside GDB:

    • bt → backtrace
    • info locals → local variables
    • info args → function arguments
    • list → show source code
    • up / down → navigate stack frames

    This shows you the exact line and variable values that caused the crash.

    7. What is the command to generate core dump in Linux manually?

    Use:

    gcore <PID>
    

    This is the official command to generate core dump in Linux without crashing the program.

    Useful for:

    • debugging stuck processes
    • analyzing deadlocks
    • freezing memory state for investigation

    8. How do I collect core dump in Linux for a background or server process?

    You can force a core dump with:

    kill -SIGSEGV <PID>
    

    Or use:

    gcore <PID>
    

    This is the answer to how to collect core dump in Linux when dealing with server applications or daemons.

    9. How do I check core dump patterns and storage settings?

    Run:

    cat /proc/sys/kernel/core_pattern
    

    This shows:

    • the naming format
    • whether a crash reporter is intercepting dumps
    • whether the system is piping the core dump to systemd

    If you see something starting with |, then Linux is piping core dumps to a program.
    This is common in Ubuntu and Arch Linux with systemd-coredump.10. Why does Linux sometimes not generate core dumps?

    Some common reasons:

    • ulimit -c is 0
    • Application is setuid (security restriction)
    • Directory has no write permission
    • Systemd captures core dumps instead of writing files
    • App is running inside a container (needs special config)

    Fixing these ensures how to get core dump in Linux always works.

    11. How to do memory dump analysis in Linux?

    Aside from GDB, Linux developers often use:

    Useful Tools:

    • valgrind → memory corruption detection
    • addr2line → convert crash addresses to code lines
    • objdump → disassembly
    • readelf → ELF structure
    • systemd-coredumpctl → manage dumps in Arch/Ubuntu

    All these help with memory dump analyzer Linux workflows.

    12. What is core dump Linux analysis and why is it important?

    Core dump Linux analysis is the process of:

    1. Opening the core file
    2. Recreating program state at crash time
    3. Viewing the backtrace
    4. Inspecting variables
    5. Understanding memory state

    It is essential for:

    • debugging production crashes
    • diagnosing segmentation faults
    • analyzing memory corruption
    • ensuring software stability

    This is the main reason companies heavily rely on core dump analysis in Linux before shipping products.

    13. How do I generate a core dump in Linux for testing?

    If you want to practice:

    echo "test" > /dev/null
    kill -SIGSEGV $$
    

    Or write a simple C/C++ program that intentionally crashes.

    This helps beginners learn how to generate core dump in Linux safely.

    14. Does Arch Linux handle core dumps differently?

    Yes.
    Arch Linux uses systemd-coredump, which stores dumps in the journal instead of writing core files on disk.

    View stored dumps:

    coredumpctl list
    

    Analyze directly with:

    coredumpctl gdb
    

    This is the standard workflow for core dump Arch Linux users.

    15. How do I get the stack trace from a core dump in Linux?

    You simply open the core dump using GDB:

    gdb ./a.out core
    

    Then:

    bt
    

    This prints the backtrace, which includes:

    • crash location
    • call chain
    • function order
    • line numbers

    Backtrace = the heart of how to analyze core dump in linux.

    16. How do I fix “Segmentation fault (core dumped)” errors?

    You fix them by:

    • enabling core dumps
    • analyzing the core file
    • identifying buffer overflow or illegal memory access
    • correcting logic errors in your C/C++ code

    Using a core dump in Linux is the cleanest way to find the exact cause of a segmentation fault.

    17. What is the best way for beginners to learn core dump debugging?

    Start simple:

    1. Write a small C/C++ program
    2. Cause a segmentation fault
    3. Enable core dump
    4. Analyze using GDB
    5. Understand the backtrace step-by-step

    This hands-on approach teaches everything from how to read core dump in linux to gdb core dump analysis in linux.

  • Swap Using XOR: 7 Powerful and Easy Techniques Explained for Beginners

    Swapping two variables is one of the fundamental operations in programming. Most developers learn the traditional method first — using a temporary variable. However, there is a more efficient and mathematically elegant technique: swap using XOR.

    This method allows you to exchange the values of two variables without using any extra memory, relying entirely on the properties of the bitwise XOR operator. It is simple, reliable, and works across all popular programming languages including C, C++, Java, and Python.

    Whether you are preparing for technical interviews, studying low-level programming, or improving your understanding of bitwise operations, learning swap using XOR gives you deeper insights into how computers manipulate data at the binary level.ons.

    What Is XOR? A Simple Explanation

    Before we jump into swapping, let’s understand the hero behind the trick: XOR.

    XOR means Exclusive OR.

    It behaves like this:

    • If two bits are different → output is 1
    • If two bits are the same → output is 0

    Truth table:

    ABA ^ B
    000
    011
    101
    110

    So XOR literally says:

    “I only return 1 if the two bits disagree.”

    This weird little behaviour is exactly what makes swap using xor possible.

    How XOR Makes Swapping Possible (The Real Magic)

    Let’s say:

    a = 5  
    b = 7
    

    Binary:

    a = 0101  
    b = 0111
    

    We perform:

    1. a = a ^ b
    2. b = a ^ b
    3. a = a ^ b

    Let’s break it down.

    Step 1

    a = a ^ b
    Now a becomes some weird mix of both.

    Step 2

    b = a ^ b
    Now b becomes original a.

    Step 3

    a = a ^ b
    Now a becomes original b.

    No temp variable.
    Just pure bitwise logic.

    This method is also called:

    • xor swap algorithm
    • swap using bitwise xor
    • swap two numbers using bitwise xor operator
    • swap with xor
    • xor to swap two variables
    • swap two values xor

    Everything means the same technique.

    Why XOR Swap Works?

    Because XOR has two beautiful properties:

    Rule 1

    x ^ x = 0
    

    Rule 2

    x ^ 0 = x
    

    Rule 3

    x ^ y ^ y = x
    

    This third rule is the secret behind the algorithm.

    Basic Example of swap using xor

    Let’s take:

    a = 10  
    b = 20
    

    Perform:

    a = a ^ b  
    b = a ^ b  
    a = a ^ b  
    

    Result?

    a = 20  
    b = 10
    

    Clean, fast, no memory required.

    This is the essence of swap 2 numbers using xor.

    Swap Using XOR in C (swap using xor in c)

    #include <stdio.h>
    
    int main() {
        int a = 5, b = 7;
    
        printf("Before swap: a=%d, b=%d\n", a, b);
    
        a = a ^ b;
        b = a ^ b;
        a = a ^ b;
    
        printf("After swap: a=%d, b=%d\n", a, b);
    
        return 0;
    }
    

    Swap Using XOR in C++ (swap using xor in cpp)

    #include <iostream>
    using namespace std;
    
    int main() {
        int a = 10, b = 20;
    
        cout << "Before swap: a=" << a << " b=" << b << endl;
    
        a = a ^ b;
        b = a ^ b;
        a = a ^ b;
    
        cout << "After swap: a=" << a << " b=" << b << endl;
    
        return 0;
    }
    

    Swap Using XOR in Java (swap using xor java)

    public class Main {
        public static void main(String[] args) {
            int a = 15, b = 25;
    
            System.out.println("Before swap: a=" + a + ", b=" + b);
    
            a = a ^ b;
            b = a ^ b;
            a = a ^ b;
    
            System.out.println("After swap: a=" + a + ", b=" + b);
        }
    }
    

    Swap Using XOR in Python (swap using xor in python)

    a = 8
    b = 12
    
    print("Before swap:", a, b)
    
    a = a ^ b
    b = a ^ b
    a = a ^ b
    
    print("After swap:", a, b)
    

    Write a Program to Swap Two Numbers Using Bitwise XOR (General Pattern)

    a = a ^ b  
    b = a ^ b  
    a = a ^ b
    

    Works in all languages.

    Understanding XOR Swap at Binary Level

    Let’s go deeper.

    Imagine:

    a = 13 → 1101  
    b = 9  → 1001
    

    Step 1

    a = a ^ b

    1101  
    1001  
    ---- XOR  
    0100  (a becomes 4)
    

    Step 2

    b = a ^ b

    0100  
    1001  
    ---- XOR  
    1101 (b becomes 13)
    

    Step 3

    a = a ^ b

    0100  
    1101  
    ---- XOR  
    1001 (a becomes 9)
    

    Swap done.

    Swap Bytes Using XOR

    This is commonly used in low-level programming:

    unsigned char x = 0xAB;
    unsigned char y = 0xCD;
    
    x ^= y;
    y ^= x;
    x ^= y;
    

    Now x=CD and y=AB.

    Useful in:

    • Embedded systems
    • Compiler optimization
    • Cryptography
    • System programming
    • Memory manipulation

    Swap a and b Using XOR

    Let’s take:

    a = 3  
    b = 4
    

    After performing XOR swap:

    a = 4  
    b = 3
    

    This satisfies:

    • swap a and b using xor
    • xor to swap two variables
    • swap two values xor
    • swap variables with xor

    Where XOR Swap Is Used in Real Life?

    Most modern compilers optimize swaps easily, so XOR is rarely used in normal application code. But XOR swap is useful:

    • In interview coding rounds
    • In extremely tight memory environments
    • When working inside registers
    • In embedded systems
    • In microcontroller code
    • In cryptographic functions
    • When swapping bytes in buffers

    When NOT to Use XOR Swap

    Even though this technique is cool, it is NOT always optimal.

    Case 1: If a and b refer to the same memory location

    a = a ^ a → becomes zero → data loss

    Case 2: Harder to read than temp-variable swap

    temp = a; a = b; b = temp;
    

    is easier to understand.

    Case 3: Modern compilers handle temp-swap better

    Optimization makes XOR swap unnecessary.

    Interview Tips: How to Explain XOR Swap

    Interviewers often ask:

    1. How to swap using xor?
    2. How to swap two numbers using xor?
    3. Why xor swap algorithm works?
    4. Can we swap without a temporary variable?

    Your answer:

    “Yes, we can swap two numbers using XOR. The XOR swap algorithm uses three XOR operations. It relies on the identity x ^ y ^ y = x. It saves temporary memory but is less readable and modern compilers optimize normal swaps well.”

    Perfect explanation.

    Comparison: XOR Swap vs Temp Swap

    FeatureXOR SwapTemp Swap
    Uses extra variableNoYes
    ReadabilityLowHigh
    SpeedSame on most CPUsSame
    RiskHigh (if a=b)Zero
    Practical useRareCommon

    More Swap Examples Using XOR

    1. Swap using xor operator in C

    a ^= b  
    b ^= a  
    a ^= b
    

    2. Swap using xor operator in C++

    Same as above.

    3. Swap using xor java

    Same logic with ^ operator.

    4. Swap using xor in python

    Python has native tuple swap, but XOR swap still works.

    Edge Cases in XOR Swap

    1. Swapping same variables

    a = a ^ a = 0
    

    Data destroyed.

    2. Floating-point swap

    Does NOT work. XOR is for integers.

    3. Boolean swap

    Works but pointless.

    Full Example: swap two numbers using xor in C++

    int a = 100;
    int b = 200;
    
    a = a ^ b;
    b = a ^ b;
    a = a ^ b;
    

    Full Example: swapping of two numbers using xor in C

    int a = 44, b = 99;
    a ^= b;
    b ^= a;
    a ^= b;
    

    Full Example: swap two numbers using xor in python

    a, b = 4, 5
    a = a ^ b
    b = a ^ b
    a = a ^ b
    

    Is XOR Swap Faster Than Normal Swap?

    Honestly? No.

    Modern CPUs use registers to optimize swaps. Compilers often convert:

    temp = a;
    a = b;
    b = temp;
    

    into register operations faster than XOR.

    So XOR swap is just a cool trick, not a performance hack.

    Advantages of XOR Swap

    • Saves memory (no temp variable)
    • Works in all languages
    • Fun interview trick
    • Makes you understand bitwise logic deeper

    Disadvantages of XOR Swap

    • Harder to read
    • Dangerous when both variables refer to same memory
    • Slower on some architectures
    • Not suitable for floating values
    • Compilers already optimize temp-swaps

    Real-World Usage of XOR Swap

    • Microcontrollers
    • Kernel-level code
    • Cryptography
    • Data compression
    • Embedded system optimization
    • Low-level audio/video DSP

    Summary

    Here’s the simplest summary:

    XOR swap is a clever way to swap two integers without using a temporary variable. It relies on XOR properties. It works, but it is rarely used in real production code due to readability and optimization issues.

    FAQ

    1. What is swap using XOR?

    A method to swap two integers without using a temporary variable using bitwise XOR.

    2. How to swap two numbers using XOR?

    Use three XOR operations:
    a = a ^ b; b = a ^ b; a = a ^ b;

    3. Why does XOR swap algorithm work?

    Because XOR is reversible: x ^ y ^ y = x.

    4. Can swap using XOR be written in C?

    Yes, and it is commonly asked in interviews.

    5. Is XOR swap faster?

    No. Modern CPUs optimize regular swaps better.

    6. Can swap using XOR be used in Python?

    Yes, but Python’s a, b = b, a is better.

    7. Is it safe to use XOR swap?

    Not completely. If a and b refer to same memory, data becomes zero.

    8. Can XOR swap handle floats?

    No. Only integers.

    9. Should I use XOR swap in production code?

    No. It’s mainly educational or for interviews.

    10. Is XOR swap used in embedded systems?

    Yes, sometimes, especially in memory-tight environments.

    11. Can I swap bytes using XOR?

    Yes. It is used in byte-level optimizations.

    12. Is XOR swap useful in competitive programming?

    Sometimes, but readability matters more.

    Conclusion

    Swapping values is one of the first things we learn in programming. But swap using XOR teaches you something deeper — how computers think in bits.

    It’s not just a trick to avoid using a temporary variable.
    It’s a doorway to understanding bitwise operations, CPU behavior, and low-level programming.

    Even though we don’t use XOR swap much in real-world application code, it remains one of the coolest concepts every programmer should know.

    Now you know:

    • How XOR works
    • How to perform variable swap using xor
    • How to swap two numbers using xor in C, C++, Java, Python
    • How xor swap algorithm actually functions
    • When to use it
    • When NOT to use it
    • Why understanding bits matters

    And most importantly…
    You now fully understand the secret behind one of the oldest programming tricks ever invented.

    If someone now asks you,
    “Do you know how to swap without a temporary variable?”
    just smile and say:
    “Yes , using XOR.”