Author: admin

  • C++ Constructors and Destructors: The Complete Guide from Beginner to Advanced

    Learn C++ Constructors and Destructors from scratch. Covers types, syntax, memory management, virtual destructors, and real interview questions. Perfect for beginners.

    If you have ever wondered how a C++ object gets its initial values the moment it is created, or how memory gets cleaned up the moment an object dies you are about to understand exactly that. Constructors and destructors are the two most fundamental concepts in C++ object-oriented programming, and honestly, once you really get them, a huge chunk of C++ starts making sense.

    This guide covers everything: basic syntax, all types of constructors, destructor behavior, memory management, advanced topics like virtual destructors, move semantics, Rule of 3 and Rule of 5, RAII, smart pointers, and interview questions. Whether you are just starting out or preparing for a senior C++ interview, stick around this is the only article you will need.

    Let’s get into it.

    1. What is a Constructor in C++?

    A constructor is a special member function of a class that gets called automatically whenever you create an object of that class. Think of it like a setup function that runs by itself you never have to call it explicitly.

    Its main job is to initialize the data members of the object to valid starting values. Without a constructor, your object’s variables would hold garbage values (whatever junk was sitting in memory at that address), and that leads to unpredictable bugs.

    Here is a simple mental model: imagine you buy a new notebook. The moment it comes out of the box, it already has your name written on the first page and the date stamped on the cover. Nobody asked you to do that manually the manufacturer set it up. That’s a constructor.

    
    #include <iostream>
    using namespace std;
    
    class Student {
    public:
        string name;
        int age;
    
        // This is the constructor
        Student() {
            name = "Unknown";
            age = 0;
            cout <<"Constructor called!" <<endl;
        }
    };
    
    int main() {
        Student s1; // Constructor is called automatically here
        cout &lt;&lt; s1.name &lt;&lt; ", " &lt;&lt; s1.age &lt;&lt; endl;
        return 0;
    }
    

    Output:

    
    Constructor called!
    Unknown, 0
    

    Notice : you did not write s1.Student() anywhere. It just ran on its own when the object was created.

    2. What is a Destructor in C++?

    A destructor is the opposite side of the coin. It is also a special member function, but it runs automatically when an object is destroyed — when it goes out of scope, or when you use delete on a dynamically allocated object.

    The destructor’s job is cleanup: releasing dynamically allocated memory, closing file handles, releasing network connections, or anything else that needs to be undone when the object’s life ends.

    Back to the notebook analogy: when you are done with the notebook and throw it away, someone shreds your personal information inside. You didn’t manually ask for that — it just happens as part of disposal. That’s a destructor.

    
    #include &lt;iostream&gt;
    using namespace std;
    
    class Student {
    public:
        Student() {
            cout &lt;&lt; "Constructor called — object is being created." &lt;&lt; endl;
        }
    
        ~Student() { // The tilde ~ marks a destructor
            cout &lt;&lt; "Destructor called — object is being destroyed." &lt;&lt; endl;
        }
    };
    
    int main() {
        Student s1; // Constructor called here
        cout &lt;&lt; "Inside main..." &lt;&lt; endl;
        // Destructor called automatically when s1 goes out of scope
        return 0;
    }
    

    Output:

    
    Constructor called — object is being created.
    Inside main...
    Destructor called — object is being destroyed.
    

    This automatic call behavior is what makes C++ so powerful for resource management — and also what trips up beginners when they don’t understand the object lifecycle.

    3. Why Do We Need Constructors and Destructors?

    Need of Constructor

    • Initialization guarantee: Without a constructor, data members start with garbage values. Constructors ensure objects are always in a valid state from the start.
    • Automatic execution: You cannot forget to call a constructor. It always runs when an object is created.
    • Encapsulation: You can enforce rules (like “age must be positive”) inside a constructor and reject bad input.
    • Resource acquisition: Constructors are the right place to open files, allocate memory, or initialize hardware.

    Need of Destructor

    • Prevent memory leaks: If you allocate memory with new inside a constructor, you need the destructor to call delete. Otherwise that memory leaks.
    • Resource release: File handles, database connections, mutex locks — all need to be released when an object is done.
    • Automatic and reliable: C++ guarantees the destructor is called when scope ends, even if an exception is thrown. This is the entire foundation of RAII, which we’ll cover later.

    In languages like Python or Java, garbage collectors handle some of this automatically. C++ gives you direct control — more power, more responsibility. The constructor and destructor pair is how you exercise that responsibility correctly.

    4. Basic Syntax of Constructor and Destructor

    Constructor Syntax Rules

    • Same name as the class
    • No return type — not even void
    • Can be overloaded (multiple constructors with different parameters)
    • Can have default arguments
    
    class ClassName {
    public:
        ClassName() {           // Default constructor
            // initialization
        }
    
        ClassName(int x) {      // Parameterized constructor
            // initialization using x
        }
    
        ClassName(const ClassName&amp; obj) { // Copy constructor
            // copy from obj
        }
    };
    

    Destructor Syntax Rules

    • Same name as the class, preceded by a tilde ~
    • No return type
    • No parameters — cannot be overloaded
    • Only one destructor per class
    
    class ClassName {
    public:
        ~ClassName() {
            // cleanup code
        }
    };
    

    5. Characteristics of Constructor and Destructor

    Characteristics of Constructor

    • Automatically called when an object is created
    • Can be overloaded — multiple constructors allowed
    • Can use default arguments
    • Can call other constructors (delegating constructors in C++11)
    • Can be inline, explicit, or private
    • Cannot be virtual (but derived class constructors can be called through base class pointers via virtual functions)
    • Cannot have a return type
    • Inherited classes get their own constructors — base class constructor is not inherited directly

    Characteristics of Destructor

    • Automatically called when an object goes out of scope or is deleted
    • Cannot be overloaded — only one destructor per class
    • Takes no arguments
    • Can and should be virtual in base classes used with polymorphism
    • Cannot be static
    • Called in reverse order of construction in case of multiple objects
    • Can throw exceptions only within the destructor body (but it is strongly discouraged)

    6. Constructor vs Normal Function | Constructor vs Destructor

    Constructor vs Normal Member Function

    FeatureConstructorNormal Function
    NameMust match class nameAny valid identifier
    Return typeNoneMust have one (even void)
    Called byCompiler automaticallyProgrammer explicitly
    PurposeInitialize objectAny operation
    OverloadingYesYes
    virtual keywordCannot be virtualCan be virtual

    Constructor vs Destructor : Basic Difference

    FeatureConstructorDestructor
    PurposeInitialize objectClean up object
    Called whenObject is createdObject is destroyed
    ParametersCan have parametersCannot have parameters
    OverloadingAllowedNot allowed
    Count per classMultiple allowedOnly one
    PrefixNoneTilde (~)
    Virtual keywordCannot be virtualCan (and should) be virtual
    Execution orderBase → DerivedDerived → Base

    7. Types of Constructors in C++

    7.1 Default Constructor

    A default constructor takes no arguments. If you don’t write any constructor, the compiler generates one automatically but it won’t initialize primitive types like int or double to any specific value. Writing your own default constructor is almost always the right call.

    
    class Box {
    public:
        int length, width, height;
    
        Box() { // Default constructor
            length = 1;
            width = 1;
            height = 1;
        }
    };
    
    int main() {
        Box b; // Calls default constructor
        return 0;
    }
    

    7.2 Parameterized Constructor

    This takes arguments so you can initialize an object with specific values at the time of creation. Much more flexible than a default constructor.

    
    class Box {
    public:
        int length, width, height;
    
        Box(int l, int w, int h) { // Parameterized constructor
            length = l;
            width = w;
            height = h;
        }
    };
    
    int main() {
        Box b1(10, 5, 3);
        Box b2(7, 7, 7);
        return 0;
    }
    

    7.3 Copy Constructor

    A copy constructor creates a new object as a copy of an existing one. It takes a reference to an object of the same class. If you don’t write one, the compiler gives you a default copy constructor that copies all members one-by-one — which is fine for simple types but causes serious problems with dynamically allocated memory (shallow copy issue).

    
    class Box {
    public:
        int length;
    
        Box(int l) { length = l; }
    
        Box(const Box&amp; obj) { // Copy constructor
            length = obj.length;
            cout &lt;&lt; "Copy constructor called" &lt;&lt; endl;
        }
    };
    
    int main() {
        Box b1(10);
        Box b2 = b1; // Copy constructor called here
        Box b3(b1);  // Same ->  copy constructor called
        return 0;
    }
    

    Copy constructors are triggered in three situations: when initializing a new object from an existing one, when passing an object by value to a function, and when returning an object by value from a function.

    7.4 Dynamic Constructor

    A dynamic constructor allocates memory on the heap using new inside the constructor body. This is used when the size of data is not known at compile time.

    
    class DynamicArray {
        int* arr;
        int size;
    
    public:
        DynamicArray(int n) {
            size = n;
            arr = new int[n]; // Dynamic allocation inside constructor
            for (int i = 0; i &lt; n; i++) arr[i] = 0;
        }
    
        ~DynamicArray() {
            delete[] arr; // Must release in destructor
        }
    };
    

    7.5 Constructor with Default Arguments

    You can give constructor parameters default values, making them optional. This lets one constructor serve the role of both a default and parameterized constructor.

    
    class Box {
    public:
        int length, width;
    
        Box(int l = 1, int w = 1) { // Default arguments
            length = l;
            width = w;
        }
    };
    
    int main() {
        Box b1;       // Uses defaults: 1, 1
        Box b2(5);    // l=5, w=1
        Box b3(5, 8); // l=5, w=8
        return 0;
    }
    

    8. Intermediate Topics

    8.1 Constructor Overloading

    Just like regular function overloading, you can have multiple constructors in the same class as long as their parameter lists differ. The compiler picks the right one based on the arguments you pass.

    
    class Rectangle {
        int length, width;
    public:
        Rectangle() { length = width = 0; }
        Rectangle(int l) { length = width = l; }
        Rectangle(int l, int w) { length = l; width = w; }
    };
    

    8.2 Passing Objects to Constructor

    You can pass an object of the same (or another) class as a parameter to a constructor. This is common when you want one object to initialize based on another.

    
    class Point {
    public:
        int x, y;
        Point(int a, int b) : x(a), y(b) {}
        Point(const Point&amp; p) : x(p.x), y(p.y) {}
    };
    
    class Line {
        Point start, end;
    public:
        Line(Point s, Point e) : start(s), end(e) {}
    };
    

    8.3 Array of Objects with Constructor

    When you create an array of objects, the default constructor is called for each element. If no default constructor exists, the compiler will give an error.

    
    class Student {
    public:
        int roll;
        Student() { roll = 0; } // Required for array creation
    };
    
    int main() {
        Student arr[5]; // Default constructor called 5 times
        return 0;
    }
    

    8.4 Order of Constructor and Destructor Execution

    This is something that trips up a lot of programmers. The rule is simple: constructors are called in the order objects are created; destructors are called in reverse order.

    
    class A {
    public:
        A() { cout &lt;&lt; "A constructor" &lt;&lt; endl; }
        ~A() { cout &lt;&lt; "A destructor" &lt;&lt; endl; }
    };
    
    class B {
    public:
        B() { cout &lt;&lt; "B constructor" &lt;&lt; endl; }
        ~B() { cout &lt;&lt; "B destructor" &lt;&lt; endl; }
    };
    
    int main() {
        A a;
        B b;
        return 0;
    }
    

    Output:

    
    A constructor
    B constructor
    B destructor
    A destructor
    

    Think of it like a stack — last in, first out. This LIFO order is guaranteed by the C++ standard.

    8.5 Constructor in Structures

    Unlike C, C++ structures (struct) are almost identical to classes — the only difference is that members are public by default. This means structures can also have constructors and destructors.

    
    struct Point {
        int x, y;
        Point(int a, int b) : x(a), y(b) {} // Valid in C++
    };
    
    int main() {
        Point p(3, 4);
        cout &lt;&lt; p.x &lt;&lt; ", " &lt;&lt; p.y &lt;&lt; endl;
        return 0;
    }

    Constructor Declared Inside, Defined Outside

    #include <iostream>
    #include <string>
    using namespace std;
    
    class Laptop {
    public:
        string brand;
        string processor;
        int ram;
    
        Laptop(string b, string p, int r); // Declaration only
    };
    
    // Definition outside using scope resolution operator ::
    Laptop::Laptop(string b, string p, int r) {
        brand     = b;
        processor = p;
        ram       = r;
    }
    
    int main() {
        Laptop l1("Dell",   "Intel i7", 16);
        Laptop l2("Apple",  "M2 Pro",   32);
        Laptop l3("Lenovo", "Ryzen 9",  64);
    
        cout << "Brand: " << l1.brand << " | CPU: " << l1.processor << " | RAM: " << l1.ram << "GB\n";
        cout << "Brand: " << l2.brand << " | CPU: " << l2.processor << " | RAM: " << l2.ram << "GB\n";
        cout << "Brand: " << l3.brand << " | CPU: " << l3.processor << " | RAM: " << l3.ram << "GB\n";
    
        return 0;
    }
    

    Output:

    Brand: Dell   | CPU: Intel i7 | RAM: 16GB
    Brand: Apple  | CPU: M2 Pro   | RAM: 32GB
    Brand: Lenovo | CPU: Ryzen 9  | RAM: 64GB
    

    With Initialization List

    // Preferred way — use initialization list instead of assigning in body
    Laptop::Laptop(string b, string p, int r)
        : brand(b), processor(p), ram(r) {
        // body is empty — members already initialized above
    }
    

    Same result, just more efficient and the professional standard in real codebases.

    What Each Part Means

    Laptop :: Laptop (string b, string p, int r)
      |           |
      |           └── Constructor name (same as class)
      └── Class name (which class this belongs to)
     
      :: = scope resolution operator ("belongs to")

    9. Memory and Resource Handling

    9.1 Dynamic Memory Allocation — new and delete

    new allocates memory on the heap at runtime and returns a pointer. delete frees it. This is different from stack memory, which is automatically managed.

    
    int* p = new int(42);    // Allocate single int
    delete p;                // Free it
    
    int* arr = new int[10];  // Allocate array
    delete[] arr;            // Free array (note the brackets)
    

    If you forget delete, that memory leaks — it’s gone, unavailable until your program exits.

    9.2 Constructor with Dynamic Memory

    
    class StringWrapper {
        char* str;
    public:
        StringWrapper(const char* s) {
            str = new char[strlen(s) + 1];
            strcpy(str, s);
        }
    
        ~StringWrapper() {
            delete[] str; // Critical — must free what constructor allocated
        }
    };
    

    9.3 Memory Leak Concept

    A memory leak happens when your program allocates memory but never frees it. Over time, this eats up available RAM. In long-running applications — servers, embedded systems, games — even a small leak per request can eventually crash the system.

    
    void leaky() {
        int* p = new int(10);
        // No delete p; -- this leaks every time leaky() is called
    }
    

    The constructor-destructor pair, used correctly, prevents leaks by design. If the constructor allocates, the destructor deallocates — always.

    9.4 Dangling Pointer Issues

    A dangling pointer points to memory that has already been freed. Accessing it is undefined behavior — your program might crash, output garbage, or seem to work fine (until it doesn’t).

    
    int* p = new int(5);
    delete p;
    // p is now dangling — DO NOT dereference it
    *p = 10; // Undefined behavior — crash or data corruption
    
    // Fix: set pointer to nullptr after delete
    delete p;
    p = nullptr;
    

    This issue is one of the biggest arguments for using smart pointers in modern C++, which we’ll cover in the Modern C++ section.

    10. Advanced Constructor Concepts

    10.1 Constructor Initialization List

    The initialization list is a more efficient way to initialize member variables. It runs before the constructor body, directly constructing members rather than default-constructing then assigning.

    
    class Box {
        int length, width;
        const int MAX; // const members MUST use initialization list
    
    public:
        Box(int l, int w) : length(l), width(w), MAX(100) {
            // Constructor body
        }
    };
    

    There are three situations where the initialization list is not just preferred — it’s required: const members, reference members, and base class constructors.

    10.2 Delegating Constructors (C++11)

    C++11 introduced the ability for one constructor to call another constructor of the same class. This reduces code duplication.

    
    class Box {
        int l, w, h;
    public:
        Box() : Box(1, 1, 1) {} // Delegates to parameterized constructor
    
        Box(int l, int w, int h) : l(l), w(w), h(h) {
            cout &lt;&lt; "Box created: " &lt;&lt; l &lt;&lt; "x" &lt;&lt; w &lt;&lt; "x" &lt;&lt; h &lt;&lt; endl;
        }
    };
    

    10.3 Explicit Constructor

    By default, a single-argument constructor can be used for implicit conversion, which sometimes causes surprising bugs. The explicit keyword prevents this.

    
    class Meters {
        double value;
    public:
        explicit Meters(double v) : value(v) {}
    };
    
    void travel(Meters m) {}
    
    int main() {
        travel(5.0);         // Error: implicit conversion blocked
        travel(Meters(5.0)); // OK: explicit
        return 0;
    }
    

    Use explicit on single-argument constructors unless you specifically want implicit conversion. This is a best practice that prevents hard-to-trace type errors.

    10.4 Inline Constructor

    When you define a constructor inside the class definition, it is implicitly inline — the compiler may expand the call at the call site rather than generating an actual function call, which improves performance for simple constructors.

    
    class Point {
    public:
        int x, y;
        Point(int a, int b) : x(a), y(b) {} // Inline by default
    };
    

    10.5 Static Members and Constructors

    Static data members belong to the class, not to any object. They are initialized once, outside the class definition, and they are not initialized by the constructor.

    
    class Counter {
        static int count;
    public:
        Counter() { count++; }
        ~Counter() { count--; }
        static int getCount() { return count; }
    };
    
    int Counter::count = 0; // Static member initialization (outside class)
    
    int main() {
        Counter a, b, c;
        cout &lt;&lt; Counter::getCount() &lt;&lt; endl; // 3
        return 0;
    }
    

    10.6 Private Constructor and the Singleton Design Pattern

    Making a constructor private prevents external code from creating objects of that class. This is the foundation of the Singleton pattern — a design pattern where only one instance of a class can ever exist.

    
    class Singleton {
        static Singleton* instance;
        Singleton() {} // Private constructor
    
    public:
        static Singleton* getInstance() {
            if (!instance)
                instance = new Singleton();
            return instance;
        }
    };
    
    Singleton* Singleton::instance = nullptr;
    
    int main() {
        Singleton* s1 = Singleton::getInstance();
        Singleton* s2 = Singleton::getInstance();
        cout &lt;&lt; (s1 == s2) &lt;&lt; endl; // 1 (true) — same object
        return 0;
    }
    

    Singleton is used for things like configuration managers, logger objects, or database connection pools where having multiple instances would cause problems.

    10.7 Copy Constructor : Deep Copy vs Shallow Copy

    This is one of the most important concepts in C++ and a very common interview topic.

    Shallow copy (compiler default): copies the pointer address. Both the original and the copy point to the same heap memory. When one is destroyed and frees the memory, the other has a dangling pointer.

    Deep copy (user-defined): allocates new memory and copies the actual data. Each object owns its own independent copy.

    
    class DeepCopy {
        int* data;
    public:
        DeepCopy(int val) {
            data = new int(val);
        }
    
        // Deep copy constructor
        DeepCopy(const DeepCopy&amp; obj) {
            data = new int(*obj.data); // Allocate NEW memory, copy the value
        }
    
        ~DeepCopy() {
            delete data;
        }
    
        int getValue() { return *data; }
    };
    
    int main() {
        DeepCopy d1(10);
        DeepCopy d2 = d1; // Deep copy — d2 has its OWN memory
        *d1.data = 99;
        cout &lt;&lt; d2.getValue() &lt;&lt; endl; // Still 10 — not affected
        return 0;
    }
    

    11. Advanced Destructor Concepts

    11.1 Virtual Destructor

    This is the most important destructor concept for anyone working with inheritance and polymorphism. If you have a base class pointer pointing to a derived class object, and you delete through that base pointer — without a virtual destructor, only the base class destructor runs. The derived class destructor is skipped, causing a memory leak.

    
    class Base {
    public:
        Base() { cout &lt;&lt; "Base constructor" &lt;&lt; endl; }
        virtual ~Base() { cout &lt;&lt; "Base destructor" &lt;&lt; endl; } // virtual!
    };
    
    class Derived : public Base {
        int* data;
    public:
        Derived() {
            data = new int(100);
            cout &lt;&lt; "Derived constructor" &lt;&lt; endl;
        }
        ~Derived() {
            delete data;
            cout &lt;&lt; "Derived destructor" &lt;&lt; endl;
        }
    };
    
    int main() {
        Base* ptr = new Derived();
        delete ptr; // With virtual destructor: both destructors run correctly
        return 0;
    }
    

    Rule of thumb: If a class has even one virtual function, give it a virtual destructor. This costs almost nothing in performance but prevents serious bugs.

    11.2 Pure Virtual Destructor

    You can declare a pure virtual destructor, making the class abstract. Unlike pure virtual functions, a pure virtual destructor must still be defined (because it will be called during object destruction).

    
    class AbstractBase {
    public:
        virtual ~AbstractBase() = 0; // Pure virtual destructor
    };
    
    AbstractBase::~AbstractBase() {
        // Must provide a definition
        cout &lt;&lt; "AbstractBase destructor" &lt;&lt; endl;
    }
    

    11.3 Destructor in Inheritance

    When a derived class object is destroyed, the derived class destructor runs first, followed by the base class destructor. This is always the case, regardless of virtual or not — the difference is whether both run when deleting through a base pointer.

    
    class Animal {
    public:
        ~Animal() { cout &lt;&lt; "Animal destructor" &lt;&lt; endl; }
    };
    
    class Dog : public Animal {
    public:
        ~Dog() { cout &lt;&lt; "Dog destructor" &lt;&lt; endl; }
    };
    
    int main() {
        Dog d; // Output on destruction: "Dog destructor" then "Animal destructor"
        return 0;
    }
    

    11.4 Destructor in Polymorphism and Multiple Inheritance

    In multiple inheritance, destructors are called in the reverse order of base class declaration in the derived class definition. Managing this correctly requires virtual destructors on every base class in the hierarchy.

    
    class A { public: virtual ~A() { cout &lt;&lt; "~A" &lt;&lt; endl; } };
    class B { public: virtual ~B() { cout &lt;&lt; "~B" &lt;&lt; endl; } };
    class C : public A, public B {
    public: ~C() { cout &lt;&lt; "~C" &lt;&lt; endl; } };
    
    int main() {
        C obj;
        // Destruction order: ~C, ~B, ~A
        return 0;
    }
    

    12. OOP Integration : Inheritance, Chaining, and Object Lifecycle

    12.1 Constructor in Inheritance

    When a derived class object is created, the base class constructor is always called first, then the derived class constructor. The derived class must explicitly call the base class constructor if it has parameters; otherwise the default base constructor is used.

    
    class Vehicle {
        int speed;
    public:
        Vehicle(int s) : speed(s) {
            cout &lt;&lt; "Vehicle constructor, speed: " &lt;&lt; speed &lt;&lt; endl;
        }
    };
    
    class Car : public Vehicle {
        string model;
    public:
        Car(int s, string m) : Vehicle(s), model(m) { // Calls base constructor
            cout &lt;&lt; "Car constructor, model: " &lt;&lt; model &lt;&lt; endl;
        }
    };
    
    int main() {
        Car c(120, "Tesla");
        return 0;
    }
    

    Output:

    
    Vehicle constructor, speed: 120
    Car constructor, model: Tesla
    

    12.2 Constructor Chaining

    Constructor chaining is the process of one constructor calling another. In C++, this happens through delegating constructors (within the same class) or through the initialization list (calling the base class constructor).

    12.3 Object Lifecycle in OOP

    Every C++ object goes through a well-defined lifecycle:

    1. Memory allocation — stack or heap
    2. Constructor execution — base then derived
    3. Normal use — object is usable
    4. Destructor execution — derived then base
    5. Memory deallocation — stack auto, heap manual

    Understanding this lifecycle is essential for writing correct C++ programs. Most resource management bugs happen when steps 4 or 5 are done incorrectly.

    13. Special and Edge Cases

    13.1 Can a Constructor be Virtual?

    No. And the reason makes sense when you think about it: virtual functions need a vtable (virtual function table) to work, and the vtable is set up by the constructor. At the time the constructor is running, there is no vtable yet — so making a constructor virtual is a contradiction.

    When creating a derived class object, you know the exact type at compile time, so dynamic dispatch is not needed anyway.

    13.2 Can a Destructor be Static?

    No. A destructor is always associated with a specific instance of the class. Static functions don’t operate on instances — they belong to the class as a whole. So a static destructor makes no conceptual sense, and the compiler will reject it.

    13.3 Constructor Return Type Rules

    Constructors have no return type — not void, not int, nothing. This is by design. A constructor’s job is to initialize an object that already exists (the memory was allocated before the constructor ran). Writing a return type is a syntax error.

    13.4 Destructor with Exceptions

    Throwing an exception from a destructor is almost always a terrible idea. If a destructor throws during stack unwinding (when another exception is already being handled), std::terminate() is called and your program crashes. Mark destructors noexcept and handle errors internally.

    
    class Safe {
    public:
        ~Safe() noexcept {
            try {
                // risky cleanup
            } catch (...) {
                // swallow — never let exception escape destructor
            }
        }
    };
    

    13.5 Default vs User-Defined Constructor

    If you write no constructor at all, the compiler generates a default one. But the moment you write any constructor — including a parameterized one the compiler stops generating the default constructor. If you want both, you have to write both (or use = default).

    
    class Box {
    public:
        Box(int l) {} // Parameterized constructor defined
        // Box() {} // Now you NEED this explicitly if you want Box b;
        Box() = default; // Or use this shorthand
    };
    

    14. Design and Best Practices

    14.1 RAII : Resource Acquisition Is Initialization

    RAII is arguably the most important programming idiom in C++. The idea is simple: tie the lifetime of a resource (memory, file handle, mutex lock, network socket) to the lifetime of an object. Acquire in the constructor, release in the destructor.

    Because C++ guarantees destructors run when scope ends — even when exceptions are thrown — RAII gives you automatic, leak-proof resource management without garbage collection.

    
    class FileHandler {
        FILE* file;
    public:
        FileHandler(const char* name) {
            file = fopen(name, "r");
            if (!file) throw runtime_error("Cannot open file");
        }
    
        ~FileHandler() {
            if (file) fclose(file); // Always runs, even if exception thrown
        }
    
        // ... read methods
    };
    
    void processFile() {
        FileHandler f("data.txt"); // File opened
        // ... do work, throw exception, return early — doesn't matter
        // Destructor ALWAYS closes file when f goes out of scope
    }
    

    RAII is the reason C++ programmers sleep well at night when managing resources. It’s the foundation behind smart pointers, mutex guards, and most of the standard library containers.

    14.2 Rule of Three

    If your class manages a resource (like heap memory) and you need to define one of these three: destructor, copy constructor, or copy assignment operator — then you almost certainly need to define all three. This is the Rule of Three.

    • Destructor: Frees the resource
    • Copy Constructor: Makes a deep copy when initializing from another object
    • Copy Assignment Operator: Makes a deep copy when assigning from another object
    
    class Buffer {
        int* data;
        int size;
    
    public:
        Buffer(int n) : size(n), data(new int[n]) {}
    
        ~Buffer() { delete[] data; } // 1. Destructor
    
        Buffer(const Buffer&amp; other) : size(other.size), data(new int[other.size]) {
            copy(other.data, other.data + size, data); // 2. Copy constructor
        }
    
        Buffer&amp; operator=(const Buffer&amp; other) { // 3. Copy assignment
            if (this != &amp;other) {
                delete[] data;
                size = other.size;
                data = new int[size];
                copy(other.data, other.data + size, data);
            }
            return *this;
        }
    };
    

    14.3 Rule of Five (Modern C++)

    C++11 added move semantics. If your class defines any of the three (destructor, copy constructor, copy assignment), it likely also needs:

    • Move Constructor: Transfers ownership of resources instead of copying
    • Move Assignment Operator: Same for assignment

    Together, these five form the Rule of Five.

    
    Buffer(Buffer&amp;&amp; other) noexcept  // Move constructor
        : data(other.data), size(other.size) {
        other.data = nullptr; // Leave moved-from object safe to destruct
        other.size = 0;
    }
    
    Buffer&amp; operator=(Buffer&amp;&amp; other) noexcept { // Move assignment
        if (this != &amp;other) {
            delete[] data;
            data = other.data;
            size = other.size;
            other.data = nullptr;
            other.size = 0;
        }
        return *this;
    }
    

    14.4 Smart Pointers vs Manual Destructor Management

    In modern C++, you should prefer smart pointers over raw new and delete. Smart pointers are RAII wrappers — their destructor automatically frees the memory.

    • unique_ptr — sole ownership, no copying, moved only
    • shared_ptr — shared ownership, reference counted
    • weak_ptr — non-owning reference to a shared_ptr
    
    #include &lt;memory&gt;
    
    void example() {
        auto p = make_unique&lt;int&gt;(42); // Allocates
        // No delete needed — destructs automatically when p goes out of scope
    
        auto sp = make_shared&lt;string&gt;("hello");
        auto sp2 = sp; // Both point to same string, ref count = 2
        // Memory freed when LAST shared_ptr is destroyed
    }
    

    Smart pointers essentially eliminate entire classes of memory bugs. The Rule of Five matters less when you use smart pointers for all your resources.

    What is a Getter?

    A getter is a function that reads a private member variable and returns its value. You use it to safely access data that is hidden inside the class.

    class Laptop {
    private:
        string brand;   // private — cannot access directly outside
    
    public:
        string getBrand() {   // Getter
            return brand;
        }
    };
    

    What is a Setter?

    A setter is a function that writes or updates a private member variable. You can also add validation logic inside it.

    class Laptop {
    private:
        int ram;
    
    public:
        void setRam(int r) {   // Setter
            if (r > 0)
                ram = r;       // Only set if valid value
            else
                cout << "Invalid RAM value!" << endl;
        }
    };
    

    Why Not Just Make Members Public?

    Great question. Compare these two:

    // BAD — public member, no control
    class Laptop {
    public:
        int ram;
    };
    
    int main() {
        Laptop l;
        l.ram = -999;   // Nobody stops this — garbage value enters
    }
    
    // GOOD — private member with setter validation
    class Laptop {
    private:
        int ram;
    public:
        void setRam(int r) {
            if (r > 0) ram = r;
            else cout << "RAM must be positive!" << endl;
        }
    };
    
    int main() {
        Laptop l;
        l.setRam(-999);  // Rejected — validation kicks in
    }
    

    Setters give you a gatekeeper between outside code and your data.

    Full Example — Constructor + Getter + Setter Together

    #include <iostream>
    #include <string>
    using namespace std;
    
    class Laptop {
    private:
        string brand;
        string processor;
        int ram;
    
    public:
        // Constructor — sets initial values
        Laptop(string b, string p, int r) {
            brand     = b;
            processor = p;
            setRam(r);   // Using setter inside constructor for validation
        }
    
        // Getters — read private data
        string getBrand()     { return brand; }
        string getProcessor() { return processor; }
        int    getRam()       { return ram; }
    
        // Setters — write private data with validation
        void setBrand(string b) {
            if (!b.empty())
                brand = b;
            else
                cout << "Brand cannot be empty!" << endl;
        }
    
        void setProcessor(string p) {
            processor = p;
        }
    
        void setRam(int r) {
            if (r > 0)
                ram = r;
            else
                cout << "Invalid RAM!" << endl;
        }
    };
    
    int main() {
        // Object created using constructor
        Laptop l1("Dell", "Intel i7", 16);
    
        // Reading values using getters
        cout << "Brand     : " << l1.getBrand()     << endl;
        cout << "Processor : " << l1.getProcessor() << endl;
        cout << "RAM       : " << l1.getRam()       << "GB" << endl;
    
        cout << "\n--- Updating values using setters ---\n" << endl;
    
        // Updating values using setters
        l1.setBrand("HP");
        l1.setRam(32);
    
        cout << "Brand     : " << l1.getBrand() << endl;
        cout << "RAM       : " << l1.getRam()   << "GB" << endl;
    
        cout << "\n--- Testing validation ---\n" << endl;
    
        l1.setRam(-8);       // Invalid — rejected
        l1.setBrand("");     // Invalid — rejected
    
        return 0;
    }
    

    Output:

    Brand     : Dell
    Processor : Intel i7
    RAM       : 16GB
    
    --- Updating values using setters ---
    
    Brand     : HP
    RAM       : 32GB
    
    --- Testing validation ---
    
    Invalid RAM!
    Brand cannot be empty!
    

    Where Do They Each Belong in OOP?

    ConceptTopicPurpose
    ConstructorConstructors and DestructorsInitialize object when created
    DestructorConstructors and DestructorsClean up when object is destroyed
    GetterEncapsulationRead private data safely
    SetterEncapsulationWrite private data with control

    How They Work Together

    Constructor  →  sets initial values when object is born
    Getter       →  lets outside code READ private data
    Setter       →  lets outside code UPDATE private data safely
    Destructor   →  cleans up when object dies
    

    Think of it like this — the constructor builds the house, getters let people look through the window, setters control who can enter and what they bring in, and the destructor demolishes the house when it’s no longer needed.

    Move Constructor in C++

    Before jumping into the move constructor itself, you need to understand why it exists because without that context, the syntax looks weird and pointless.

    The Problem : Copying is Expensive

    Imagine you have a class that holds a large chunk of heap memory. When you pass it around or return it from a function, C++ makes a full copy — allocates new memory, copies every single byte. That is slow and wasteful, especially when the original object is a temporary that is going to be thrown away immediately anyway.

    #include <iostream>
    using namespace std;
    
    class BigData {
    public:
        int* data;
        int size;
    
        // Regular constructor
        BigData(int n) {
            size = n;
            data = new int[n];
            for (int i = 0; i < n; i++) data[i] = i;
            cout << "Constructor called — memory allocated" << endl;
        }
    
        // Copy constructor — makes a full duplicate
        BigData(const BigData& obj) {
            size = obj.size;
            data = new int[size];              // New allocation
            for (int i = 0; i < size; i++)
                data[i] = obj.data[i];         // Copy every element
            cout << "Copy constructor — full copy made" << endl;
        }
    
        ~BigData() {
            delete[] data;
            cout << "Destructor called" << endl;
        }
    };
    

    Now when you do this:

    BigData a(1000000);   // 1 million integers allocated
    BigData b = a;        // Full copy — another 1 million integers copied
    

    That copy of 1 million integers is expensive. And if a is a temporary object about to be destroyed anyway — why copy at all? Just steal its memory.

    That is exactly what a move constructor does.

    What is a Move Constructor?

    A move constructor transfers ownership of resources from one object to another instead of copying them. The source object is left in a valid but empty state its pointer is set to nullptr so its destructor does not double-free the memory.

    // Move constructor syntax
    ClassName(ClassName&& obj) noexcept {
        // steal the resources
        // leave obj in safe empty state
    }
    

    The && is called an rvalue reference — it binds to temporary objects that are about to be destroyed.

    lvalue vs rvalue Quick Explanation

    This is the key concept behind move semantics.

    int x = 10;
    // x  → lvalue  — has a name, has an address, persists
    // 10 → rvalue  — temporary, no name, lives only in that expression
    
    BigData a(100);         // a is lvalue — has a name, persists
    BigData b = a;          // copy constructor — a still needed after this
    BigData c = BigData(50);// BigData(50) is rvalue — temporary, dies immediately
                            // move constructor kicks in here
    

    Full Example : Copy vs Move Side by Side

    #include <iostream>
    using namespace std;
    
    class BigData {
    public:
        int* data;
        int  size;
    
        // Regular constructor
        BigData(int n) : size(n), data(new int[n]) {
            for (int i = 0; i < n; i++) data[i] = i;
            cout << "Constructor       — allocated " << n << " integers" << endl;
        }
    
        // Copy constructor — deep copy
        BigData(const BigData& obj) : size(obj.size), data(new int[obj.size]) {
            for (int i = 0; i < size; i++)
                data[i] = obj.data[i];
            cout << "Copy Constructor  — full copy made" << endl;
        }
    
        // Move constructor — steal resources
        BigData(BigData&& obj) noexcept {
            data     = obj.data;    // Steal the pointer
            size     = obj.size;    // Steal the size
            obj.data = nullptr;     // Leave source empty — critical!
            obj.size = 0;
            cout << "Move Constructor  — resources stolen, no copy" << endl;
        }
    
        // Destructor
        ~BigData() {
            delete[] data;          // Safe — nullptr delete does nothing
            cout << "Destructor called" << endl;
        }
    
        void show() {
            if (data)
                cout << "First element: " << data[0] << " | Size: " << size << endl;
            else
                cout << "Object is empty (moved from)" << endl;
        }
    };
    
    int main() {
        cout << "--- Creating a ---" << endl;
        BigData a(5);
    
        cout << "\n--- Copy into b ---" << endl;
        BigData b = a;              // Copy constructor — a still valid
    
        cout << "\n--- Move into c ---" << endl;
        BigData c = move(a);        // Move constructor — a is now empty
    
        cout << "\n--- Checking state ---" << endl;
        b.show();                   // Fine — has its own copy
        c.show();                   // Fine — owns a's original data
        a.show();                   // Empty — resources were moved out
    
        return 0;
    }
    

    Output:

    --- Creating a ---
    Constructor       — allocated 5 integers
    
    --- Copy into b ---
    Copy Constructor  — full copy made
    
    --- Move into c ---
    Move Constructor  — resources stolen, no copy
    
    --- Checking state ---
    First element: 0 | Size: 5
    First element: 0 | Size: 5
    Object is empty (moved from)
    
    Destructor called
    Destructor called
    Destructor called
    

    What is std::move?

    std::move does not actually move anything. It just casts an lvalue to an rvalue reference, telling the compiler:

    “Treat this named object as a temporary — it’s okay to steal from it.”

    BigData a(100);
    BigData b = a;          // Copy — a is still needed
    BigData c = move(a);    // Move — a is being given up intentionally
    // After this: a.data == nullptr, a.size == 0
    // Do NOT use a after moving from it
    

    Copy vs Move : Performance Comparison

    // Without move semantics
    BigData createData() {
        BigData temp(1000000);
        return temp;            // Copies 1 million ints — SLOW
    }
    
    // With move semantics
    BigData createData() {
        BigData temp(1000000);
        return temp;            // Compiler uses move — just pointer transfer — FAST
    }
    

    The compiler is smart enough to apply RVO (Return Value Optimization) and move semantics automatically in many cases. But writing the move constructor yourself ensures it works correctly when the compiler needs it.

    Move Constructor Syntax Breakdown

    BigData(BigData&& obj) noexcept
    //      |       |        |
    //      |       |        └── Promise: this won't throw an exception
    //      |       └── rvalue reference — binds to temporaries
    //      └── Parameter type is the same class
    {
        data     = obj.data;   // Take ownership of the pointer
        size     = obj.size;   // Take the size value
        obj.data = nullptr;    // MUST do this — prevent double delete
        obj.size = 0;          // Leave source in valid empty state
    }
    

    The noexcept is important — standard library containers like std::vector will only use your move constructor during reallocation if it is marked noexcept. Without it, they fall back to copying.

    Where Move Constructor is Called Automatically

    BigData a(10);
    
    // 1. Explicit std::move
    BigData b = move(a);
    
    // 2. Returning a local object from a function
    BigData createData() {
        BigData temp(10);
        return temp;            // Move constructor (or RVO)
    }
    
    // 3. Passing a temporary
    void process(BigData obj) {}
    process(BigData(10));       // Temporary — move constructor used
    
    // 4. Storing in containers
    vector<BigData> v;
    v.push_back(BigData(10));   // Temporary — move constructor used
    

    Move Constructor vs Copy Constructor

    FeatureCopy ConstructorMove Constructor
    Parameterconst ClassName&ClassName&&
    What it doesAllocates new memory, copies dataSteals pointer, sets source to null
    SpeedSlow — O(n) data copyFast — O(1) pointer transfer
    Source object afterUnchanged, fully validEmpty but safe
    When usedCopying a named objectMoving a temporary or std::move
    noexceptOptionalStrongly recommended

    Rule of Five — Where Move Constructor Fits

    If your class manages a resource, you need all five:

    class BigData {
    public:
        BigData(int n);                          // 1. Regular constructor
        ~BigData();                              // 2. Destructor
        BigData(const BigData& obj);             // 3. Copy constructor
        BigData& operator=(const BigData& obj);  // 4. Copy assignment
        BigData(BigData&& obj) noexcept;         // 5. Move constructor  ← this one
        BigData& operator=(BigData&& obj) noexcept; // 6. Move assignment
    };
    

    Move Assignment Operator — Bonus

    Similar to move constructor but for assignment between existing objects:

    BigData& operator=(BigData&& obj) noexcept {
        if (this != &obj) {
            delete[] data;       // Free existing resource first
            data     = obj.data; // Steal
            size     = obj.size;
            obj.data = nullptr;  // Empty source
            obj.size = 0;
        }
        return *this;
    }
    
    BigData a(10);
    BigData b(20);
    b = move(a);    // Move assignment — not move constructor
                    // b already existed, so assignment operator runs
    

    Real Life Analogy

    Think of it like this:

    Copy constructor — You have a USB drive with files. You plug in a new USB and copy all files to it. Both drives now have the same data. Takes time proportional to file size.

    Move constructor — You just hand over the USB drive itself. No copying. Instant. The original drive is now empty — you gave it away.

    Quick Rules to Remember

    • Write a move constructor when your class owns heap memory
    • Always set the source pointer to nullptr after stealing
    • Always mark it noexcept — standard containers depend on it
    • After std::move, treat the source object as empty — do not use it
    • Move constructor is called automatically on temporaries — std::move forces it on named objects
    • If you use smart pointers like unique_ptr, the compiler generates a correct move constructor for free

    15. Modern C++ Topics

    15.1 Move Constructor and Move Semantics

    Move semantics, introduced in C++11, allow you to transfer resources from a temporary (rvalue) object to a new object instead of copying them. This is dramatically more efficient when dealing with large data.

    
    class BigData {
        vector&lt;int&gt; data;
    public:
        BigData(vector&lt;int&gt;&amp;&amp; v) : data(move(v)) {} // Move constructor
    };
    
    int main() {
        vector&lt;int&gt; v(1000000, 1);
        BigData bd(move(v)); // v's data is MOVED, not copied — O(1) instead of O(n)
        return 0;
    }
    

    Without move semantics, returning large objects from functions involved expensive copies. With move semantics, the compiler can transfer ownership of the internal buffer directly — no allocation, no copying.

    15.2 = default and = delete

    = default tells the compiler to generate the default implementation of a special member function. = delete prevents a function from being called — generating a compile error if someone tries to use it.

    
    class NonCopyable {
    public:
        NonCopyable() = default;                             // Use compiler default
        NonCopyable(const NonCopyable&amp;) = delete;            // Disable copying
        NonCopyable&amp; operator=(const NonCopyable&amp;) = delete; // Disable copy assignment
    
        NonCopyable(NonCopyable&amp;&amp;) = default;                // Enable move
        NonCopyable&amp; operator=(NonCopyable&amp;&amp;) = default;     // Enable move assign
    };
    

    This is cleaner and more expressive than the old trick of putting copy constructor in the private section. The = delete approach gives a clear compiler error message.

    15.3 Smart Pointers in Depth

    
    #include &lt;memory&gt;
    #include &lt;iostream&gt;
    using namespace std;
    
    class Resource {
    public:
        Resource() { cout &lt;&lt; "Resource acquired" &lt;&lt; endl; }
        ~Resource() { cout &lt;&lt; "Resource released" &lt;&lt; endl; }
    };
    
    int main() {
        // unique_ptr — single owner
        {
            unique_ptr&lt;Resource&gt; up = make_unique&lt;Resource&gt;();
            // Destructor called automatically at end of block
        }
    
        // shared_ptr — multiple owners
        {
            shared_ptr&lt;Resource&gt; sp1 = make_shared&lt;Resource&gt;();
            {
                shared_ptr&lt;Resource&gt; sp2 = sp1; // ref count = 2
                cout &lt;&lt; "Count: " &lt;&lt; sp1.use_count() &lt;&lt; endl; // 2
            } // sp2 destroyed, count = 1
            cout &lt;&lt; "Count: " &lt;&lt; sp1.use_count() &lt;&lt; endl; // 1
        } // sp1 destroyed, count = 0 — Resource released
    
        return 0;
    }
    

    15.4 Automatic Resource Management

    The combination of RAII, smart pointers, and move semantics means modern C++ programs can manage resources as safely as garbage-collected languages — without the runtime overhead of a garbage collector. This is the “zero-cost abstraction” philosophy at work.

    16. Interview Questions : Constructors and Destructors

    Q1: What is the difference between a constructor and a destructor?

    Constructor initializes an object when created. Destructor cleans up when the object is destroyed. Constructor can be overloaded; destructor cannot. Constructor has no prefix; destructor has ~. Constructor can take arguments; destructor cannot. Constructor cannot be virtual; destructor can and should be virtual in base classes.

    Q2: What is the difference between a copy constructor and the assignment operator?

    • Copy Constructor: Creates a new object as a copy. Called when a new object is initialized from an existing one. Signature: ClassName(const ClassName& obj)
    • Assignment Operator: Copies data into an existing object. Called when = is used between two already-existing objects. Signature: ClassName& operator=(const ClassName& obj)
    
    Box b1(5);
    Box b2 = b1; // Copy constructor (b2 is being created)
    Box b3;
    b3 = b1;     // Assignment operator (b3 already exists)
    

    Q3: Shallow Copy vs Deep Copy

    • Shallow copy copies the pointer, not the data it points to. Both objects share the same memory. When one is destroyed, the other has a dangling pointer.
    • Deep copy allocates new memory and copies the actual data. Objects are independent.

    The compiler-generated copy constructor does a shallow copy. Write your own for deep copy when your class manages heap memory.

    Q4: Why is a virtual destructor important?

    When you have a base class pointer to a derived object and call delete, only the base destructor runs if it’s not virtual. This skips derived class cleanup and leaks memory. Making the base destructor virtual ensures both destructors run correctly via dynamic dispatch.

    Q5: What is a copy constructor and when is it called?

    A copy constructor creates a new object from an existing one. It is called in three situations:

    1. Object initialized from another: Box b2 = b1;
    2. Object passed by value to a function
    3. Object returned by value from a function

    Q6: What is the Rule of Three? Rule of Five?

    If your class defines a destructor, copy constructor, or copy assignment — define all three (Rule of Three). C++11 adds move constructor and move assignment — define all five (Rule of Five). Or, use smart pointers and follow the Rule of Zero: define none of them and let the compiler handle everything.

    Q7: Output-Based Question — Constructor and Destructor Order

    
    class A {
    public:
        A() { cout &lt;&lt; "A()" &lt;&lt; endl; }
        ~A() { cout &lt;&lt; "~A()" &lt;&lt; endl; }
    };
    
    class B : public A {
    public:
        B() { cout &lt;&lt; "B()" &lt;&lt; endl; }
        ~B() { cout &lt;&lt; "~B()" &lt;&lt; endl; }
    };
    
    int main() {
        B obj;
        return 0;
    }
    

    Output:

    
    A()
    B()
    ~B()
    ~A()
    

    Constructor chain goes base → derived. Destructor chain goes derived → base.

    Q8: What happens if you forget to write a virtual destructor?

    
    class Base {
    public:
        ~Base() { cout &lt;&lt; "Base destructor" &lt;&lt; endl; } // NOT virtual
    };
    
    class Derived : public Base {
        int* data;
    public:
        Derived() { data = new int[100]; }
        ~Derived() {
            delete[] data; // This NEVER RUNS if deleted via Base*
            cout &lt;&lt; "Derived destructor" &lt;&lt; endl;
        }
    };
    
    int main() {
        Base* ptr = new Derived();
        delete ptr; // Only Base destructor runs — memory leak!
        return 0;
    }
    

    This is a classic memory leak. Fix: add virtual to Base’s destructor.

    Q9: Can you call a constructor explicitly? What about a destructor?

    You can call a constructor explicitly when using placement new (advanced topic — constructing an object at a specific memory address). You can technically call a destructor explicitly (like obj.~ClassName()), but it is almost never correct and usually leads to double-destruction bugs. With placement new it is necessary, but you should avoid this pattern unless you’re writing a memory allocator.

    Q10: Real-Life Example — RAII in Action

    Consider a mutex lock in a multithreaded program:

    
    class LockGuard {
        mutex&amp; mtx;
    public:
        LockGuard(mutex&amp; m) : mtx(m) { mtx.lock(); }
        ~LockGuard() { mtx.unlock(); } // Guaranteed to run — even if exception
    };
    
    void criticalSection(mutex&amp; m) {
        LockGuard guard(m); // Locked
        // ... do work, throw exception, return early — doesn't matter
        // Mutex is ALWAYS unlocked when guard goes out of scope
    }
    

    The standard library provides std::lock_guard which works exactly this way. This is RAII solving a real concurrency problem elegantly using constructors and destructors.

    Q11: What is a Delegating Constructor and why use it?

    Delegating constructors (C++11) let one constructor call another in the same class. Before C++11, shared initialization logic had to go into a private helper function. Now you can delegate directly, reducing duplication and keeping initialization in one place.

    Q12: Debugging Constructor and Destructor Calls

    Add print statements to constructors and destructors while learning. Count the calls: for every constructor call, there should be exactly one destructor call. If counts don’t match, you have a memory management bug. Tools like Valgrind, AddressSanitizer, or Microsoft’s CRT debug heap can catch these issues automatically.

    
    // Quick debug trick
    class Debug {
        static int count;
    public:
        Debug() { count++; cout &lt;&lt; "Created #" &lt;&lt; count &lt;&lt; endl; }
        ~Debug() { cout &lt;&lt; "Destroyed, remaining: " &lt;&lt; --count &lt;&lt; endl; }
    };
    int Debug::count = 0;
    

    Quick Reference Cheat Sheet

    ConceptKey Point
    Default ConstructorNo args; compiler generates if no constructor defined
    Parameterized ConstructorTakes args; initialize with specific values
    Copy ConstructorTakes const ClassName&; creates copy
    Move ConstructorTakes ClassName&&; transfers ownership
    Destructor~ClassName(); no args; no overloading
    Virtual DestructorRequired when deleting derived via base pointer
    Explicit ConstructorPrevents implicit type conversion
    Delegating ConstructorOne constructor calls another (C++11)
    RAIIAcquire in constructor, release in destructor
    Rule of ThreeDestructor + copy ctor + copy assign
    Rule of FiveRule of Three + move ctor + move assign
    = defaultCompiler-generated special member function
    = deleteDisable a function — compile error if called
    unique_ptrSole ownership, no copy, auto-delete
    shared_ptrShared ownership, reference counted
    Deep vs Shallow CopyDeep = new memory; Shallow = same pointer
    Singleton PatternPrivate constructor + static instance
    Constructor orderBase → Derived
    Destructor orderDerived → Base (reverse of construction)

    Conclusion

    If there is one thing to take away from this entire guide, it is this: constructors and destructors are the entry and exit points of every object’s life in C++. They are not just initialization helpers they are the mechanism through which C++ manages resources, enforces invariants, and gives you the power to write code that is both safe and efficient.

    Start with understanding the basics default, parameterized, and copy constructors. Understand why destructors exist and how they pair with constructors for resource management. Then level up to virtual destructors, RAII, move semantics, and smart pointers. That progression mirrors how C++ itself evolved over the decades.

    The real skill is not just knowing the syntax it is understanding when each concept is needed and why. Once that clicks, you will find yourself writing C++ code that is genuinely correct by construction, not just by luck.

    If you are preparing for interviews, pay special attention to: virtual destructors, shallow vs deep copy, Rule of Three and Five, and RAII. Those topics come up constantly because they test whether a candidate truly understands C++ memory model not just the surface syntax.

    Keep coding, keep breaking things in a sandbox, and the patterns will become second nature.

    Found this guide helpful? Share it with someone learning C++. And if you have a specific constructor or destructor question that wasn’t covered here, drop it in the comments below.

    For detailed understanding of Platform Devices and Drivers on Linux, refer to the Linux documentation on Platform Devices and Drivers .
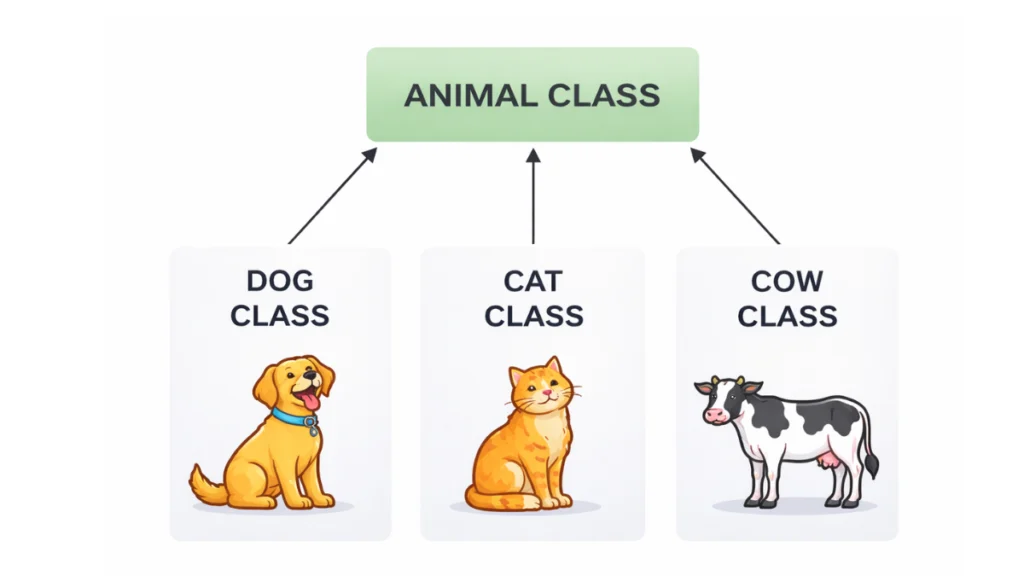
  • Inheritance in C++

    Learn Inheritance in C++ with simple examples, syntax, types, and access specifiers. A complete beginner to advanced guide for interviews and exams.

    Inheritance in C++ is an Object-Oriented Programming (OOP) concept where one class (called the derived class) acquires the properties and behavior (variables and functions) of another class (called the base class).

    In simple terms:
    Inheritance allows you to reuse existing code and build new features on top of it.

    Basic Syntax

    
    class BaseClass {
    // data members and member functions
    };
    
    class DerivedClass : access_specifier BaseClass {
    // additional members of derived class
    };

    Example :

    class BaseClass {
    public:
        int a;
    
        void display() {
            cout << "This is base class" << endl;
        }
    };
    
    class DerivedClass : public BaseClass {
    public:
        void show() {
            cout << "This is derived class" << endl;
        }
    };
    

    Example Program

    #include <iostream>
    using namespace std;
    
    class Animal {
    public:
        void eat() {
            cout << "Animal eats" << endl;
        }
    };
    
    class Dog : public Animal {
    public:
        void bark() {
            cout << "Dog barks" << endl;
        }
    };
    
    int main() {
        Dog d;
        d.eat();   // inherited from Animal
        d.bark();  // own function
        return 0;
    }
    

    Output:

    Animal eats
    Dog barks
    

    How Inheritance Works in C++

    1.Base Class is Created

    The base class contains common properties and functions.

    class Animal {
    public:
        void eat() {
            cout << "Animal eats" << endl;
        }
    };
    

    2.Derived Class Inherits Base Class

    The derived class uses : to inherit from the base class.

    class Dog : public Animal {
    public:
        void bark() {
            cout << "Dog barks" << endl;
        }
    };
    

    3.Object of Derived Class is Created

    When you create an object of the derived class, it can access:

    • Its own methods
    • Inherited methods from base class
    int main() {
        Dog d;
        d.eat();   // inherited function
        d.bark();  // own function
    }
    

    Internal Working of Inheritance

    Memory Sharing

    • The derived class object contains base class data + its own data
    • No duplication of code

    Conceptually:

    Dog object = Animal properties + Dog properties
    

    Function Access

    • Derived class can directly use public and protected members
    • Cannot access private members of base class directly

    Constructor Execution Order

    When object is created:

    1. Base class constructor runs first
    2. Derived class constructor runs next
    class A {
    public:
        A() {
            cout << "Base Constructor" << endl;
        }
    };
    
    class B : public A {
    public:
        B() {
            cout << "Derived Constructor" << endl;
        }
    };
    

    Output:

    Base Constructor
    Derived Constructor
    

    Destructor Order (Reverse)

    When object is destroyed:

    1. Derived class destructor runs
    2. Base class destructor runs

    Function Overriding

    Derived class can override base class function

    class A {
    public:
        void show() {
            cout << "Base";
        }
    };
    
    class B : public A {
    public:
        void show() {
            cout << "Derived";
        }
    };
    

    Access Specifiers in C++ Inheritance

    In inheritance, access specifiers define how the base class members are accessible in the derived class.

    Types of Access Specifiers

    public

    • Accessible everywhere
    • Can be used inside and outside the class

    protected

    • Accessible within the class and derived class
    • Not accessible outside

    private

    • Accessible only within the same class
    • Not accessible in derived class directly

    Syntax with Access Specifier

    class DerivedClass : access_specifier BaseClass {
        // code
    };
    

    Example:

    class B : public A
    

    How Access Specifiers Work in Inheritance

    Inheritance TypeBase public →Base protected →Base private →
    publicpublicprotected❌ not accessible
    protectedprotectedprotected❌ not accessible
    privateprivateprivate❌ not accessible

    Example Code

    #include <iostream>
    using namespace std;
    
    class A {
    public:
        int x = 10;
    
    protected:
        int y = 20;
    
    private:
        int z = 30;
    };
    
    class B : public A {
    public:
        void show() {
            cout << x << endl; // ✅ public → accessible
            cout << y << endl; // ✅ protected → accessible
            // cout << z; ❌ private → not accessible
        }
    };
    
    int main() {
        B obj;
        obj.show();
        cout << obj.x; // ✅ public accessible outside
        // cout << obj.y; ❌ not accessible outside
    }
    

    Key Points

    public → accessible everywhere
    protected → accessible in child class only
    private → not accessible in child class

    Default inheritance:

    • class → private inheritance
    • struct → public inheritance

    Real-Life Working Example

    Think of:

    • Parent Class: Vehicle
    • Child Class: Car

    Car automatically gets:

    • speed
    • engine

    But also adds:

    • air conditioning
    • music system

    Why Inheritance is Used in C++

    Benefits

    • Code reusability
    • Reduces duplication
    • Easy maintenance
    • Supports polymorphism
    • Improves readability

    Important Points

    • Inheritance uses : operator
    • Base class constructor executes first
    • Private members are not directly accessible
    • Supports multiple types (single, multiple, multilevel, etc.)
    • Used for “is-a” relationship (Dog is an Animal)

    What is the use of : in C++ Inheritance?

    In C++, the colon : is used to specify inheritance.

    It tells the compiler that:

    “This class is inheriting from another class.”

    Basic Syntax

    class DerivedClass : public BaseClass {
    };
    

    Here:

    • : → means inherit from
    • public → access specifier
    • BaseClass → parent class

    How : Works

    When you write:

    class B : public A {
    };
    

    It means:

    • Class B gets properties and functions of class A
    • B becomes child (derived class)
    • A becomes parent (base class)

    Example

    #include <iostream>
    using namespace std;
    
    class A {
    public:
        void show() {
            cout << "Base class" << endl;
        }
    };
    
    class B : public A {
    };
    
    int main() {
        B obj;
        obj.show();  // inherited using :
    }
    

    Without : → inheritance will NOT happen

    Without : (No Inheritance)

    class B {
    };
    

    Now:

    • B has no relation with A
    • Cannot access A’s functions

    Real Meaning of :

    Think of it like:

    : = “is derived from”
    : = “inherits from”

    Important Uses of :

    1. To inherit a class

    class Child : public Parent

    2. Multiple inheritance

    class C : public A, public B

    3. Access control during inheritance

    class B : private A

    Types of Inheritance in C++

    1. Single Inheritance

    One base class → One derived class

    class A {};
    class B : public A {};

    2. Multiple Inheritance

    One derived class inherits from multiple base classes

    class A {};
    class B {};
    class C : public A, public B {};

    3. Multilevel Inheritance

    Chain of inheritance

    class A {};
    class B : public A {};
    class C : public B {};

    4. Hierarchical Inheritance

    One base class → multiple derived classes

    class A {};
    class B : public A {};
    class C : public A {};

    5. Hybrid Inheritance

    Combination of multiple types (complex structure)

    Access Specifiers in Inheritance

    Inheritance TypePublic MembersProtected MembersPrivate Members
    publicpublicprotectednot accessible
    protectedprotectedprotectednot accessible
    privateprivateprivatenot accessible

    Example:

    class A {
    protected:
        int x;
    };
    
    class B : public A {
    public:
        void set() {
            x = 10; // accessible
        }
    };

    Key Concepts

    1. Code Reusability

    Reuse existing class code → reduces redundancy

    2. Method Overriding

    Derived class can redefine base class function

    class A {
    public:
        void show() {
            cout << "A";
        }
    };
    
    class B : public A {
    public:
        void show() {
            cout << "B";
        }
    };
    

    3. Constructor in Inheritance

    Base class constructor runs first

    class A {
    public:
        A() {
            cout << "Base constructor" << endl;
        }
    };
    
    class B : public A {
    public:
        B() {
            cout << "Derived constructor" << endl;
        }
    };
    

    4. Destructor Order

    Destructor runs in reverse order

    5. protected Keyword

    Allows access in derived classes but not outside

    6. super concept in C++

    C++ uses base class name instead of super

    class B : public A {
    public:
        void show() {
            A::show(); // calling base class function
        }
    };
    

    Advantages of Inheritance

    • ✔ Code reuse
    • ✔ Easy maintenance
    • ✔ Extensibility
    • ✔ Improves readability
    • ✔ Supports polymorphism

    Disadvantages

    • ❌ Tight coupling between classes
    • ❌ Can increase complexity
    • ❌ Improper use leads to errors

    Real-Life Example

    Think of:

    • Vehicle (Base Class)
    • Car, Bike (Derived Classes)

    All share common features like speed, engine, but also have unique features.

    Interview Questions

    1. What is inheritance in C++?
    2. Difference between inheritance and polymorphism?
    3. Types of inheritance?
    4. What is multiple inheritance?
    5. What is diamond problem?
    6. Difference between public, private, protected inheritance?
    7. Constructor order in inheritance?
    8. What is virtual inheritance?

    Summary

    Inheritance is a powerful feature in C++ that allows one class to inherit properties and behavior from another class, making code reusable, scalable, and easier to manage.

    Frequently Asked Questions (FAQs) on Inheritance in C++

    1️⃣ What is inheritance in C++?

    Inheritance is an OOP concept where a derived class acquires properties and functions of a base class.

    2️⃣ Why is inheritance used in C++?

    It is used for:

    • Code reusability
    • Reducing duplication
    • Easy maintenance
    • Extending existing functionality

    3️⃣ What is a base class and derived class?

    • Base class → Parent class
    • Derived class → Child class that inherits from base class

    4️⃣ What does : mean in inheritance?

    The : operator is used to define inheritance between classes.

    5️⃣ What are the types of inheritance in C++?

    • Single
    • Multiple
    • Multilevel
    • Hierarchical
    • Hybrid

    6️⃣ What is single inheritance?

    One derived class inherits from one base class.

    7️⃣ What is multiple inheritance?

    A derived class inherits from more than one base class.

    8️⃣ What is multilevel inheritance?

    A class is derived from another derived class (chain structure).

    9️⃣ What is hierarchical inheritance?

    Multiple classes inherit from the same base class.

    🔟 What is hybrid inheritance?

    Combination of multiple inheritance types.

    1️⃣1️⃣ What are access specifiers in inheritance?

    They control visibility of base class members:

    • public
    • protected
    • private

    1️⃣2️⃣ Can private members be inherited?

    Yes, but they are not directly accessible in derived class.

    1️⃣3️⃣ What is function overriding?

    When a derived class provides its own implementation of a base class function.

    1️⃣4️⃣ What is the order of constructor execution?

    • Base class constructor executes first
    • Then derived class constructor

    1️⃣5️⃣ What is the diamond problem?

    It occurs in multiple inheritance when a class inherits from two classes that have a common base class, causing ambiguity.

    Solution: Virtual inheritance

    For detailed understanding of Platform Devices and Drivers on Linux, refer to the Linux documentation on Platform Devices and Drivers .
  • What is Polymorphism?

    Learn polymorphism in object-oriented programming (OOP) with clear examples and easy explanations. Understand method overloading, method overriding, runtime and compile-time polymorphism, and how they improve code flexibility, reusability, and scalability.

    Polymorphism is a fundamental concept in object-oriented programming (OOP) that allows a single function, method, or interface to perform different behaviors depending on the object or input.

    In simple terms, polymorphism means “one name, many forms,” where the same operation behaves differently in different situations.

    Polymorphism = “Many Forms”

    In programming, it means:

    One name (function/method) can do different things depending on the object or input.

    Simple Real-Life Example

    Think of the word “run”:

    • You run in a race
    • A machine runs
    • A program runs

    Same word → different meanings → polymorphism

    Programming Example

    • For a circle → it draws a circle
    • For a square → it draws a square

    Same function name → different behavior

    Code Example

    class Shape {
    public:
        void draw() {
            cout << "Drawing shape";
        }
    };
    
    class Circle : public Shape {
    public:
        void draw() {
            cout << "Drawing circle";
        }
    };
    
    class Square : public Shape {
    public:
        void draw() {
            cout << "Drawing square";
        }
    };
    

    What happens?

    Shape* s;
    
    Circle c;
    Square sq;
    
    s = &c;
    s->draw();   // Drawing circle
    
    s = &sq;
    s->draw();   // Drawing square
    

    Same draw() → different outputs
    This is polymorphism

    Why Do We Need Polymorphism?

    • Code Reusability
      Write one function and use it for multiple types of objects, reducing duplicate code.
    • Flexibility in Code
      The same interface can handle different data types or objects, making code adaptable.
    • Cleaner & Maintainable Code
      Reduces complexity and keeps code organized, especially in large projects.
    • Extensibility (Easy to Add Features)
      You can add new classes or behaviors without changing existing code.
    • Supports Dynamic Behavior
      Objects can behave differently at runtime, making programs more realistic.
    • Improves Readability
      Using a common method name makes code easier to understand.
    • Reduces Conditional Statements
      Avoids multiple if-else or switch cases by using a common interface.
    • Better Abstraction
      Focus on what to do, not how it is done, improving design quality.
    • Real-World Modeling
      Helps represent real-world scenarios where the same action behaves differently.

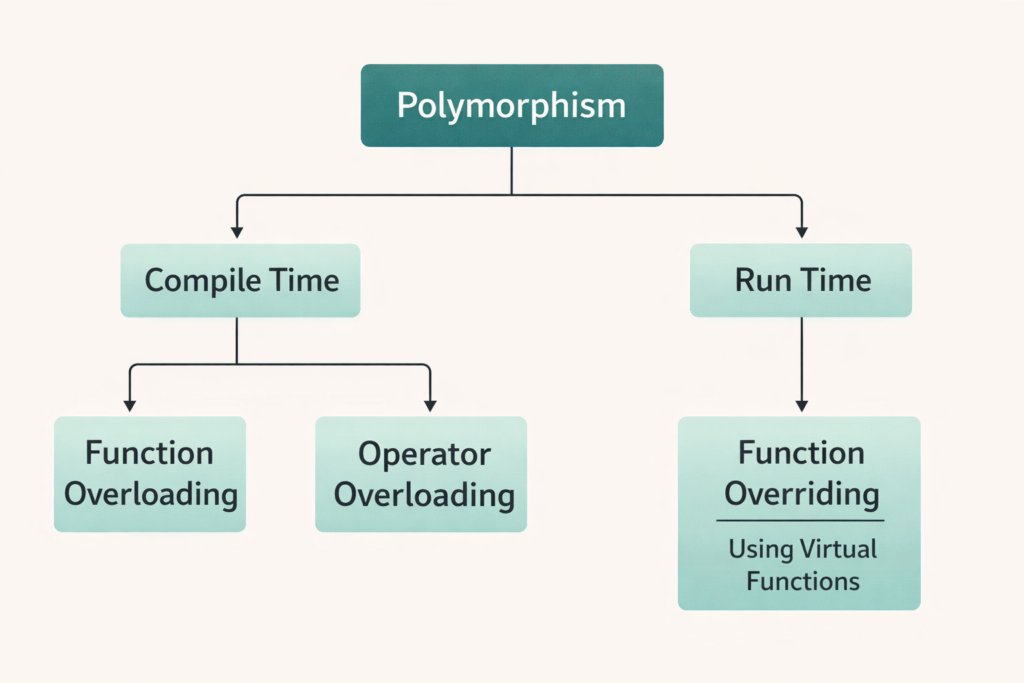
    Types of Polymorphism

    There are two main types:

    Types of Polymorphism

    1.Compile-Time Polymorphism (Static Polymorphism)

    Decided at compile time (before program runs)

    How it works?

    The compiler decides which function to call based on:

    • Number of parameters
    • Type of parameters

    A ) Method Overloading

    Same function name, but:

    • Different number of arguments OR
    • Different data types

    Example (C++)

    class Math {
    public:
        int add(int a, int b) {
            return a + b;
        }
    
        int add(int a, int b, int c) {
            return a + b + c;
        }
    
        float add(float a, float b) {
            return a + b;
        }
    };
    

    What’s happening?

    Math m;
    
    m.add(2, 3);        // calls int version
    m.add(2, 3, 4);     // calls 3-arg version
    m.add(2.5, 3.5);    // calls float version
    

    Compiler chooses function before execution

    B) Operator Overloading

    Operators behave differently based on operands.

    int a = 5 + 3;        // addition
    string s = "Hi " + "Bro"; // concatenation
    

    Same + → different behavior

    Key Features

    • Fast (no runtime decision)
    • No inheritance required
    • Less flexible than runtime polymorphism

    2.Run-Time Polymorphism (Dynamic Polymorphism)

    Decided at runtime (during execution)

    How it works?

    • Uses inheritance
    • Uses function overriding
    • Uses pointers/references
    • Uses virtual functions (C++)

    Method Overriding

    Child class provides its own version of parent function.

    Example (C++)

    class Animal {
    public:
        virtual void sound() {
            cout << "Animal sound";
        }
    };
    
    class Dog : public Animal {
    public:
        void sound() {
            cout << "Dog barks";
        }
    };
    
    class Cat : public Animal {
    public:
        void sound() {
            cout << "Cat meows";
        }
    };
    

    Runtime Behavior

    Animal* a;
    
    Dog d;
    Cat c;
    
    a = &d;
    a->sound();   // Dog barks
    
    a = &c;
    a->sound();   // Cat meows
    

    Decision happens at runtime, not compile time

    What is virtual in C++?

    The virtual keyword is used in a base class to ensure that a function can be overridden in a derived (child) class and that the correct function is called at runtime, not compile time.

    Definition

    virtual enables runtime polymorphism by allowing function calls to be resolved dynamically (during execution).

    Why Do We Need virtual?

    Without virtual, C++ uses early binding (compile-time)
    With virtual, C++ uses late binding (runtime)

    This ensures the program calls the correct function based on the actual object, not the pointer type.

    Without virtual (Problem ❌)

    class Animal {
    public:
        void sound() {
            cout << "Animal sound";
        }
    };
    
    class Dog : public Animal {
    public:
        void sound() {
            cout << "Dog barks";
        }
    };
    
    Animal* a;
    Dog d;
    
    a = &d;
    a->sound();   // ❌ Output: Animal sound
    

    Even though object is Dog, it calls Animal function
    Because binding happens at compile time

    With virtual (Solution ✔️)

    class Animal {
    public:
        virtual void sound() {
            cout << "Animal sound";
        }
    };
    
    class Dog : public Animal {
    public:
        void sound() {
            cout << "Dog barks";
        }
    };
    
    Animal* a;
    Dog d;
    
    a = &d;
    a->sound();   // ✔️ Output: Dog barks
    

    Now correct function is called at runtime

    How virtual Works Internally

    When you use virtual:

    Compiler creates:

    • vtable (Virtual Table) → stores function pointers
    • vptr (Virtual Pointer) → inside each object

    At runtime:

    • Object’s vptr points to correct function in vtable
    • Function call is resolved dynamically

    Key Concepts Related to virtual

    1.Function Overriding

    Child class replaces parent function

    2.Base Class Pointer

    Animal* a;
    

    Needed for runtime polymorphism

    3.Dynamic Binding

    Function call decided at runtime

    Virtual Destructor

    class Base {
    public:
        virtual ~Base() {
            cout << "Base destructor";
        }
    };
    

    Ensures:

    • Proper cleanup of derived class objects
    • Prevents memory leaks

    Pure Virtual Function (Advanced)

    class Shape {
    public:
        virtual void draw() = 0;  // pure virtual
    };
    

    Makes class abstract
    Child class must implement this function

    When to Use virtual?

    • When using inheritance
    • When behavior should change in child classes
    • When using base class pointers/references
    • When implementing polymorphism

    Why virtual is important?

    Without virtual:
    Base class function will always be called ❌

    With virtual:
    Correct child function is called ✔️

    Behind the scenes

    • Uses vtable (virtual table)
    • Each object keeps pointer to correct function
    • Enables dynamic dispatch

    Key Features

    • Flexible
    • Supports real-world modeling
    • Slightly slower (runtime decision)
    • Requires inheritance

    Difference Between Both

    FeatureCompile-TimeRun-Time
    Decision TimeBefore executionDuring execution
    SpeedFasterSlightly slower
    ConceptOverloadingOverriding
    InheritanceNot requiredRequired
    FlexibilityLessMore

    Simple Analogy

    • Compile-time → Teacher assigns roles before play
    • Run-time → Actor changes role on stage dynamically

    Compile-Time Polymorphism

    Other Names:

    • Static Polymorphism
    • Early Binding
    • Static Binding

    All mean the same thing:

    Decision is made before program runs

    Run-Time Polymorphism

    Other Names:

    • Dynamic Polymorphism
    • Late Binding
    • Dynamic Binding

    All mean:

    Decision is made during program execution

    Example WITHOUT virtual ❌ (Compile-Time Binding)

    Code

    #include <iostream>
    using namespace std;
    
    class Animal {
    public:
        void speak() {
            cout << "Animal speaks" << endl;
        }
    };
    
    class Dog : public Animal {
    public:
        void speak() {
            cout << "Dog barks" << endl;
        }
    };
    
    int main() {
        Animal* a;
        Dog d;
    
        a = &d;
        a->speak();   // What will this print?
    
        return 0;
    }
    

    Output

    Animal speaks
    

    Why this happens (Important)

    • Pointer type = Animal*
    • Object type = Dog

    But C++ ignores object type here
    It only looks at pointer type at compile time

    So:

    • Compiler decides → call Animal::speak()
    • This is called Static Binding / Early Binding

    Key Point

    Without virtual, function call depends on pointer type, not actual object.

    Example WITH virtual ✔️ (Run-Time Binding)

    Code

    #include <iostream>
    using namespace std;
    
    class Animal {
    public:
        virtual void speak() {
            cout << "Animal speaks" << endl;
        }
    };
    
    class Dog : public Animal {
    public:
        void speak() {
            cout << "Dog barks" << endl;
        }
    };
    
    int main() {
        Animal* a;
        Dog d;
    
        a = &d;
        a->speak();   // Now what?
    
        return 0;
    }
    

    Output

    Dog barks
    

    Why this happens

    Because of virtual:

    Compiler delays decision until runtime
    It checks actual object type (Dog)
    Calls Dog::speak()

    This is called:

    What Changes Internally?

    Without virtual:

    • Direct function call
    • No extra mechanism
    • Faster
    • No polymorphism

    With virtual:

    C++ creates:

    vtable (Virtual Table)

    • A table storing addresses of virtual functions

    vptr (Virtual Pointer)

    • Hidden pointer inside each object

    Flow at Runtime:

    1. a = &d;
    2. Object d has its own vptr
    3. vptr points to Dog’s vtable
    4. a->speak():
      • Looks into vtable
      • Finds Dog::speak()
      • Calls it ✔️

    Side-by-Side Comparison

    FeatureWithout virtualWith virtual
    BindingCompile-timeRun-time
    Function CalledBased on pointerBased on object
    Polymorphism❌ No✔️ Yes
    SpeedFasterSlightly slower
    FlexibilityLowHigh

    Real-Life Analogy

    Without virtual:
    You call a person by their job title only
    (“Hey Employee”) → always same response

    With virtual:
    You call based on actual person
    (“Hey Developer / Manager”) → different response

    Basic Interview Questions

    • What is polymorphism?
    • What are the types of polymorphism?
    • Difference between compile-time and runtime polymorphism?
    • What is method overloading vs method overriding?
    • What is the virtual keyword in C++?
    • Why do we use virtual functions?

    Core Concept Questions

    • What happens if we don’t use virtual in function overriding?
    • Why do we need a base class pointer for runtime polymorphism?
    • Explain early binding vs late binding.
    • How does C++ decide which function to call?
    • Can we achieve polymorphism without inheritance? (Yes → overloading)

    Code-Based Questions

    Interviewer may give code like this:

    class A {
    public:
        void show() { cout << "A"; }
    };
    
    class B : public A {
    public:
        void show() { cout << "B"; }
    };
    
    int main() {
        A* obj = new B();
        obj->show();
    }
    

    Question:

    What will be the output and why?

    Expected Answer:

    • Output = A (because no virtual)
    • Uses compile-time binding

    Same with virtual

    virtual void show()
    

    Output = B
    Because of runtime polymorphism

    Advanced Questions

    • What is a virtual table (vtable)?
    • What is a virtual pointer (vptr)?
    • How does dynamic dispatch work internally?
    • What is the cost of using virtual functions?
    • Can constructors be virtual? (No ❌)
    • Can destructors be virtual? (Yes ✔️, very important)

    Tricky Questions

    • What happens if base class destructor is not virtual?
      👉 Can cause memory issues / incomplete cleanup
    • Can we override a non-virtual function?
      👉 Yes, but no runtime polymorphism
    • Difference between virtual and pure virtual?
      👉 Pure virtual makes class abstract
    • What is an abstract class?
      👉 Class with at least one pure virtual function

    Scenario-Based Questions

    • When should you use polymorphism in real projects?
    • Give a real-world example of polymorphism.
    • Where have you used virtual functions?
    • How would you design a system using polymorphism?

    Top 5 Must-Prepare Questions

    If you prepare only these, you’re safe 👇

    1. What is polymorphism with example?
    2. Compile-time vs runtime polymorphism
    3. What is virtual and why needed?
    4. Output-based question (with/without virtual)
    5. What is vtable and how it works?

    For detailed understanding of Platform Devices and Drivers on Linux, refer to the Linux documentation on Platform Devices and Drivers .

  • Choosing Your First Drone Platform : The Complete Beginner’s Guide

    Choosing your first drone platform made easy. Compare features, costs, flight control systems, and use cases to pick the perfect drone for beginners.

    So you’ve decided you want a drone. Maybe you watched a friend’s aerial footage on YouTube and your jaw dropped. Maybe you hiked somewhere stunning and wished you had a camera in the sky. Or maybe you just love gadgets and the idea of flying something with your hands sounds like the most fun you can have on a Saturday afternoon.

    Whatever got you here, welcome. You’re about to make a decision that, done right, will give you years of enjoyment. Done wrong, you’ll spend $400 on a plastic paperweight that crashes into a tree on day two and never gets turned on again.

    Choosing your first drone platform is genuinely one of the trickier consumer tech decisions out there, and that’s not because drones are complicated in themselves. It’s because the market is flooded with options ranging from $30 toys to $10,000 cinematic rigs, and the marketing around all of them is aggressively optimistic. Every box says “easy to fly.” Every listing says “perfect for beginners.” Most of them are lying, at least a little.

    This guide is going to cut through all of that. We’ll talk about what actually matters when you’re picking your first drone, what the different categories mean in practice, which platforms are genuinely worth your money in 2025, and what nobody in the marketing material ever tells you about flying one.

    Why Your First Drone Platform Decision Actually Matters

    Here’s the thing most beginner drone guides gloss over: the platform you start on shapes your entire experience with the hobby, at least for the first year or two.

    If you buy something too simple, you’ll hit its ceiling within a month and feel bored. If you buy something too advanced, you’ll spend more time troubleshooting and crashing than actually flying, and you’ll either give up or burn through money on replacements. If you buy the wrong category entirely, you’ll end up with a drone that can’t do what you actually wanted.

    The best first drone for someone who wants to shoot travel videos is completely different from the best first drone for someone who wants to race through gates in a field. Those are different sports that happen to share some technology.

    So before we talk about any specific model, we need to talk about what you actually want to do. That question sounds obvious, but a surprising number of people skip it and just buy whatever has the most impressive spec sheet.

    Step One: Be Honest About What You Actually Want to Do

    This is the most important section in this entire article. Read it before you look at a single product listing.

    There are three distinct worlds within consumer drones, and they don’t overlap as much as you’d think.

    Camera Drones are what most people picture when they think of a drone. A small flying machine with a stabilized camera hanging underneath it. You take off, fly it somewhere interesting, shoot video or photos, land it, and use the footage. These are GPS-stabilized, usually come with automated flight modes, and are designed to be flown by people who are primarily interested in the footage rather than the flying. DJI dominates this category with models like the Mini 4 Pro and the Air 3.

    FPV Drones (First Person View) are completely different. You wear goggles and you see what the drone sees in real time, flying from the drone’s perspective like you’re actually inside it. These are fast, agile, and demand real skill. The flying itself is the point, not just the footage. FPV is an actual skill-based sport, and the learning curve is steep. The footage can be breathtaking, but you will crash a lot before you get there.

    Toy and Micro Drones are the $30 to $100 plastic quadcopters you see at electronics stores. They’re fine for indoor flying and learning the basic concept of how controls work, but they have almost no real-world capability. Wind is their enemy. Cameras, if they have one, are usually terrible. These aren’t really a platform, they’re a stepping stone or a kids’ toy.

    Most beginners who want to actually do something with their drone, whether that’s photography, videography, travel content, real estate work, or just outdoor flying fun, belong in the camera drone category. That’s where most of this guide will focus. We’ll also cover FPV specifically because there’s a growing audience of beginners who want to get into it.

    If you’re reading this because you want to take nice footage of your camping trips, your kids’ sports games, or your travels abroad, a camera drone is what you want. Keep reading.

    Understanding Drone Categories and What They Actually Mean for Beginners

    Camera Drones: The Practical Choice for Most People

    The camera drone market in 2025 is largely split into tiers by weight and capability, and this matters more than you might expect because drone regulations worldwide are structured around weight classes.

    Sub-250g Drones are the sweet spot for beginners, and for good reason. In most countries including the United States, European Union, Canada, and Australia, drones under 250 grams face significantly lighter regulatory requirements than heavier aircraft. In the US, you can fly a sub-250g drone recreationally without FAA registration (though you still need to follow flight rules). In the EU, sub-250g drones often fall into the most permissive C0 class. This means you can fly more places with fewer legal headaches.

    The DJI Mini series dominates this category. The Mini 4 Pro weighs in just under 249 grams and shoots 4K video with a 1/1.3-inch sensor. That’s a genuinely capable camera in a form factor that fits in your jacket pocket. For a first drone, it’s hard to argue against it.

    250g to 600g Drones offer larger sensors and more advanced features but come with more regulatory requirements. The DJI Air 3 lives here, with a dual-camera setup and a larger 1/1.3-inch main sensor. If you’re serious about aerial photography and want that step up in image quality, this is the tier to consider, but understand you’re taking on more paperwork and more locations where you’ll need to check permissions.

    600g and Above is where you find prosumer and professional tools. The DJI Mavic 3 series, the Autel EVO II Pro, and similar platforms. These have large sensors, exceptional image quality, and long flight times, but they’re not beginner territory. They’re also expensive enough that crashing one is genuinely painful.

    For your first drone, the answer for most people is: buy in the sub-250g category. You’ll have fewer legal barriers, the drones are physically smaller and easier to transport, and the technology has gotten good enough that you won’t feel like you’re making a meaningful sacrifice in image quality.

    FPV Drones: A Completely Different Animal

    If you want to get into FPV flying, understand going in that this is more like learning to ride a motorcycle than learning to drive a car. It requires dedicated practice, there will be crashes, and you’ll probably need to repair or rebuild your quad at some point.

    The standard advice for FPV beginners is to start in a simulator before you ever buy real hardware. FPV simulators like Velocidrone and Liftoff are available on PC and they accurately simulate the physics of FPV flight. Spend 20 to 30 hours in a sim before spending money on hardware. This alone will save you hundreds of dollars in crash repairs.

    For your actual first FPV build or prebuilt, the options have gotten much better for beginners. The DJI Neo and Avata 2 are DJI’s entry points into assisted FPV, where you get some of the FPV experience with safety nets like obstacle avoidance and stabilized flight modes. These are genuinely a good starting point if you want the FPV experience without going full manual immediately.

    For traditional “freestyle” FPV, the Geprc Cinelog 25 and similar 2.5-inch quads are popular beginner choices because they’re small enough to crash without catastrophic damage but capable enough to grow with you.

    We’ll come back to FPV later in the guide. For now, let’s go deep on camera drones since that’s what most people asking about choosing their first drone platform actually want.

    Key Specs That Actually Matter (And Ones That Don’t)

    Drone product listings are full of numbers. Most of them matter less than the marketing suggests. Here’s what’s actually worth paying attention to.

    Camera Sensor Size

    This matters more than megapixels. A larger sensor captures more light, which means better image quality in anything other than perfect daytime conditions. When you’re shooting at sunrise, in shade, or in any kind of low light, sensor size becomes the deciding factor between footage that looks professional and footage that looks grainy and noisy.

    For reference: a 1/2-inch sensor is decent for a beginner drone. A 1/1.3-inch sensor is noticeably better. A 4/3-inch sensor (found in the Mavic 3 series) is excellent. The difference between 1/2-inch and 1/1.3-inch is clearly visible in challenging light. The difference between 12MP and 48MP matters far less than sensor size.

    Video Resolution and Frame Rate

    4K is now basically standard at any price point above $200, so don’t let it dazzle you. What matters more is whether the drone can shoot 4K at 60fps (useful for slow-motion) and what the color profile options are. Drones with a D-Log or similar flat color profile give you much more flexibility in post-production. If you plan to do any color grading, look for a drone that supports LOG footage.

    Flight Time

    This is one of the most aggressively optimistic numbers in drone marketing. When a manufacturer says a drone has a 34-minute flight time, they mean in perfect conditions, no wind, optimal speed, fresh battery, mild temperature. In real-world conditions, knock 20 to 30 percent off that number. Also remember you should land with some battery remaining, and the last 20 percent of charge often gets consumed faster than the rest.

    Practically speaking: 20 to 25 minutes of real-world flight time is solid for a beginner camera drone. 15 minutes is workable. Anything under 12 minutes starts to become frustrating.

    Range and Transmission System

    The range listed on drone specs assumes ideal conditions with no interference. In urban environments with lots of Wi-Fi signals, your range will be lower. That said, for most beginner flying, range beyond about 1 kilometer isn’t practically useful anyway. What matters more is the quality of the video transmission link, how stable it is, and how well it handles interference.

    DJI’s O3 and O4 transmission systems are genuinely best-in-class at this point. The difference between DJI’s video link and competitors shows up in real-world reliability.

    Obstacle Avoidance

    For beginners, this is worth paying for. Obstacle avoidance uses sensors (often infrared or camera-based) to detect objects in the drone’s path and stop or redirect. It doesn’t catch everything, and it doesn’t work in all conditions, but it will save you from many of the embarrassing beginner crashes where you didn’t see the tree branch behind you.

    The DJI Mini 4 Pro has omnidirectional obstacle avoidance, meaning it can sense obstacles in all directions including below and above. The older Mini 3 Pro only has forward, backward, and downward sensing. If obstacle avoidance matters to you, it’s worth paying for the fuller implementation.

    GPS and Stabilization

    This is non-negotiable for a beginner camera drone. GPS allows the drone to hold its position in the air when you let go of the sticks. Without GPS, the drone will drift with the wind and require constant correction. For beginners, flying without GPS is an exercise in frustration.

    Every drone in the $200-and-up camera drone category will have GPS. Just make sure it also has GLONASS support (more satellites, better positioning) and ideally Galileo or BeiDou support as well. More satellite systems equals faster lock and more stable positioning.

    Wind Resistance

    This matters more than beginners expect. A drone rated for Level 5 wind resistance can handle winds up to about 38 km/h (approximately 24 mph). Level 4 handles up to about 29 km/h. In practice, you can fly in wind conditions up to the drone’s rated level, but the footage will be shakier and flight time drops significantly in wind.

    Heavier drones generally handle wind better than lighter ones. The sub-250g class, by being lighter, is more susceptible to wind. You’ll notice this the first time you try to fly your Mini series drone on a gusty afternoon.

    Budget Breakdown: What You Actually Get at Each Price Point

    Let’s be direct about money because this is where a lot of beginners go wrong, either by underspending and getting frustrated, or overspending on features they don’t need yet.

    Under $100: Toy Drones

    These are primarily indoor flying toys. They have cameras ranging from genuinely terrible to mediocre. They are not stable outdoors in any real wind. They are fine for learning the basic concept of how a quadcopter responds to stick inputs, especially for kids or as a gift, but they are not a platform for doing anything meaningful with aerial photography.

    The Ryze Tello (made by DJI, programmed for education) is the best in this range and is worth mentioning specifically because of its flight stability and programming capabilities, but even it has severe limitations outdoors.

    If your budget is genuinely under $100, buy the Tello or save up. Don’t spend $60 on a random no-name quadcopter expecting a real flying experience.

    $100 to $250: Entry-Level Platforms with Real Capability

    This tier is where you start to get actual value for outdoor flying. The Holy Stone HS720E and similar GPS-enabled camera drones offer real GPS stabilization, 4K cameras (often with smaller sensors but decent video in good light), and flight times around 20 minutes. These are legitimate starter platforms.

    For FPV beginners, this budget range also opens up options like the DJI Neo, which brings DJI build quality and transmission technology to an accessible price point with beginner-friendly flight modes.

    The limitation of this tier is image quality. Sensors in this range are small, and footage in anything other than bright daylight shows noise and limited dynamic range. If casual flying and basic aerial shots are your goal, this is fine. If you want footage you’re proud of, you’ll feel the ceiling.

    $250 to $500: Where Serious Beginners Should Start

    This is the sweet spot for most people reading this guide. The DJI Mini 3 (not the Pro) sits at around $299 to $399 depending on where you buy and which bundle you choose. You get DJI’s excellent O3 video transmission, a genuinely capable camera, GPS with solid stabilization, and the full DJI Fly app experience including automated flight modes.

    The DJI Mini 3 Pro (now slightly reduced in price) adds forward and backward obstacle avoidance and a better camera for another $100 to $150. If you can stretch to the Mini 3 Pro over the base Mini 3, do it.

    In this range you’ll also find the Autel EVO Nano+, which is a direct competitor to the Mini 3 with slightly different feature tradeoffs. Autel’s SkyPixel app is less polished than DJI Fly, but the hardware is solid.

    $500 to $800: Best First Drone Platforms for Serious Aerial Photography

    If your goal is to produce footage you’re genuinely proud of, the DJI Mini 4 Pro is where serious beginners with a real interest in aerial photography should be looking. At around $760 for the Fly More combo (which includes extra batteries and a bag, things you definitely want), it’s a meaningful investment but one that gives you a drone with genuinely professional-grade features.

    The Mini 4 Pro shoots 4K at up to 100fps, has a 1/1.3-inch sensor with D-Log M support for color grading, omnidirectional obstacle avoidance, and ActiveTrack 360 for tracking subjects automatically. It’s the drone professional travel creators and real estate photographers actually reach for.

    Above $800: Probably Not Your First Drone

    The DJI Air 3, DJI Mavic 3 Classic, and Autel EVO Lite+ all live above $800. These are excellent platforms but they’re not where you should spend your first drone budget. Buy a Mini 4 Pro, learn on it, crash it a few times (hopefully minor crashes), figure out what you actually want to do with aerial footage, and then upgrade if you decide you need more. Buying a $1,500 drone as your first purchase and then discovering you only fly it twice a year is a common and expensive mistake.

    Top Beginner Drone Platforms Compared: 2025 Honest Review

    Let’s get into specific recommendations.

    DJI Mini 4 Pro — Best All-Around First Drone

    Who it’s for: Travel content creators, beginner aerial photographers, people who want footage they’re proud of without a steep learning curve.

    What makes it great: The Mini 4 Pro gets almost everything right for a first serious drone. The 1/1.3-inch sensor produces footage that looks genuinely cinematic in the right conditions. Omnidirectional obstacle avoidance means it’s actively working to keep itself in one piece while you’re learning. The DJI Fly app is well-designed and the automated modes like Hyperlapse, Mastershots, and QuickShots give you impressive footage even before you learn to fly manually.

    The sub-249g weight is the other major advantage. You’ll face fewer regulatory barriers, it’s small enough to pack in a regular daypack, and the propellers are less dangerous if something goes wrong.

    What to know: Even with obstacle avoidance, you can still crash this drone. Obstacle avoidance doesn’t work in low light, doesn’t detect wires well, and won’t save you from dumb decisions. Fly cautiously while you learn.

    Pricing note: Buy the Fly More Combo. The extra batteries make a massive difference in your actual flying sessions. One battery gives you maybe 25 minutes of real-world flight time. Three batteries gets you closer to an hour.

    DJI Mini 3 — Best Value First Drone

    Who it’s for: Beginners who want a capable first drone without spending $760.

    What makes it great: The base Mini 3 costs significantly less than the Mini 4 Pro while still offering 4K video, solid GPS stabilization, the full DJI ecosystem experience, and that valuable sub-249g weight class. It’s a genuinely capable beginner platform.

    What to know: The Mini 3 lacks obstacle avoidance (forward and side sensors only on the Pro version, nothing on the base). Its sensor is slightly smaller than the Mini 4 Pro’s. You’ll feel the difference in low-light shooting. But for daytime flying and casual aerial content, you might never notice.

    Autel EVO Nano+ — Best Alternative to DJI

    Who it’s for: People who specifically want an alternative to DJI, or anyone who has existing Autel gear.

    What makes it great: The EVO Nano+ packs a competitive camera with a 1/1.28-inch sensor into the sub-249g form factor. It has obstacle avoidance on three sides. Autel’s color science is excellent, particularly for still photography. And buying Autel means you’re diversifying away from DJI’s sometimes-complicated relationship with export regulations and app restrictions.

    What to know: The SkyPixel app isn’t as polished as DJI Fly. The transmission system is good but doesn’t quite match DJI O3’s reliability at range. Accessories and batteries are less widely available than DJI options. But if you have specific reasons to avoid DJI, the EVO Nano+ is a legitimate choice.

    DJI Avata 2 — Best First FPV Drone

    Who it’s for: Beginners specifically interested in the FPV experience who want guard rings and safety features.

    What makes it great: The Avata 2 is DJI’s attempt to make FPV accessible. It has protective guard rings around the propellers, making it safer for indoor flying and closer proximity work. It has three flight modes including a “Normal” mode that behaves more like a regular camera drone and a “Sport” mode before you get into full manual. The DJI Goggles 3 paired with the Avata 2 give you a genuinely immersive FPV experience.

    What to know: The Avata 2 isn’t what traditional FPV pilots fly. It’s a gateway drug, an introduction to the experience. Many Avata pilots end up wanting to transition to proper freestyle quads after six months. That’s fine, the skills transfer. But go in knowing you’re buying a training wheel FPV platform.

    Holy Stone HS720E — Best Budget Camera Drone

    Who it’s for: True beginners on a tight budget who want GPS stabilization and a real outdoor flying experience without spending $400.

    What makes it great: At around $150 to $200, the HS720E gives you GPS hold, a 4K camera (small sensor but functional in daylight), and flight times around 23 minutes. It’s a genuine outdoor camera drone at an accessible price point.

    What to know: Everything about this drone is a tier below the DJI and Autel options. The camera quality in anything other than perfect daylight is mediocre. The app is clunky. There’s no obstacle avoidance. Repairs and parts are harder to find. But if $200 is your budget and you want a real GPS drone, this is a legitimate starting point.

    GPS vs. Non-GPS Drones: Why This Matters So Much for Beginners

    This distinction deserves its own section because it’s the single most important feature for beginner safety and enjoyment.

    A GPS drone holds its position automatically. When you take your hands off the sticks, the drone hovers in place. If it loses signal with the controller, it will usually Return to Home automatically, flying back to where it took off and landing itself. This is an enormous safety net for beginners.

    A non-GPS drone (often called optical flow only if it has downward cameras for indoor stabilization) will drift with the wind the moment you let go of the sticks. You have to constantly make small corrections to keep it where you want it. This is a learnable skill, but it requires real attention and practice. In outdoor conditions with any wind, flying without GPS is stressful for beginners.

    For your first outdoor drone, GPS is non-negotiable. Don’t let anyone convince you otherwise. Every camera drone above $200 that’s worth buying has GPS. If a listing says “optical flow only” with no mention of GPS, keep scrolling.

    The only context where non-GPS flying makes sense for beginners is FPV, where it’s part of the challenge and the tradition. Even then, many new FPV pilots start in Angle mode (a stabilized flight mode that behaves similarly to GPS drones) before progressing to Acro mode.


    Drone Laws for Beginners: What You Actually Need to Know

    This section is important, and honestly, most drone guides either skip it entirely or bury it at the end. We’re putting it front and center because flying illegally, even accidentally, can result in real fines and legal trouble.

    In the United States (FAA Rules)

    The FAA governs drone flying in the US, and the rules depend on your drone’s weight and your intended use.

    Recreational Flyers: If you fly purely for fun and personal use, you’re a recreational flyer. Here’s what you need to know:

    • Drones 250 grams and above must be registered with the FAA. Registration costs $5 and lasts three years. You register the drone, label it with your registration number, and you’re legal.
    • Drones under 250 grams do not need registration for recreational use. This is another reason the DJI Mini series is so popular with beginners.
    • You must pass The Recreational UAS Safety Test (TRUST), which is a free online test available from FAA-approved organizations. It takes about 30 minutes and the certificate has no expiration date.
    • You must fly below 400 feet in uncontrolled airspace.
    • You cannot fly over people or moving vehicles.
    • You cannot fly within 5 miles of an airport without checking airspace authorization through the FAA’s LAANC system (which is free and often gives near-instant authorization for certain areas).
    • You cannot fly at night without proper lighting on the drone.

    Commercial Operations: If you fly for any commercial purpose, even just posting your footage on a monetized YouTube channel, technically you are a commercial operator. This requires a Part 107 Remote Pilot Certificate, which involves passing a real knowledge test at an FAA-approved testing center. The test costs around $175 and requires studying FAA regulations, weather, airspace, and other topics.

    Many content creators and real estate photographers get their Part 107 specifically because it also opens up access to more airspace and allows waiver applications for specific operations.

    Apps to Know: The B4UFLY app (official FAA app) shows you airspace restrictions for your location. The AirMap app gives similar information. These are free and you should have at least one on your phone before every flight.

    In the European Union

    The EU has a common drone regulation system that applies across member states with some local variations.

    • All drones 250 grams and above must be registered with your national aviation authority. Most EU countries have online registration systems.
    • Sub-250g drones without cameras can be flown without registration. Sub-250g drones with cameras fall into the Open Category A1, which allows flight over uninvolved people in most conditions.
    • The Open Category A2 applies to drones in the 250g to 900g class. These require a self-declaration quiz and more careful operation planning.
    • Night flying, flying over crowds, and flying beyond visual line of sight all require additional authorizations.
    • The EU Drone Regulation website has detailed country-specific information.

    In Canada

    Transport Canada requires registration for drones 250 grams and above, and requires pilots to pass a knowledge test. The Small Advanced Operations and Small Basic Operations categories have different requirements based on where and how you fly.

    General Rules That Apply Almost Everywhere

    • Never fly near emergency operations (accidents, fires, police activity).
    • Never fly over crowds of people.
    • Always keep the drone within your visual line of sight unless specifically authorized.
    • Respect private property and don’t fly over private property without permission.
    • National parks in most countries have specific and often strict drone restrictions. Always check before flying in any protected area.

    Essential Accessories for Your First Drone

    Drone accessories are another area where marketing runs ahead of reality. Here’s what you actually need versus what’s nice to have.

    Actually Essential

    Extra Batteries: This is the most important accessory for any drone. One battery gives you maybe 20 to 25 minutes of real flying. Buy at least two extra batteries before your first real flying trip. Most manufacturers sell a “Fly More Combo” that includes extra batteries and a carrying case at a price that works out significantly cheaper than buying accessories separately.

    ND Filters: These are tinted filters that screw onto your drone’s camera lens and reduce the amount of light entering the sensor. For video shooting, you want to follow the 180-degree shutter rule, which means your shutter speed should be approximately double your frame rate. At 30fps, you want a 1/60 shutter. In bright daylight, an ND filter is how you achieve that without overexposing your footage. An ND 4/8/16/64 set is a good starting kit. These run $30 to $80 depending on quality.

    Carrying Case: Your drone is a precision instrument. Transporting it loose in a bag is asking for damage. Most Fly More combos include a shoulder bag. If yours doesn’t, buy a purpose-made case.

    SD Cards: Most drones need a high-speed microSD card. Get a card rated at V30 or above for 4K recording. The SanDisk Extreme line and Samsung Pro Endurance line are reliable choices. Buy at least 64GB, preferably 128GB.

    Nice to Have

    Landing Pad: A foldable landing pad gives you a clean, visible surface to take off from and land on. This is especially useful on grass or dirt where debris can get sucked into motors or camera lenses. They cost about $15 to $30 and fold down to nothing.

    Controller Holder for Phone: Most beginner drones use your smartphone as a screen. A controller that has a built-in phone holder is included, but if you’re using a tablet or larger phone, check that it fits the stock holder before assuming you need an upgrade.

    Propeller Guards: If you’re flying indoors or in close proximity to obstacles while learning, prop guards reduce damage from minor collisions. They add weight and reduce flight efficiency slightly, so most people take them off once they’re comfortable flying.

    Don’t Bother

    Drone Backpacks: Most are unnecessary bulk if your drone comes with a case. An exception is if you’re hiking significant distances to flying locations, in which case a drone-specific backpack distributes weight better.

    Third-Party Batteries: Tempting because they’re cheaper, but drone batteries communicate with the drone’s power management system. Third-party batteries can cause flight instability warnings or refuse to charge properly. Stick to manufacturer batteries, at least for your first drone.

    How to Learn to Fly: A Practical Approach for Beginners

    Buying the drone is the easy part. Actually learning to fly well takes time and intention. Here’s a structured approach that will save you frustration and money.

    Before Your First Flight: Homework Required

    1. Read the manual. This sounds obvious, but a huge percentage of beginners skip this and then wonder why their drone behaves unexpectedly. The manual covers the Return to Home behavior, low battery warnings, GPS lock requirements, and the specific behavior of different flight modes. Read it.
    2. Practice in the DJI Fly app simulator (or equivalent for your drone). Most modern drones have a simulator built into the app that uses the actual controller. Spend a few hours here before your first real flight.
    3. Check the airspace. Use B4UFLY or AirMap before every flight, especially when you’re getting started. Flying in controlled airspace without authorization is a real legal risk.
    4. Find an open space. Your first flights should happen in a large open area with no obstacles, preferably on a calm day. A soccer field, an empty parking lot, or a park with no trees nearby are ideal.

    Your First Real Flight Session

    Start with hover practice. Take off, let the drone hover at about five feet off the ground, and just watch it. Get comfortable with the idea that it’s going to hold position and not fall out of the sky. Most beginners are anxious the first time they fly and tend to over-correct. Give the drone a chance to show you what GPS stabilization actually does.

    Then practice very slow, deliberate movements. Move forward slowly, stop. Move left slowly, stop. Practice pivoting the drone to face different directions and then moving in those directions. The camera is your forward reference, and learning to think in the drone’s orientation rather than your own is one of the first real skills in drone flying.

    Practice landing. Landing is where most crashes happen. Bring the drone directly over the landing pad, descend slowly, and don’t rush it. Learn to use the automatic landing function and also how to land manually.

    Building Skills Over Time

    Once you’re comfortable with basic movement, start flying in sport mode for short periods to understand how the drone behaves at higher speeds. Learn to use the automated modes like QuickShots and Hyperlapse, which will give you impressive footage while you’re still building your manual skills.

    After a month of regular flying, try flying in a gentle crosswind. This is where you’ll really learn how to compensate for conditions. Then try flying in stronger wind. Understanding your drone’s limits and your own limits in different conditions is part of being a responsible pilot.

    FPV-Specific Learning Path

    If your goal is FPV, the path is different. Start in a simulator. Velocidrone, Liftoff, and DRL Simulator are all excellent options. Spend genuine hours here before touching hardware. Join local FPV communities; almost every city has an FPV racing or freestyle club and they’re usually happy to help beginners. Watch tutorials from experienced FPV pilots on YouTube. JoshardFPV, Mr. Steele, and Rotor Riot all have beginner-friendly content.

    When you do buy your first FPV hardware, consider starting with a whoops-class tiny whoop (a small, protected indoor quad) before moving to outdoor freestyle.

    Common Beginner Mistakes When Choosing and Flying Your First Drone

    Let’s talk about the mistakes people make, because learning from others’ expensive errors is genuinely valuable.

    Buying Without Knowing the Rules

    Flying a drone in a national park, over a crowd, or near an airport without authorization isn’t just illegal, it’s dangerous and it gives drone pilots everywhere a bad reputation. Don’t be the person who gets their drone confiscated by a ranger. Know the rules for your area before you fly.

    Buying the Wrong Category for Their Goals

    We covered this at the start, but it bears repeating. If you want to shoot cinematic footage and you buy an FPV racing quad, you’re going to be very frustrated. If you want to learn to race and you buy a camera drone, you’ll hit its ceiling fast. Be honest about what you want to do.

    Flying Without GPS Lock

    Your drone will tell you when it has a strong GPS lock, usually through the app showing the number of satellites and a solid positioning indicator. Don’t take off until you have GPS lock. Flying without it means you lose all the stabilization and Return to Home safety features. Beginners who ignore this end up chasing a drifting drone across a field.

    Ignoring Low Battery Warnings

    Every drone has multiple battery warning levels. When you get the first warning, start thinking about landing. When you get the critical warning, land immediately. The temptation to squeeze another two minutes out of a session has killed many drones. Lithium batteries don’t like being fully depleted; it degrades them quickly and can cause failures.

    Flying in Conditions Beyond Your Skill Level

    A 20 mph crosswind is manageable for an experienced pilot. For a beginner, it’s an invitation to a crash. Start flying in calm conditions, understand your own limits, and add challenge gradually. Most beginners push their skills and their drone further than they should in the first month.

    Not Calibrating Before Flights

    Most modern drones don’t require manual compass calibration before every flight, but when a new location is significantly different from where you last flew (especially magnetically, near large metal structures), calibration can help. Learn what your drone’s app tells you about calibration and pay attention to any warnings.

    Skipping the Fly More Combo

    This is a small but common financial mistake. If you buy a drone and then realize you need extra batteries and a bag, you’ll pay significantly more buying them separately than if you’d just bought the Fly More Combo from the start. Do the math before you check out.

    Choosing Your First Drone Platform Based on Your Specific Goals

    Let’s bring this together with specific recommendations based on what you actually want to do.

    You want to take beautiful travel videos and photos: Get the DJI Mini 4 Pro Fly More Combo. It’s the most capable beginner camera drone in a legal and practical package. If the budget is tight, the DJI Mini 3 is the next best choice.

    You’re on a strict budget under $300: The DJI Mini 3 (base model) is the first recommendation. If even that’s too much, look at the Holy Stone HS720E for a real GPS camera drone experience, understanding the image quality tradeoff.

    You want to get into FPV but you’re a complete beginner: Buy Velocidrone or Liftoff on Steam first. Spend a month in the simulator. Then buy the DJI Avata 2 for an FPV experience with training wheels, or jump straight to a 2.5-inch freestyle quad like the Geprc Cinelog 25 if you’re committed to learning proper manual flight.

    You want to do real estate aerial photography professionally: Get your FAA Part 107 certificate first, then buy the DJI Mini 4 Pro or Air 3 depending on your budget. If you’re going pro, treat this like buying a professional camera, invest in quality.

    You’re buying a drone for a kid: The DJI Mini 3 is actually appropriate for mature teenagers who will take it seriously. For younger kids or uncertain circumstances, the Ryze Tello is a better starting point because it’s safer and cheaper to crash.

    You want to fly indoors primarily: The DJI Avata 2 with its prop guards, a Ryze Tello, or a tiny whoop FPV quad are all better indoor choices than a standard camera drone. Standard camera drones in tight indoor spaces are just difficult to control without reliable GPS.

    What Nobody Tells You About Owning a Drone

    A few honest notes from people who’ve been flying for years and wished someone had told them these things upfront.

    The first crash will happen. Even with obstacle avoidance. Even with GPS. You will at some point misjudge, misread the environment, have a weird signal glitch, or just make a beginner’s mistake. Budget emotionally for this. The DJI Mini series is reasonably robust for minor crashes. DJI also offers DJI Care Refresh, an insurance plan that lets you replace a crashed drone for a significantly reduced fee. It’s worth considering if you’re worried about accidents, which all beginners should be.

    The battery situation is real. You’ll never feel like you have enough batteries. Even with three batteries and a charging hub, serious flying sessions feel too short. This is just the nature of the technology right now.

    You’ll become more aware of airspace. Within a few weeks of flying, you’ll start noticing restricted zones everywhere you go. You’ll look at every interesting location and think about whether you can fly there. The airspace awareness doesn’t go away; it becomes part of how you see the world.

    Great footage requires more than great hardware. The drone is a tool. Composition, timing, light, movement, and storytelling are what make drone footage actually compelling. Spend as much time thinking about how to shoot as you do thinking about what drone to buy.

    The community is genuinely great. There are local drone clubs in most cities. Online communities on Reddit (r/drones, r/fpv, r/djimini4pro) are active and helpful. If you get into this hobby, connecting with other pilots will accelerate your learning and make the hobby more enjoyable.

    Frequently Asked Questions About Choosing Your First Drone Platform

    Do I need a license to fly a drone? In the US, recreational flyers need to pass the free TRUST test and register drones over 250g. Commercial pilots need a FAA Part 107 certificate. Requirements vary by country, so always check your local aviation authority’s current rules.

    What’s the best first drone for beginners in 2025? The DJI Mini 4 Pro is the best all-around first drone for most people. The DJI Mini 3 is the best value option if budget is a consideration.

    How long does it take to learn to fly a drone? Basic competency comes within a few hours. Flying well enough to get consistently good footage takes weeks to months of regular practice. FPV flying takes longer, especially if you want to fly in Acro (manual) mode.

    Is DJI the only brand worth buying? DJI is the dominant choice for good reasons, but Autel makes genuinely competitive hardware, particularly the EVO Nano+ and EVO Lite+ series. For FPV components, brands like Betaflight, Foxeer, Caddx, and Geprc are widely respected.

    Can I fly a drone at the beach? Usually yes, but check local regulations. Many popular beaches are in controlled airspace or near restricted zones. Salt air is also hard on drones, so rinse with care and avoid flying in breaking surf.

    Should I buy a drone with or without a controller screen? The DJI RC series controllers have a built-in screen, which eliminates the need for your smartphone and avoids issues with phone holders, app notifications interrupting your flying session, and battery drain on your phone. For serious flying, a built-in screen controller is worth it.

    How do I protect my drone from crashes? DJI Care Refresh is the closest thing to real insurance. Fly cautiously especially while learning. Enable Return to Home. Keep your drone in visual line of sight. Enable obstacle avoidance features. And accept that occasional minor crashes are part of the learning process.

    What’s the difference between a camera drone and an FPV drone for beginners? Camera drones are GPS-stabilized, fly in a traditional third-person-view style, and are designed primarily for getting aerial footage. FPV drones are flown with goggles from a first-person perspective and prioritize agility and pilot skill over stability. They’re fundamentally different experiences requiring different skills.

    Final Thoughts: Making the Right Choice for You

    Choosing your first drone platform doesn’t have to be complicated if you start with the right questions. What do you actually want to do with it? How much are you willing to spend? What’s your tolerance for a learning curve?

    For the vast majority of people who want to capture aerial footage of their travels, their outdoor adventures, or just experience the joy of flying a real aircraft with their hands, the answer lands somewhere in the DJI Mini family. The technology has gotten genuinely good, the regulatory situation favors the sub-250g category, and the ecosystem of apps, tutorials, and community support makes learning accessible.

    If you want the FPV experience, plan for a longer journey, start in a simulator, and be patient with yourself. The payoff is extraordinary once you get there, but it takes more dedication upfront.

    Whatever you choose, go in with realistic expectations, respect the airspace and the people around you when you fly, and give yourself permission to take it slow at first. The drone hobby rewards patience and punishes overconfidence pretty reliably.

    Now go enjoy the sky. There’s nothing quite like the first time you hover a drone two hundred feet above a landscape you’ve only ever seen from the ground, and suddenly realize you can go anywhere.

    For detailed understanding of Platform Devices and Drivers on Linux, refer to the Linux documentation on Platform Devices and Drivers .

  • Complete Linux Block Device Driver Project: Kernel Driver + Userspace Access Program

    Complete Linux Block Device Driver Project tutorial covering kernel module development and userspace access program. Learn how to build, register, and test a block device driver in Linux with step-by-step code examples, real-world concepts, and performance insights for beginners and advanced developers.

    This is a complete, working project. By the end of this guide you will have a Linux block device driver running as a kernel module, a userspace C program that opens the device and performs raw read/write operations on it, a working Makefile that builds both, and a clear understanding of every line of code.

    No hand-waving. No “left as an exercise.” Every file is here, complete and ready to compile.

    This is the kind of project that actually belongs in a portfolio if you are looking for embedded Linux or Linux kernel driver roles. It touches kernel module development, block layer internals, device node access from userspace, raw sector I/O, and ioctl communication all in one project.

    Before diving into implementation, it’s important to understand the fundamentals of how block device drivers work in Linux. If you’re new to this topic, check out this Linux Block Device Drivers: The Complete Beginner’s Guide, which explains core concepts like request queues, buffering, and kernel interactions in a simple and beginner-friendly way.

    Linux Block Device Driver Project

    1. Project Overview and Architecture

    Here is what we are building and how the pieces connect:

    
    +---------------------------+
    |     Userspace Program     |  userapp.c
    |  open() / read() / write()|
    |  ioctl() / lseek()        |
    +------------+--------------+
                 |
                 | /dev/myblkdev  (block device node)
                 |
    +------------+--------------+
    |      Linux Block Layer    |  Kernel block layer
    |  bio, request queue,      |
    |  blk-mq, scheduler        |
    +------------+--------------+
                 |
    +------------+--------------+
    |   myblkdev.ko             |  Our kernel module
    |   RAM-backed block driver |
    |   16MB virtual disk       |
    |   ioctl for device info   |
    +---------------------------+
                 |
         vmalloc'd RAM buffer
         (simulates disk storage)
    

    The kernel module registers a block device backed by a 16MB chunk of kernel RAM. It handles read and write requests through the blk-mq interface. It also exposes an ioctl command so userspace can query device information like size and sector count.

    The userspace program opens the device node directly using open(), writes a pattern to specific sectors using write(), reads it back and verifies it, and calls ioctl() to print device info.

    This is exactly how tools like dd, hdparm, and storage benchmark tools work at the lowest level.

    2. Prerequisites and Environment Setup

    Before you start, make sure your system has everything needed:

    # Install kernel headers for your running kernel
    sudo apt-get update
    sudo apt-get install linux-headers-$(uname -r) build-essential
    
    # Verify kernel headers are present
    ls /lib/modules/$(uname -r)/build
    # Should show a directory, not an error
    
    # Check your kernel version
    uname -r
    # This project is tested on 5.15+ and 6.x kernels

    You also need to run the load and test steps as root or with sudo. Block devices require root access for raw sector I/O from userspace.

    If you are on a VM (recommended for kernel development), make sure you can do sudo insmod and that your VM has at least 256MB of RAM free for the driver’s buffer plus kernel overhead.

    3. Project Directory Structure

    Create this layout on your machine:

    myblkdev/
    ├── myblkdev.c       # Kernel block device driver
    ├── myblkdev.h      # Shared header (kernel + userspace)
    ├── userapp.c         # Userspace test and access program
    └── Makefile           # Builds both kernel module and userapp
    mkdir myblkdev
    cd myblkdev

    All four files go in this single directory. The Makefile handles building the kernel module (which goes through the kernel build system) and the userspace binary (which is just a normal gcc compile) in one make command.

    4. Shared Header File : myblkdev.h

    This header is included by both the kernel driver and the userspace program. It defines the ioctl command numbers and the data structure used to exchange device information. Sharing this header between kernel and userspace is the standard kernel pattern — it ensures both sides agree on the exact binary layout of ioctl structures.

    /* myblkdev.h
     * Shared header between kernel driver and userspace program.
     * Defines ioctl interface for myblkdev block device driver.
     */
    
    #ifndef MYBLKDEV_H
    #define MYBLKDEV_H
    
    #include <linux/ioctl.h>
    
    /* Magic number for our driver's ioctl commands.
     * Pick something unlikely to conflict. Check Documentation/userspace-api/ioctl/ioctl-number.rst
     */
    #define MYBLKDEV_MAGIC  0xBD
    
    /* Device info structure returned by MYBLKDEV_GET_INFO ioctl */
    struct myblkdev_info {
        unsigned long total_bytes;    /* total device size in bytes */
        unsigned long sector_count;   /* total number of 512-byte sectors */
        unsigned int  sector_size;    /* sector size in bytes (always 512 here) */
        unsigned int  major;          /* device major number */
        unsigned int  minor;          /* device minor number */
    };
    
    /* ioctl command: get device info
     * Direction: kernel -> userspace (IOR = read from kernel's perspective)
     * Type: MYBLKDEV_MAGIC
     * Number: 1
     * Size: sizeof(struct myblkdev_info)
     */
    #define MYBLKDEV_GET_INFO  _IOR(MYBLKDEV_MAGIC, 1, struct myblkdev_info)
    
    /* ioctl command: reset device (zero all storage)
     * Direction: no data transfer
     * Type: MYBLKDEV_MAGIC
     * Number: 2
     */
    #define MYBLKDEV_RESET     _IO(MYBLKDEV_MAGIC, 2)
    
    #endif /* MYBLKDEV_H */

    The _IOR and _IO macros encode the direction, magic number, command number, and data size into a single 32-bit integer. This encoding prevents different drivers from accidentally sharing the same ioctl number, which would cause the wrong driver to handle the command.

    5. The Kernel Block Device Driver : myblkdev.c

    This is the full kernel driver. Read through it section by section — every part is commented to explain what it does and why.

    /* myblkdev.c
     * A RAM-backed Linux block device driver with ioctl support.
     * Registers /dev/myblkdev as a 16MB block device.
     *
     * Tested on Linux 5.15 - 6.x
     * License: GPL v2
     */
    
    #include <linux/module.h>
    #include <linux/kernel.h>
    #include <linux/init.h>
    #include <linux/fs.h>
    #include <linux/blkdev.h>
    #include <linux/blk-mq.h>
    #include <linux/genhd.h>
    #include <linux/hdreg.h>
    #include <linux/vmalloc.h>
    #include <linux/uaccess.h>
    #include "myblkdev.h"
    
    MODULE_LICENSE("GPL");
    MODULE_AUTHOR("myblkdev project");
    MODULE_DESCRIPTION("RAM-backed block device driver with ioctl");
    MODULE_VERSION("1.0");
    
    /* ===== Configuration ===== */
    #define MYBLKDEV_MAJOR       240        /* static major; 240-254 are for local use */
    #define MYBLKDEV_NAME        "myblkdev"
    #define MYBLKDEV_MINORS      1          /* 1 = no partitions; use 16 to allow partitions */
    #define DISK_SIZE_MB         16
    #define KERNEL_SECTOR_SIZE   512
    
    /* ===== Device State ===== */
    struct myblkdev_state {
        unsigned long    size;          /* device size in bytes */
        u8              *data;          /* vmalloc'd storage buffer */
        spinlock_t       lock;          /* protects data access */
        struct blk_mq_tag_set  tag_set;
        struct request_queue  *queue;
        struct gendisk        *gd;
        int              major;
        int              minor;
    };
    
    /* Single global device instance for this example */
    static struct myblkdev_state *mydev;
    
    /* ===== Request Handler ===== */
    /*
     * This is the core of the driver. The block layer calls this function
     * for every I/O request. We iterate over each segment of the request,
     * copy data to/from our RAM buffer, and signal completion.
     */
    static blk_status_t myblkdev_queue_rq(struct blk_mq_hw_ctx *hctx,
                                           const struct blk_mq_queue_data *bd)
    {
        struct request        *req  = bd->rq;
        struct myblkdev_state *dev  = req->q->queuedata;
        struct bio_vec         bvec;
        struct req_iterator    iter;
        loff_t                 pos;
        unsigned long          flags;
    
        /* Mark request as started — required by blk-mq before any processing */
        blk_mq_start_request(req);
    
        /* Reject non-filesystem requests (SCSI passthrough, etc.) */
        if (blk_rq_is_passthrough(req)) {
            pr_notice(MYBLKDEV_NAME ": skip passthrough request\n");
            blk_mq_end_request(req, BLK_STS_IOERR);
            return BLK_STS_OK;
        }
    
        /* Convert starting sector to byte offset.
         * blk_rq_pos() returns offset in 512-byte units always. */
        pos = (loff_t)blk_rq_pos(req) * KERNEL_SECTOR_SIZE;
    
        spin_lock_irqsave(&dev->lock, flags);
    
        /* Iterate over each scatter-gather segment in the request */
        rq_for_each_segment(bvec, req, iter) {
            void   *buf = page_address(bvec.bv_page) + bvec.bv_offset;
            size_t  len = bvec.bv_len;
    
            /* Bounds check — never go past our buffer */
            if (pos + len > dev->size) {
                pr_err(MYBLKDEV_NAME ": I/O beyond device size "
                       "(pos=%lld len=%zu size=%lu)\n",
                       pos, len, dev->size);
                spin_unlock_irqrestore(&dev->lock, flags);
                blk_mq_end_request(req, BLK_STS_IOERR);
                return BLK_STS_OK;
            }
    
            if (rq_data_dir(req) == WRITE) {
                /* WRITE: copy from bio page into our RAM buffer */
                memcpy(dev->data + pos, buf, len);
            } else {
                /* READ: copy from our RAM buffer into bio page */
                memcpy(buf, dev->data + pos, len);
            }
    
            pos += len;
        }
    
        spin_unlock_irqrestore(&dev->lock, flags);
    
        /* Signal successful completion to the block layer */
        blk_mq_end_request(req, BLK_STS_OK);
        return BLK_STS_OK;
    }
    
    /* blk-mq operations table — only queue_rq is mandatory */
    static const struct blk_mq_ops myblkdev_mq_ops = {
        .queue_rq = myblkdev_queue_rq,
    };
    
    /* ===== ioctl Handler ===== */
    /*
     * Userspace programs can call ioctl() on the block device fd to
     * get device info or trigger a reset. We handle our custom commands
     * here and return -ENOTTY for anything we don't recognize.
     */
    static int myblkdev_ioctl(struct block_device *bdev, fmode_t mode,
                               unsigned int cmd, unsigned long arg)
    {
        struct myblkdev_state *dev = bdev->bd_disk->private_data;
        struct myblkdev_info   info;
        unsigned long          flags;
    
        switch (cmd) {
    
        case MYBLKDEV_GET_INFO:
            /* Fill info structure and copy to userspace */
            info.total_bytes  = dev->size;
            info.sector_count = dev->size / KERNEL_SECTOR_SIZE;
            info.sector_size  = KERNEL_SECTOR_SIZE;
            info.major        = dev->major;
            info.minor        = dev->minor;
    
            if (copy_to_user((void __user *)arg, &info, sizeof(info)))
                return -EFAULT;
            return 0;
    
        case MYBLKDEV_RESET:
            /* Zero the entire storage buffer */
            spin_lock_irqsave(&dev->lock, flags);
            memset(dev->data, 0, dev->size);
            spin_unlock_irqrestore(&dev->lock, flags);
            pr_info(MYBLKDEV_NAME ": device reset (zeroed)\n");
            return 0;
    
        default:
            /* Unknown command — return standard "not a typewriter" error */
            return -ENOTTY;
        }
    }
    
    /* ===== Block Device Operations Table ===== */
    static const struct block_device_operations myblkdev_fops = {
        .owner          = THIS_MODULE,
        .ioctl          = myblkdev_ioctl,
    };
    
    /* ===== Module Init ===== */
    static int __init myblkdev_init(void)
    {
        int ret;
    
        pr_info(MYBLKDEV_NAME ": initializing %d MB RAM block device\n",
                DISK_SIZE_MB);
    
        /* Allocate our device state structure */
        mydev = kzalloc(sizeof(*mydev), GFP_KERNEL);
        if (!mydev) {
            pr_err(MYBLKDEV_NAME ": failed to allocate device state\n");
            return -ENOMEM;
        }
    
        mydev->size  = DISK_SIZE_MB * 1024 * 1024;
        mydev->major = MYBLKDEV_MAJOR;
        mydev->minor = 0;
        spin_lock_init(&mydev->lock);
    
        /* Allocate the RAM storage buffer using vmalloc.
         * We use vmalloc (not kmalloc) because we need a large contiguous
         * virtual mapping but don't need physically contiguous memory. */
        mydev->data = vmalloc(mydev->size);
        if (!mydev->data) {
            pr_err(MYBLKDEV_NAME ": failed to allocate %d MB storage\n",
                   DISK_SIZE_MB);
            ret = -ENOMEM;
            goto err_free_dev;
        }
        memset(mydev->data, 0, mydev->size);
    
        /* Register the block device major number */
        ret = register_blkdev(MYBLKDEV_MAJOR, MYBLKDEV_NAME);
        if (ret < 0) {
            pr_err(MYBLKDEV_NAME ": register_blkdev failed (%d)\n", ret);
            goto err_free_data;
        }
    
        /* Configure blk-mq tag set.
         * nr_hw_queues=1: single hardware queue (fine for RAM, no real HW)
         * queue_depth=128: up to 128 in-flight requests at once */
        mydev->tag_set.ops          = &myblkdev_mq_ops;
        mydev->tag_set.nr_hw_queues = 1;
        mydev->tag_set.queue_depth  = 128;
        mydev->tag_set.numa_node    = NUMA_NO_NODE;
        mydev->tag_set.cmd_size     = 0;
        mydev->tag_set.flags        = BLK_MQ_F_SHOULD_MERGE;
    
        ret = blk_mq_alloc_tag_set(&mydev->tag_set);
        if (ret) {
            pr_err(MYBLKDEV_NAME ": blk_mq_alloc_tag_set failed (%d)\n", ret);
            goto err_unreg_blkdev;
        }
    
        /* Create the request queue linked to our tag set */
        mydev->queue = blk_mq_init_queue(&mydev->tag_set);
        if (IS_ERR(mydev->queue)) {
            ret = PTR_ERR(mydev->queue);
            pr_err(MYBLKDEV_NAME ": blk_mq_init_queue failed (%d)\n", ret);
            goto err_free_tag_set;
        }
    
        /* Store device pointer in queue for access from request handler */
        mydev->queue->queuedata = mydev;
    
        /* Set queue limits — tell the block layer what our "hardware" supports */
        blk_queue_logical_block_size(mydev->queue, KERNEL_SECTOR_SIZE);
        blk_queue_max_hw_sectors(mydev->queue, 256); /* max 128KB per request */
    
        /* Allocate the gendisk structure.
         * MYBLKDEV_MINORS=1 means no partition support.
         * Use 16 if you want to allow up to 15 partitions. */
        mydev->gd = alloc_disk(MYBLKDEV_MINORS);
        if (!mydev->gd) {
            pr_err(MYBLKDEV_NAME ": alloc_disk failed\n");
            ret = -ENOMEM;
            goto err_free_queue;
        }
    
        /* Fill in gendisk fields */
        mydev->gd->major        = MYBLKDEV_MAJOR;
        mydev->gd->first_minor  = 0;
        mydev->gd->fops         = &myblkdev_fops;
        mydev->gd->queue        = mydev->queue;
        mydev->gd->private_data = mydev;
        snprintf(mydev->gd->disk_name, sizeof(mydev->gd->disk_name),
                 MYBLKDEV_NAME);
    
        /* Set disk capacity in 512-byte sectors */
        set_capacity(mydev->gd, mydev->size / KERNEL_SECTOR_SIZE);
    
        /* add_disk() makes the device visible — /dev/myblkdev appears after this */
        add_disk(mydev->gd);
    
        pr_info(MYBLKDEV_NAME ": ready — /dev/%s, major=%d, size=%lu MB\n",
                mydev->gd->disk_name, MYBLKDEV_MAJOR,
                mydev->size / (1024 * 1024));
        return 0;
    
    /* Error cleanup — reverse order of initialization */
    err_free_queue:
        blk_cleanup_queue(mydev->queue);
    err_free_tag_set:
        blk_mq_free_tag_set(&mydev->tag_set);
    err_unreg_blkdev:
        unregister_blkdev(MYBLKDEV_MAJOR, MYBLKDEV_NAME);
    err_free_data:
        vfree(mydev->data);
    err_free_dev:
        kfree(mydev);
        return ret;
    }
    
    /* ===== Module Exit ===== */
    static void __exit myblkdev_exit(void)
    {
        /* Cleanup in strict reverse order of init */
        del_gendisk(mydev->gd);          /* remove from block layer */
        put_disk(mydev->gd);             /* release gendisk reference */
        blk_cleanup_queue(mydev->queue); /* destroy request queue */
        blk_mq_free_tag_set(&mydev->tag_set);
        unregister_blkdev(MYBLKDEV_MAJOR, MYBLKDEV_NAME);
        vfree(mydev->data);              /* free RAM storage */
        kfree(mydev);                    /* free device state */
    
        pr_info(MYBLKDEV_NAME ": unloaded\n");
    }
    
    module_init(myblkdev_init);
    module_exit(myblkdev_exit);
    

    6. The Makefile

    This single Makefile builds both the kernel module and the userspace program. Run make once and you get both.

    # Makefile for myblkdev project
    # Builds kernel module (myblkdev.ko) and userspace program (userapp)
    
    # Kernel build directory — uses headers for currently running kernel
    KDIR ?= /lib/modules/$(shell uname -r)/build
    
    # Kernel module object
    obj-m += myblkdev.o
    
    # Default target: build kernel module then userspace app
    all: module userapp
    
    module:
    	$(MAKE) -C $(KDIR) M=$(PWD) modules
    
    # Userspace app: plain gcc, no kernel headers needed
    # _GNU_SOURCE for pread/pwrite, O_DIRECT etc.
    userapp: userapp.c myblkdev.h
    	gcc -Wall -Wextra -O2 -D_GNU_SOURCE -o userapp userapp.c
    
    clean:
    	$(MAKE) -C $(KDIR) M=$(PWD) clean
    	rm -f userapp
    
    .PHONY: all module userapp clean

    The kernel module build goes through the kernel’s own build system (make -C $(KDIR)). The userspace binary is just a normal gcc compile. The shared myblkdev.h header is included by both — that dependency is declared on the userapp line so it rebuilds if the header changes.

    7. The Userspace Access Program : userapp.c

    This program demonstrates every way a userspace application can interact with a raw block device. It opens the device node directly, queries info via ioctl, writes test patterns to specific sectors, reads them back, and verifies the data.

    /* userapp.c
     * Userspace program to test and demonstrate myblkdev block driver access.
     * Performs: ioctl info query, raw sector write, raw sector read, verify.
     *
     * Run as root: sudo ./userapp /dev/myblkdev
     */
    
    #include <stdio.h>
    #include <stdlib.h>
    #include <string.h>
    #include <unistd.h>
    #include <fcntl.h>
    #include <errno.h>
    #include <sys/ioctl.h>
    #include <sys/types.h>
    
    /* Include our shared header.
     * For userspace, linux/ioctl.h is included via sys/ioctl.h already.
     * We redefine to use userspace-safe types. */
    #include "myblkdev.h"
    
    #define SECTOR_SIZE     512
    #define TEST_SECTORS    8       /* write/read 8 sectors = 4KB at a time */
    #define TEST_PATTERN    0xAB    /* byte pattern to write for verification */
    
    /* ===== Helper: print device info from ioctl ===== */
    static void print_device_info(int fd)
    {
        struct myblkdev_info info;
    
        printf("\n--- Device Info (via ioctl) ---\n");
    
        if (ioctl(fd, MYBLKDEV_GET_INFO, &info) < 0) {
            perror("ioctl MYBLKDEV_GET_INFO failed");
            return;
        }
    
        printf("  Total Size   : %lu bytes (%lu MB)\n",
               info.total_bytes, info.total_bytes / (1024 * 1024));
        printf("  Sector Count : %lu sectors\n", info.sector_count);
        printf("  Sector Size  : %u bytes\n", info.sector_size);
        printf("  Major Number : %u\n", info.major);
        printf("  Minor Number : %u\n", info.minor);
        printf("-------------------------------\n\n");
    }
    
    /* ===== Helper: write pattern to a sector range ===== */
    static int write_sectors(int fd, off_t start_sector,
                              int num_sectors, unsigned char pattern)
    {
        size_t   buf_size = num_sectors * SECTOR_SIZE;
        unsigned char *buf;
        ssize_t  written;
        off_t    offset = start_sector * SECTOR_SIZE;
    
        buf = malloc(buf_size);
        if (!buf) {
            fprintf(stderr, "malloc failed\n");
            return -1;
        }
    
        /* Fill buffer with test pattern */
        memset(buf, pattern, buf_size);
    
        /* Seek to the correct byte offset on the block device */
        if (lseek(fd, offset, SEEK_SET) < 0) {
            perror("lseek failed");
            free(buf);
            return -1;
        }
    
        /* Write the buffer — this goes through VFS -> block layer -> our driver */
        written = write(fd, buf, buf_size);
        if (written != (ssize_t)buf_size) {
            fprintf(stderr, "write: expected %zu bytes, got %zd (%s)\n",
                    buf_size, written, strerror(errno));
            free(buf);
            return -1;
        }
    
        printf("[WRITE] Sector %ld - %ld: wrote %zu bytes, pattern=0x%02X\n",
               (long)start_sector, (long)(start_sector + num_sectors - 1),
               buf_size, pattern);
    
        free(buf);
        return 0;
    }
    
    /* ===== Helper: read from sector range and verify pattern ===== */
    static int read_and_verify(int fd, off_t start_sector,
                                int num_sectors, unsigned char expected_pattern)
    {
        size_t    buf_size = num_sectors * SECTOR_SIZE;
        unsigned char *buf;
        ssize_t   bytes_read;
        off_t     offset = start_sector * SECTOR_SIZE;
        int       errors = 0;
        size_t    i;
    
        buf = malloc(buf_size);
        if (!buf) {
            fprintf(stderr, "malloc failed\n");
            return -1;
        }
    
        /* Seek to sector offset */
        if (lseek(fd, offset, SEEK_SET) < 0) {
            perror("lseek failed");
            free(buf);
            return -1;
        }
    
        /* Read back the data */
        bytes_read = read(fd, buf, buf_size);
        if (bytes_read != (ssize_t)buf_size) {
            fprintf(stderr, "read: expected %zu bytes, got %zd (%s)\n",
                    buf_size, bytes_read, strerror(errno));
            free(buf);
            return -1;
        }
    
        /* Verify every byte matches the expected pattern */
        for (i = 0; i < buf_size; i++) {
            if (buf[i] != expected_pattern) {
                fprintf(stderr, "[VERIFY] Mismatch at byte %zu: "
                        "got 0x%02X, expected 0x%02X\n",
                        i, buf[i], expected_pattern);
                errors++;
                if (errors > 5) {
                    fprintf(stderr, "[VERIFY] Too many errors, stopping\n");
                    break;
                }
            }
        }
    
        if (errors == 0) {
            printf("[READ]  Sector %ld - %ld: read %zu bytes — VERIFIED OK "
                   "(pattern=0x%02X)\n",
                   (long)start_sector,
                   (long)(start_sector + num_sectors - 1),
                   buf_size, expected_pattern);
        } else {
            printf("[READ]  Sector %ld - %ld: VERIFICATION FAILED "
                   "(%d errors)\n",
                   (long)start_sector,
                   (long)(start_sector + num_sectors - 1),
                   errors);
        }
    
        free(buf);
        return errors ? -1 : 0;
    }
    
    /* ===== Helper: dump first 64 bytes of a sector as hex ===== */
    static void hexdump_sector(int fd, off_t sector)
    {
        unsigned char buf[64];
        ssize_t       n;
        size_t        i;
    
        lseek(fd, sector * SECTOR_SIZE, SEEK_SET);
        n = read(fd, buf, sizeof(buf));
        if (n <= 0) {
            perror("hexdump read failed");
            return;
        }
    
        printf("\n[HEXDUMP] First 64 bytes of sector %ld:\n", (long)sector);
        for (i = 0; i < (size_t)n; i++) {
            if (i % 16 == 0) printf("  %04zx: ", i);
            printf("%02x ", buf[i]);
            if (i % 16 == 15) printf("\n");
        }
        printf("\n");
    }
    
    /* ===== Helper: reset device via ioctl ===== */
    static void reset_device(int fd)
    {
        printf("[RESET] Sending MYBLKDEV_RESET ioctl...\n");
        if (ioctl(fd, MYBLKDEV_RESET) < 0) {
            perror("ioctl MYBLKDEV_RESET failed");
            return;
        }
        printf("[RESET] Device zeroed successfully\n");
    }
    
    /* ===== Main ===== */
    int main(int argc, char *argv[])
    {
        const char *devpath;
        int         fd;
        int         ret = 0;
    
        if (argc < 2) {
            fprintf(stderr, "Usage: %s \n", argv[0]);
            fprintf(stderr, "Example: sudo %s /dev/myblkdev\n", argv[0]);
            return EXIT_FAILURE;
        }
    
        devpath = argv[1];
    
        printf("===========================================\n");
        printf("  myblkdev Userspace Test Program\n");
        printf("  Device: %s\n", devpath);
        printf("===========================================\n");
    
        /* Open the block device.
         * O_RDWR: we need both read and write access.
         * O_SYNC: write() calls wait for I/O completion before returning.
         *         Important for testing — without this, writes may be
         *         cached by the page cache and not reach the driver immediately. */
        fd = open(devpath, O_RDWR | O_SYNC);
        if (fd < 0) {
            fprintf(stderr, "open(%s) failed: %s\n", devpath, strerror(errno));
            fprintf(stderr, "Did you load the module? Are you running as root?\n");
            return EXIT_FAILURE;
        }
    
        printf("[OPEN]  Opened %s successfully (fd=%d)\n\n", devpath, fd);
    
        /* Step 1: Query device info via ioctl */
        print_device_info(fd);
    
        /* Step 2: Write pattern 0xAB to sectors 0-7 (first 4KB) */
        printf("--- Test 1: Write and Read First 4KB ---\n");
        if (write_sectors(fd, 0, TEST_SECTORS, TEST_PATTERN) < 0) {
            ret = 1;
            goto out;
        }
    
        /* Step 3: Read back and verify */
        if (read_and_verify(fd, 0, TEST_SECTORS, TEST_PATTERN) < 0) {
            ret = 1;
            goto out;
        }
    
        /* Step 4: Hexdump sector 0 to visually confirm */
        hexdump_sector(fd, 0);
    
        /* Step 5: Write different pattern to a sector in the middle of the disk */
        printf("\n--- Test 2: Write and Read Middle of Disk ---\n");
        {
            off_t mid_sector = (DISK_SIZE_MB * 1024 * 1024 / SECTOR_SIZE) / 2;
            printf("[INFO]  Mid-disk sector: %ld\n", (long)mid_sector);
    
            if (write_sectors(fd, mid_sector, TEST_SECTORS, 0xCD) < 0) {
                ret = 1;
                goto out;
            }
            if (read_and_verify(fd, mid_sector, TEST_SECTORS, 0xCD) < 0) {
                ret = 1;
                goto out;
            }
            hexdump_sector(fd, mid_sector);
        }
    
        /* Step 6: Verify sector 0 still has original pattern
         * (mid-disk write must not have corrupted sector 0) */
        printf("\n--- Test 3: Re-verify Sector 0 (Isolation Check) ---\n");
        if (read_and_verify(fd, 0, TEST_SECTORS, TEST_PATTERN) < 0) {
            ret = 1;
            goto out;
        }
    
        /* Step 7: Reset device and verify sector 0 is now zeroed */
        printf("\n--- Test 4: Reset Device and Verify Zeroed ---\n");
        reset_device(fd);
        if (read_and_verify(fd, 0, TEST_SECTORS, 0x00) < 0) {
            ret = 1;
            goto out;
        }
    
        printf("\n===========================================\n");
        if (ret == 0)
            printf("  ALL TESTS PASSED\n");
        else
            printf("  SOME TESTS FAILED — check output above\n");
        printf("===========================================\n");
    
    out:
        close(fd);
        return ret ? EXIT_FAILURE : EXIT_SUCCESS;
    }
    

    8. How the ioctl Interface Works

    The ioctl path is worth understanding clearly because it is the standard way userspace programs communicate non-I/O control information to block and character drivers.

    When userspace calls:

    ioctl(fd, MYBLKDEV_GET_INFO, &info);

    The kernel routes this through VFS to blkdev_ioctl() in the block layer, which checks if it is a standard block ioctl (like BLKGETSIZE, BLKRRPART). If not recognized, it calls your driver’s .ioctl function pointer — which is myblkdev_ioctl() in our driver.

    Inside the driver, copy_to_user() safely copies data from kernel space to the userspace buffer pointer that was passed in as the third argument. You must always use copy_to_user and copy_from_user for this — never dereference a userspace pointer directly in kernel code. It will either fault or silently access wrong memory.

    The _IOR, _IOW, _IOWR, and _IO macros encode direction and size into the command number so the kernel’s ioctl dispatch can do basic sanity checking on the argument size before even calling your handler.

    9. Build, Load, and Run : Step by Step

    # Step 1: Build everything
    cd myblkdev
    make
    
    # You should see:
    # CC [M] /path/to/myblkdev/myblkdev.o
    # LD [M] /path/to/myblkdev/myblkdev.ko
    # gcc -Wall -Wextra -O2 -D_GNU_SOURCE -o userapp userapp.c
    
    # Step 2: Load the kernel module
    sudo insmod myblkdev.ko
    
    # Step 3: Verify it loaded and device node exists
    dmesg | tail -5
    # Expected: myblkdev: ready — /dev/myblkdev, major=240, size=16 MB
    
    ls -la /dev/myblkdev
    # Expected: brw-rw---- 1 root disk 240, 0 ... /dev/myblkdev
    
    cat /proc/devices | grep myblkdev
    # Expected: 240 myblkdev
    
    # Step 4: Run the userspace test program
    sudo ./userapp /dev/myblkdev
    
    # Step 5: When done, unload the module
    sudo rmmod myblkdev
    dmesg | tail -3
    # Expected: myblkdev: unloaded

    10. Expected Output

    When you run sudo ./userapp /dev/myblkdev you should see exactly this:

    ===========================================
      myblkdev Userspace Test Program
      Device: /dev/myblkdev
    ===========================================
    [OPEN]  Opened /dev/myblkdev successfully (fd=3)
    
    --- Device Info (via ioctl) ---
      Total Size   : 16777216 bytes (16 MB)
      Sector Count : 32768 sectors
      Sector Size  : 512 bytes
      Major Number : 240
      Minor Number : 0
    -------------------------------
    
    --- Test 1: Write and Read First 4KB ---
    [WRITE] Sector 0 - 7: wrote 4096 bytes, pattern=0xAB
    [READ]  Sector 0 - 7: read 4096 bytes — VERIFIED OK (pattern=0xAB)
    
    [HEXDUMP] First 64 bytes of sector 0:
      0000: ab ab ab ab ab ab ab ab ab ab ab ab ab ab ab ab
      0010: ab ab ab ab ab ab ab ab ab ab ab ab ab ab ab ab
      0020: ab ab ab ab ab ab ab ab ab ab ab ab ab ab ab ab
      0030: ab ab ab ab ab ab ab ab ab ab ab ab ab ab ab ab
    
    --- Test 2: Write and Read Middle of Disk ---
    [INFO]  Mid-disk sector: 16384
    [WRITE] Sector 16384 - 16391: wrote 4096 bytes, pattern=0xCD
    [READ]  Sector 16384 - 16391: read 4096 bytes — VERIFIED OK (pattern=0xCD)
    
    [HEXDUMP] First 64 bytes of sector 16384:
      0000: cd cd cd cd cd cd cd cd cd cd cd cd cd cd cd cd
      ...
    
    --- Test 3: Re-verify Sector 0 (Isolation Check) ---
    [READ]  Sector 0 - 7: read 4096 bytes — VERIFIED OK (pattern=0xAB)
    
    --- Test 4: Reset Device and Verify Zeroed ---
    [RESET] Sending MYBLKDEV_RESET ioctl...
    [RESET] Device zeroed successfully
    [READ]  Sector 0 - 7: read 4096 bytes — VERIFIED OK (pattern=0x00)
    
    ===========================================
      ALL TESTS PASSED
    ===========================================

    11. How Userspace Actually Talks to the Block Driver

    This is worth tracing through the full kernel call path for both the write and ioctl cases, because understanding this path is what separates someone who just ran the code from someone who actually understands it.

    write() Call Path

    userapp: write(fd, buf, 4096)
      |
      v
    syscall: sys_write()
      |
      v
    VFS: vfs_write() -> block_write_iter()
      |
      v
    Page Cache: data written to page cache first
      |
      v (O_SYNC forces immediate flush)
    Block Layer: submit_bio()
      -> bio created with our data pages
      -> bio submitted to request queue
      -> blk-mq merges/dispatches
      |
      v
    myblkdev_queue_rq()  <-- OUR DRIVER
      -> rq_for_each_segment loops over bio_vec segments
      -> memcpy(dev->data + pos, buf, len)  for WRITE
      -> blk_mq_end_request(req, BLK_STS_OK)
      |
      v
    Block layer signals completion
      -> page cache marks page clean (O_SYNC path)
      |
      v
    write() returns 4096 to userspace

    ioctl() Call Path

    userapp: ioctl(fd, MYBLKDEV_GET_INFO, &info)
      |
      v
    syscall: sys_ioctl()
      |
      v
    VFS: vfs_ioctl() -> blkdev_ioctl()
      |
      v (not a standard block ioctl)
    myblkdev_ioctl()  <-- OUR DRIVER
      -> copy_to_user(&info, kernel_info, sizeof(info))
      -> return 0
      |
      v
    ioctl() returns 0 to userspace
    userspace info struct now has device data

    The key thing to notice: userspace never directly accesses the driver’s memory. Everything goes through the kernel’s VFS and block layer. The copy_to_user() in the driver is the only point where kernel-owned data crosses into user-owned memory, and it does so safely through kernel-controlled copy routines that check permissions.

    12. Extending the Project

    Here are four concrete things you can add to this project to take it further:

    Add Partition Support

    Change MYBLKDEV_MINORS from 1 to 16. Then after loading, run fdisk /dev/myblkdev to create partitions. The kernel will automatically create /dev/myblkdev1, /dev/myblkdev2, etc. Your driver handles them with zero additional code because the block layer translates offsets for you.

    Add a Module Parameter for Disk Size

    static int disk_size_mb = DISK_SIZE_MB;
    module_param(disk_size_mb, int, 0444);
    MODULE_PARM_DESC(disk_size_mb, "Disk size in MB (default 16)");

    Then load with: sudo insmod myblkdev.ko disk_size_mb=64

    Add Multiple Device Instances

    Change the single global device to an array and support creating multiple devices at load time, like the real brd driver does with /dev/ram0, /dev/ram1, etc.

    Format and Mount It

    sudo mkfs.ext4 /dev/myblkdev
    sudo mkdir /mnt/myblkdev
    sudo mount /dev/myblkdev /mnt/myblkdev
    echo "data survives in RAM until rmmod" | sudo tee /mnt/myblkdev/note.txt
    cat /mnt/myblkdev/note.txt
    sudo umount /mnt/myblkdev

    13. Troubleshooting Common Errors

    insmod: ERROR: could not insert module myblkdev.ko: Invalid module format

    Your kernel headers do not match your running kernel. Run uname -r and verify that /lib/modules/$(uname -r)/build exists and matches. On Ubuntu after a kernel update, run sudo apt-get install linux-headers-$(uname -r) again.

    open(/dev/myblkdev) failed: No such file or directory

    The module is not loaded or load failed. Run dmesg | tail -20 to see the error. Also check lsmod | grep myblkdev.

    open(/dev/myblkdev) failed: Permission denied

    Run with sudo. Block devices require root for raw access. Alternatively: sudo chmod 666 /dev/myblkdev for testing only.

    ioctl MYBLKDEV_GET_INFO failed: Inappropriate ioctl for device

    This means the ioctl command number does not match between userapp and the loaded driver. Make sure you rebuilt both after any header change. Run make clean && make, then sudo rmmod myblkdev && sudo insmod myblkdev.ko.

    Kernel panic on rmmod

    Almost always caused by a cleanup order bug. The most common one: calling put_disk() before del_gendisk(), or calling unregister_blkdev() while requests are still in flight. Make sure your exit function matches the exact order in the code above.

    VERIFICATION FAILED in userapp output

    Check dmesg for any error messages from the driver. The most common causes are wrong sector arithmetic (off-by-one in byte offset calculation) or a missing spinlock that lets two requests race on the same buffer region.

    Project File Summary

    FilePurposeLines
    myblkdev.hShared ioctl definitions, magic numbers, info struct~50
    myblkdev.cKernel block device driver — full blk-mq + ioctl~220
    userapp.cUserspace test program — open, write, read, ioctl, verify~230
    MakefileBuilds kernel module and userspace binary together~15

    Final Thoughts

    This project gives you a working end-to-end example of how the Linux block I/O stack operates from the userspace open() call all the way down to your driver’s request handler. Every layer in between VFS, page cache, block layer, blk-mq scheduler, bio structure, scatter-gather segments is exercised by running this code.

    The most important habit to build from here: whenever something does not work, start with dmesg. The kernel logs everything your driver prints and every oops or warning. It is your primary debugging window and it will tell you exactly where something went wrong almost every time.

    From this foundation, the next logical project is adding DMA support to talk to real hardware, or building a stacked driver using the Device Mapper framework that encrypts data before passing it to this RAM disk. Both use exactly the same block layer interfaces you just learned.

    For detailed understanding of Platform Devices and Drivers on Linux, refer to the Linux documentation on Platform Devices and Drivers .

  • Linux Block Device Drivers : The Complete Beginner’s Guide

    Learn Linux block device drivers from scratch how they work, how to write one, request queues, bio structures, blk-mq, and real kernel code examples. The most complete beginner guide

    you’ve ever wondered how your Linux system actually talks to a hard disk, an SSD, or even a RAM-based virtual disk block device drivers are the answer. They sit right in the middle, between the kernel’s file system layer and the raw hardware, quietly doing one of the most critical jobs in the entire OS.

    This guide is for people who already know C, have some basic Linux kernel awareness, and want to actually understand block device drivers not just skim a Wikipedia summary. We’re going to go deep. We’ll look at the architecture, write real code, understand request queues, dissect the bio structure, and by the end you’ll have a working skeleton driver you can actually compile and test.

    No fluff. No corporate jargon. Just kernel internals explained like we’re sitting at a coffee shop with a whiteboard between us

    1. What Is a Block Device in Linux?

    A block device is any storage device that Linux treats as a collection of fixed-size blocks typically 512 bytes or 4096 bytes each. You can read or write any individual block independently, in any order. That’s the defining characteristic.

    Your /dev/sda, /dev/nvme0n1, /dev/mmcblk0 these are all block devices. Even /dev/loop0 (a loopback device backed by a file) is a block device. The kernel doesn’t care if the actual storage is a spinning HDD, an NVMe SSD, an SD card, or a chunk of RAM. As long as the driver exposes the right interface, the kernel’s VFS and file system layers talk to it identically.

    The kernel represents block devices under /dev/ and exposes them with major and minor numbers. The major number identifies the driver, and the minor number identifies the specific device or partition that driver manages.

    $ ls -l /dev/sda*
    brw-rw---- 1 root disk 8, 0 Mar 30 09:15 /dev/sda
    brw-rw---- 1 root disk 8, 1 Mar 30 09:15 /dev/sda1
    brw-rw---- 1 root disk 8, 2 Mar 30 09:15 /dev/sda2

    The b at the start means block device. Major number 8 belongs to the sd driver (SCSI disk). Minor 0 is the whole disk; 1, 2 are partitions.

    2. Block Devices vs Character Devices : What’s the Real Difference?

    People learning Linux device drivers always hit this question early. Here’s the honest answer:

    Character devices move data as a stream, byte by byte, sequentially. Think serial ports, keyboards, audio devices. You can’t seek to byte 4000 on a keyboard that makes no sense. The kernel doesn’t buffer data for character devices in any sophisticated way; what you write is what gets sent.

    Block devices are random-access, block-addressable storage. The kernel’s block layer sits between the file system and the driver. It buffers I/O requests, reorders them for efficiency (that’s the I/O scheduler), merges adjacent requests, and handles caching through the page cache. The driver never talks directly to a file system it talks to the block layer, which handles all that complexity above it.

    This distinction matters a lot when you’re writing a driver. A character driver implements file_operations like read() and write(). A block device driver implements a request handler (or a make_request_fn) and registers a gendisk structure. The kernel does the rest of the heavy lifting.

    Another practical difference: block devices support partitioning. You can take /dev/sda and carve it into /dev/sda1, /dev/sda2. The partition table is parsed by the kernel when you register the disk. Character devices don’t have this concept.

    3. The Linux Kernel I/O Stack : The Big Picture

    Before you write a single line of driver code, you need this mental model. The Linux I/O stack has several layers, and knowing where your driver sits changes everything about how you write it.

    From top to bottom:

    1. User Space : your application calls read() or write() on a file
    2. VFS (Virtual File System) : the generic file system interface. Routes calls to the correct file system (ext4, xfs, btrfs, etc.)
    3. Page Cache : kernel-managed RAM buffer. If data is already cached, it never even hits the driver
    4. File System Layer : ext4, xfs, etc. convert file offsets to block addresses
    5. Block Layer : this is where your driver interfaces. It takes block I/O requests, schedules them, merges them, and dispatches to the driver
    6. Block Device Driver : your code. Translates kernel requests into hardware commands
    7. Hardware : the actual disk controller, SSD, or RAM

    Your block device driver lives at layer 6. It never sees file names, file offsets, or inodes. All it gets are sector numbers and memory buffers. “Read 8 sectors starting at sector 1024 into this memory address.” That’s the level of abstraction you work at.

    This is why writing block drivers is actually simpler in some ways than file systems you don’t deal with the complexity of the FS. But it’s harder in other ways because you deal directly with kernel memory management, DMA, and hardware timing.

    4. Block Layer Internals : How I/O Requests Actually Flow

    The block layer is one of the most sophisticated pieces of the Linux kernel. Here’s what happens between “user calls read()” and “driver gets the request”.

    Step 1: The File System Submits a bio

    When a file system needs to read or write blocks, it creates a bio (Block I/O) structure and submits it to the block layer using submit_bio(). The bio contains the target block device, the starting sector, the data buffer (as a list of memory pages), and the direction (read or write).

    Step 2: The Block Layer Processes the bio

    The block layer does several things with incoming bios:

    • Merging: If two requests target adjacent sectors, merge them into one. Fewer requests = better throughput, especially on spinning disks.
    • Sorting: Reorder requests to minimize seek time on HDDs (the classic “elevator algorithm”).
    • Batching: Group requests and dispatch them together to reduce per-request overhead.

    Step 3: Driver Receives and Processes the Request

    The driver’s request function gets called. It reads the sector address and data buffer from the request, does the actual I/O (memory copy for RAM disks, DMA transfer for real hardware), and signals completion by calling blk_mq_end_request().

    The block layer then updates the page cache, wakes up any waiting processes, and the user-space read() call finally returns.

    5. The bio Structure : The Kernel’s Fundamental I/O Unit

    If you want to write block device drivers, you need to understand struct bio cold. It’s defined in include/linux/blk_types.h and it’s the main data structure that flows through the entire block layer.

    struct bio {
        struct bio          *bi_next;       /* request queue link */
        struct block_device *bi_bdev;       /* target block device */
        unsigned int         bi_opf;        /* operation and flags */
        blk_status_t         bi_status;     /* error status */
        struct bvec_iter     bi_iter;       /* current position */
        bio_end_io_t        *bi_end_io;    /* completion callback */
        void                *bi_private;    /* driver private data */
        unsigned short       bi_vcnt;       /* number of bio_vecs */
        struct bio_vec       bi_io_vec[0]; /* the actual data vectors */
    };
    

    The key parts:

    bi_iter : Where You Are in the I/O

    struct bvec_iter {
        sector_t    bi_sector;   /* device sector (512-byte units) */
        unsigned int bi_size;    /* remaining bytes */
        unsigned int bi_idx;     /* current bio_vec index */
        unsigned int bi_bvec_done; /* bytes done in current bvec */
    };
    

    bi_iter.bi_sector tells you which sector on disk this I/O starts at. Always work with this, never with raw byte offsets.

    bio_vec : The Scatter-Gather List

    A bio doesn’t always point to a single contiguous memory buffer. It uses a scatter-gather list of bio_vec structures, each pointing to a page of memory plus an offset and length within that page.

    struct bio_vec {
        struct page *bv_page;   /* pointer to the page */
        unsigned int bv_len;    /* length of this segment */
        unsigned int bv_offset; /* offset within the page */
    };
    

    To iterate over all segments in a bio, use the bio_for_each_segment macro:

    struct bio_vec bvec;
    struct bvec_iter iter;
    
    bio_for_each_segment(bvec, bio, iter) {
        void *kaddr = kmap_atomic(bvec.bv_page);
        /* do your I/O with kaddr + bvec.bv_offset, length bvec.bv_len */
        kunmap_atomic(kaddr);
    }
    

    bi_opf : Operation Flags

    This field tells you what kind of I/O to do. Use bio_data_dir(bio) to get the direction: READ or WRITE. For writes, you read data from the bio’s pages and write to storage. For reads, you write data into the bio’s pages from storage.

    Never try to directly check bi_opf for direction always use the helper macro. The flags field has multiple bits packed together and you’ll get it wrong if you poke at it directly.

    6. Request Queues and the I/O Scheduler

    Every block device in Linux has an associated request queue struct request_queue. This is the object that sits between the block layer and your driver. It holds pending I/O requests, scheduler configuration, queue limits, and a reference to your driver’s request-handling function.

    Queue Limits : Telling the Kernel What Your Device Can Do

    One of the most important things you set up when registering a block driver is the queue limits. These tell the block layer what your hardware can and can’t handle, so it can merge and split requests appropriately.

    blk_queue_max_hw_sectors(queue, max_sectors);
    blk_queue_max_segments(queue, max_segments);
    blk_queue_logical_block_size(queue, 512);
    blk_queue_physical_block_size(queue, 4096);
    

    If you say your device supports max 256 sectors per request, the block layer will never send you a request larger than that. If you support scatter-gather with up to 128 segments, the layer respects that too. Getting these wrong leads to subtle corruption or panics, so set them carefully.

    I/O Schedulers

    The I/O scheduler (also called the block scheduler) decides in what order to dispatch requests from the queue to the driver. Linux has had several over the years:

    • CFQ (Completely Fair Queuing) : removed in kernel 5.0, was the default for years
    • Deadline : prioritizes requests by deadline, good for SSDs and databases
    • BFQ (Budget Fair Queuing) : interactive workload friendly, groups processes
    • mq-deadline : the multi-queue version of Deadline, common default today
    • none : no reordering, FIFO, used for NVMe and fast storage

    You can check and change the scheduler at runtime:

    $ cat /sys/block/sda/queue/scheduler
    mq-deadline [kyber] bfq none
    
    $ echo none > /sys/block/nvme0n1/queue/scheduler

    For simple drivers (RAM disks, virtual devices), you usually use BLK_MQ_F_SHOULD_MERGE flags and let the block layer handle scheduling without worrying about it yourself.

    7. Writing Your First Linux Block Device Driver

    Enough theory. Let’s write a simple RAM-backed block device driver essentially a software-defined disk that lives in kernel memory. This is the classic learning exercise for block driver development because it has no hardware complexity, just the pure kernel interfaces.

    Our driver will:

    • Register a block device with a 16MB RAM disk
    • Handle read and write requests
    • Be loadable as a kernel module
    • Be accessible as /dev/myblk

    Header Includes

    #include &lt;linux/module.h&gt;
    #include &lt;linux/kernel.h&gt;
    #include &lt;linux/fs.h&gt;
    #include &lt;linux/blkdev.h&gt;
    #include &lt;linux/blk-mq.h&gt;
    #include &lt;linux/genhd.h&gt;
    #include &lt;linux/hdreg.h&gt;
    #include &lt;linux/vmalloc.h&gt;
    
    MODULE_LICENSE("GPL");
    MODULE_AUTHOR("Your Name");
    MODULE_DESCRIPTION("Simple RAM Block Device Driver");
    

    Device State Structure

    #define MY_BLOCK_MAJOR    240
    #define MY_BLOCK_MINORS   1
    #define MY_BLOCK_NAME     "myblk"
    #define KERNEL_SECTOR_SIZE 512
    #define MY_DISK_SIZE_MB   16
    
    static int major_num = MY_BLOCK_MAJOR;
    static int disk_size_mb = MY_DISK_SIZE_MB;
    
    struct my_block_dev {
        unsigned long size;          /* size in bytes */
        u8 *data;                    /* the RAM storage */
        struct blk_mq_tag_set tag_set;
        struct request_queue *queue;
        struct gendisk *gd;
    };
    
    static struct my_block_dev *dev;
    

    The Request Handler

    This is the heart of any block driver. The kernel calls this function when it has I/O work for you to do. In blk-mq style (modern kernel), each request is a struct request that wraps one or more bio structures.

    static blk_status_t my_block_request(struct blk_mq_hw_ctx *hctx,
                                          const struct blk_mq_queue_data *bd)
    {
        struct request *req = bd->rq;
        struct my_block_dev *bdev = req->q->queuedata;
        struct bio_vec bvec;
        struct req_iterator iter;
        loff_t pos = blk_rq_pos(req) * KERNEL_SECTOR_SIZE;
        loff_t dev_size = bdev->size;
    
        blk_mq_start_request(req);
    
        if (blk_rq_is_passthrough(req)) {
            pr_notice("Skip non-fs request\n");
            blk_mq_end_request(req, BLK_STS_IOERR);
            return BLK_STS_OK;
        }
    
        rq_for_each_segment(bvec, req, iter) {
            size_t len = bvec.bv_len;
            void *buf = page_address(bvec.bv_page) + bvec.bv_offset;
    
            if (pos + len > dev_size) {
                pr_err("Request beyond device size\n");
                blk_mq_end_request(req, BLK_STS_IOERR);
                return BLK_STS_OK;
            }
    
            if (rq_data_dir(req) == WRITE)
                memcpy(bdev->data + pos, buf, len);
            else
                memcpy(buf, bdev->data + pos, len);
    
            pos += len;
        }
    
        blk_mq_end_request(req, BLK_STS_OK);
        return BLK_STS_OK;
    }
    
    static const struct blk_mq_ops my_mq_ops = {
        .queue_rq = my_block_request,
    };
    

    Notice: rq_data_dir(req) returns WRITE or READ. For writes, copy from the bio’s pages into our RAM buffer. For reads, copy from the RAM buffer into the bio’s pages. That’s the entire I/O operation for a RAM disk just memcpy.

    8. The gendisk Structure and Disk Registration

    The struct gendisk is how you tell the kernel “here is a disk.” It holds the device name, capacity, major/minor numbers, and function pointers for partition-related operations. You allocate it with alloc_disk() and register it with add_disk().

    static const struct block_device_operations my_fops = {
        .owner = THIS_MODULE,
    };
    
    static int __init my_block_init(void)
    {
        int ret;
    
        /* Allocate device state */
        dev = kzalloc(sizeof(*dev), GFP_KERNEL);
        if (!dev)
            return -ENOMEM;
    
        dev->size = disk_size_mb * 1024 * 1024;
        dev->data = vmalloc(dev->size);
        if (!dev->data) {
            ret = -ENOMEM;
            goto err_free_dev;
        }
        memset(dev->data, 0, dev->size);
    
        /* Set up the tag set for blk-mq */
        dev->tag_set.ops = &my_mq_ops;
        dev->tag_set.nr_hw_queues = 1;
        dev->tag_set.queue_depth = 128;
        dev->tag_set.numa_node = NUMA_NO_NODE;
        dev->tag_set.cmd_size = 0;
        dev->tag_set.flags = BLK_MQ_F_SHOULD_MERGE;
    
        ret = blk_mq_alloc_tag_set(&dev->tag_set);
        if (ret)
            goto err_free_data;
    
        /* Create the request queue */
        dev->queue = blk_mq_init_queue(&dev->tag_set);
        if (IS_ERR(dev->queue)) {
            ret = PTR_ERR(dev->queue);
            goto err_free_tag_set;
        }
        dev->queue->queuedata = dev;
    
        /* Allocate the gendisk */
        dev->gd = alloc_disk(MY_BLOCK_MINORS);
        if (!dev->gd) {
            ret = -ENOMEM;
            goto err_free_queue;
        }
    
        dev->gd->major = major_num;
        dev->gd->first_minor = 0;
        dev->gd->fops = &my_fops;
        dev->gd->queue = dev->queue;
        dev->gd->private_data = dev;
        snprintf(dev->gd->disk_name, 32, MY_BLOCK_NAME);
    
        /* Set capacity in 512-byte sectors */
        set_capacity(dev->gd, dev->size / KERNEL_SECTOR_SIZE);
    
        /* Register the major number */
        ret = register_blkdev(major_num, MY_BLOCK_NAME);
        if (ret < 0)
            goto err_free_gd;
    
        /* Add the disk to the system */
        add_disk(dev->gd);
    
        pr_info("myblk: registered with %d MB RAM disk\n", disk_size_mb);
        return 0;
    
    err_free_gd:
        put_disk(dev->gd);
    err_free_queue:
        blk_cleanup_queue(dev->queue);
    err_free_tag_set:
        blk_mq_free_tag_set(&dev->tag_set);
    err_free_data:
        vfree(dev->data);
    err_free_dev:
        kfree(dev);
        return ret;
    }
    

    The Cleanup Function

    static void __exit my_block_exit(void)
    {
        del_gendisk(dev->gd);
        put_disk(dev->gd);
        blk_cleanup_queue(dev->queue);
        blk_mq_free_tag_set(&dev->tag_set);
        unregister_blkdev(major_num, MY_BLOCK_NAME);
        vfree(dev->data);
        kfree(dev);
        pr_info("myblk: unregistered\n");
    }
    
    module_init(my_block_init);
    module_exit(my_block_exit);
    

    Order matters in cleanup you always reverse the registration order. del_gendisk before unregister_blkdev. Free memory last. A single wrong order here causes a kernel panic on module unload.

    9. The make_request Approach : Bypassing the Request Queue

    There are two main styles of block driver in Linux. The request-queue style (what we’ve been building with blk-mq) buffers requests, lets the scheduler sort them, and dispatches them to your handler. This is good for real hardware where reordering matters.

    The other style uses blk_queue_make_request() to register a custom function that bypasses the scheduler entirely. Every bio comes straight to your function with no buffering. This is ideal for:

    • RAM disks (seek time is zero, no benefit to reordering)
    • Stacked drivers (like dm-crypt, RAID) that pass I/O through to other devices
    • Virtual devices where latency matters more than throughput optimization
    static blk_qc_t my_make_request(struct request_queue *q, struct bio *bio)
    {
        struct my_block_dev *bdev = q->queuedata;
        struct bio_vec bvec;
        struct bvec_iter iter;
        loff_t pos = bio->bi_iter.bi_sector * KERNEL_SECTOR_SIZE;
    
        bio_for_each_segment(bvec, bio, iter) {
            void *buf = kmap_atomic(bvec.bv_page) + bvec.bv_offset;
            size_t len = bvec.bv_len;
    
            if (bio_data_dir(bio) == WRITE)
                memcpy(bdev->data + pos, buf, len);
            else
                memcpy(buf, bdev->data + pos, len);
    
            kunmap_atomic(buf - bvec.bv_offset);
            pos += len;
        }
    
        bio_endio(bio);
        return BLK_QC_T_NONE;
    }
    
    /* During init, instead of blk_mq_init_queue: */
    dev->queue = blk_alloc_queue(GFP_KERNEL);
    blk_queue_make_request(dev->queue, my_make_request);
    

    Note the use of kmap_atomic() this temporarily maps a high-memory page into the kernel’s virtual address space so you can access it. Always pair with kunmap_atomic(). Forgetting this causes silent data corruption on 32-bit systems with more than 1GB RAM, or just panics outright.

    10. Multi-Queue Block Layer (blk-mq) : The Modern Way

    Before kernel 3.13, Linux had a single request queue per device. All requests serialized through one lock. This was fine when a disk could do maybe 100-200 IOPS. Modern NVMe SSDs do millions of IOPS. A single queue becomes a catastrophic bottleneck.

    The multi-queue block layer (blk-mq) solved this. It gives each CPU (or NUMA node) its own software queue, and maps those to multiple hardware queues if the device supports it. NVMe SSDs commonly have 32+ hardware queues. blk-mq can feed all of them in parallel with zero lock contention between CPUs.

    The architecture looks like this:

    • Software Queues : one per CPU, handles submissions from that CPU without locking others
    • Hardware Queues : one per device queue (NVMe namespace/queue), your driver processes these
    • Mapping : blk-mq maps many software queues to fewer (or more) hardware queues automatically

    When you call blk_mq_alloc_tag_set(), you configure this mapping:

    dev->tag_set.nr_hw_queues = num_online_cpus(); /* one HW queue per CPU */
    dev->tag_set.queue_depth = 256;                /* max outstanding requests per queue */
    

    For a RAM disk or simple driver, nr_hw_queues = 1 is fine. For a real NVMe driver, you’d query the hardware for the actual number of queues it supports and set this accordingly.

    Tags and Request Tracking

    blk-mq uses a tag system to track in-flight requests. Each request gets a tag (an integer ID) when it’s submitted, and you use that tag to identify and complete it later. This is crucial for asynchronous I/O where you submit a request to hardware and get an interrupt later when it’s done.

    /* In your queue_rq handler: */
    blk_mq_start_request(req);   /* mark it as started, tag is active */
    
    /* ... submit to hardware, store req somewhere indexed by tag ... */
    
    /* In your interrupt handler or completion poll: */
    blk_mq_end_request(req, BLK_STS_OK);  /* or BLK_STS_IOERR on error */
    

    11. Handling Partitions in Block Drivers

    When you register a disk with add_disk(), the kernel automatically reads the partition table from the device’s first sectors (or GPT header) and creates the partition device nodes for you. You don’t manually create /dev/myblk1 — the kernel does it.

    The number of minors you allocate when calling alloc_disk() controls how many partitions your device can have. If you call alloc_disk(16), you get minor numbers 0 through 15, meaning 15 possible partitions (minor 0 is the whole disk).

    For a partition, the block layer translates the sector offset automatically. If partition 1 starts at sector 2048, and a request comes in for sector 0 of partition 1, your driver sees sector 2048. The translation is completely transparent. This is one of the great things about the kernel’s partition handling — your driver doesn’t need to know anything about partitions.

    To force the kernel to re-read a partition table after you’ve modified it (like after writing a new MBR), use:

    ioctl(fd, BLKRRPART, 0);
    /* or from command line: */
    /* blockdev --rereadpt /dev/myblk */

    12. Compiling, Loading, and Testing Your Driver

    The Makefile

    obj-m += myblk.o
    
    KDIR ?= /lib/modules/$(shell uname -r)/build
    
    all:
        make -C $(KDIR) M=$(PWD) modules
    
    clean:
        make -C $(KDIR) M=$(PWD) clean
    
    $ make
    $ sudo insmod myblk.ko
    $ dmesg | tail -5
    [12345.678] myblk: registered with 16 MB RAM disk
    $ ls /dev/myblk
    /dev/myblk
    

    Creating a File System and Mounting

    $ sudo mkfs.ext4 /dev/myblk
    $ sudo mkdir /mnt/myblk
    $ sudo mount /dev/myblk /mnt/myblk
    $ df -h /mnt/myblk
    Filesystem      Size  Used Avail Use% Mounted on
    /dev/myblk       15M  152K   14M   2% /mnt/myblk
    $ echo "hello kernel world" | sudo tee /mnt/myblk/test.txt
    $ cat /mnt/myblk/test.txt
    hello kernel world

    If that works congratulations. You have a working Linux block device driver. The kernel’s ext4 file system is writing to and reading from your driver’s RAM buffer through the full kernel I/O stack.

    Stress Testing with fio

    $ sudo fio --name=test --filename=/dev/myblk --rw=randrw \
        --bs=4k --size=8M --numjobs=4 --time_based --runtime=10 \
        --group_reporting

    This hits your driver with random 4KB reads and writes from 4 parallel threads. Watch for kernel panics, data corruption, or lockups. If it runs clean for 30 seconds, your locking and memory handling are probably okay.

    Checking /proc and /sys

    $ cat /proc/devices | grep myblk
    240 myblk
    
    $ ls /sys/block/myblk/
    alignment_offset  capability  dev  holders  inflight  power  
    queue  range  removable  ro  size  slaves  stat  subsystem  uevent
    
    $ cat /sys/block/myblk/size
    32768           # in 512-byte sectors = 16MB
    
    $ cat /sys/block/myblk/queue/logical_block_size
    512

    13. Real-World Block Driver Examples in the Kernel

    The best way to get better at block driver development after writing your own toy driver is to read real drivers in the kernel tree. Here are the ones worth studying, in order of increasing complexity:

    drivers/block/brd.c — RAM Disk Driver

    This is the official kernel RAM disk driver (/dev/ram0, etc.). It’s very similar to what we built, but handles multiple devices, proper memory management with radix trees, and the make_request style. Read this first. About 400 lines, very approachable.

    drivers/block/loop.c — Loopback Driver

    This backs a block device with a regular file. When you do losetup /dev/loop0 disk.img, this driver reads/writes to disk.img in userspace. It uses make_request style and shows how to do asynchronous I/O with kernel threads. Medium complexity.

    drivers/block/null_blk/ — Null Block Driver

    This is a high-performance benchmarking driver that discards all writes and returns zeroes on reads. It’s used to benchmark the block layer overhead itself. It supports blk-mq with multiple queues, optional latency injection, and configurable parameters via sysfs. This is a goldmine for learning advanced blk-mq patterns.

    drivers/nvme/host/ — NVMe Driver

    The real NVMe driver is one of the most sophisticated block drivers in the kernel. Multiple hardware queues, PCI DMA, interrupt-based completion, NVMe command sets — it’s all there. Read this only after you’re comfortable with the basics. But when you are, it shows you exactly how production-quality block drivers handle real hardware.

    drivers/md/ — Software RAID and dm

    The MD (Multiple Devices) layer and Device Mapper (dm) are stacked block drivers — they sit on top of other block devices and provide RAID, encryption (dm-crypt), LVM, thin provisioning, etc. These are fascinating because they show how to stack block devices and how the kernel handles the same bio being processed by multiple drivers in sequence.

    14. Debugging Linux Block Device Drivers

    Kernel debugging is a whole different world from userspace debugging. You can’t attach GDB and step through kernel code easily (well, you can with KGDB, but it’s painful). Here are the practical techniques that actually work.

    pr_info, pr_err, printk

    Your first tool is always printk-based logging. Use pr_info(), pr_warn(), pr_err() — these prepend your module name automatically if you define pr_fmt at the top of your file:

    #define pr_fmt(fmt) KBUILD_MODNAME ": " fmt

    Then all your pr_info() calls show up in dmesg as myblk: your message here. Check dmesg -w in a terminal while loading and exercising your module.

    QEMU + GDB for Real Debugging

    The real way to debug kernel drivers without destroying your actual system is to run Linux in QEMU and attach GDB to it. QEMU supports -s -S flags that start it with a GDB stub paused at the first instruction.

    $ qemu-system-x86_64 -kernel bzImage -initrd initrd.img \
        -append "console=ttyS0" -nographic -s -S
    
    # In another terminal:
    $ gdb vmlinux
    (gdb) target remote :1234
    (gdb) break my_block_request
    (gdb) continue

    This lets you set breakpoints in your driver code, inspect kernel data structures, and single-step through the request handler. It’s the closest thing to real debugging you’ll get in the kernel world.

    CONFIG_DEBUG_BLOCK_EXT_DEVT and Block-Specific Debugging

    The kernel has several Kconfig options specifically for block layer debugging:

    • CONFIG_BLK_DEBUG_FS — exposes detailed blk-mq debugging info under /sys/kernel/debug/block/
    • CONFIG_BLK_DEV_IO_TRACE — enables blktrace, a powerful tool for recording every I/O event
    • CONFIG_FAIL_MAKE_REQUEST — fault injection for block requests

    blktrace and blkparse

    blktrace is a dedicated block I/O tracing tool. It hooks into the kernel’s block trace points and records every event — bio submission, queue insertion, driver dispatch, completion — with nanosecond timestamps.

    $ sudo blktrace -d /dev/myblk -o trace
    $ sudo blkparse trace.blktrace.0 | head -50

    This output shows you exactly what the block layer is doing with your device. Great for diagnosing scheduler behavior, finding unexpected I/O patterns, and verifying that your driver is completing requests correctly.

    15. Common Mistakes Beginners Make With Block Device Drivers

    These mistakes have caused panics for probably every kernel developer who’s gone through this learning curve. Learn from them instead of experiencing them firsthand.

    Mistake 1: Not Calling blk_mq_start_request

    In blk-mq, you must call blk_mq_start_request(req) before doing any processing. Skipping this causes the timeout mechanism to fire incorrectly and you’ll see mysterious “request timeout” errors or double-completions that panic the kernel.

    Mistake 2: Wrong Sector Arithmetic

    Sectors are always 512 bytes in the block layer’s address space, even if your device uses 4096-byte physical blocks. blk_rq_pos(req) returns the offset in 512-byte units. Always multiply by KERNEL_SECTOR_SIZE (512) to get bytes. Getting this wrong causes reads to return garbage and writes to corrupt data in non-obvious ways.

    Mistake 3: Sleeping in Atomic Context

    Your request handler might be called in an atomic context (interrupts disabled, spinlock held). Calling anything that can sleep — kmalloc(GFP_KERNEL), mutex_lock(), copy_to_user() — in this context causes a lockdep warning or a kernel crash. Always use GFP_ATOMIC for allocations in the request path, and do all blocking work in a separate kernel thread or workqueue.

    Mistake 4: Not Handling Bio Completion Correctly

    Every bio that comes to your driver must be completed — either with bio_endio(bio) (success), bio_io_error(bio) (error), or through request-level completion via blk_mq_end_request(). Forgetting to complete a bio hangs the process that submitted it forever. It won’t crash the kernel immediately — it’ll just hang, which is often harder to debug than a crash.

    Mistake 5: Cleanup Order Errors

    The exit path cleanup order is the reverse of the init path setup order. This sounds obvious but it’s easy to get wrong when you’re debugging and adding/removing init steps. A wrong cleanup order causes use-after-free bugs, double-free crashes, or hung processes when you do rmmod.

    Mistake 6: Ignoring Request Flush and FUA

    If your device claims to have a write cache (and some real hardware does), you need to handle flush requests. When an application calls fsync(), the file system submits a special REQ_PREFLUSH or REQ_FUA (Force Unit Access) request to make sure data is actually on stable storage. Ignoring these means fsync() appears to succeed but data could be lost on power failure. For a simple RAM disk driver this doesn’t matter, but for any driver that interfaces with real hardware with write caches, this is critical for data integrity.

    16. What to Learn Next

    You’ve got the fundamentals of Linux block device driver development down. Here’s where to go from here depending on your goals:

    If You Want to Work on Real Storage Hardware

    Learn DMA (Direct Memory Access). Real drivers don’t use memcpy — they program the hardware’s DMA controller to transfer data directly between device and RAM without CPU involvement. Study the kernel’s DMA API: dma_alloc_coherent(), dma_map_sg(), dma_sync_for_device(). The NVMe driver is the best example of DMA in block drivers.

    If You’re Interested in Storage Stacking (LVM, RAID, Encryption)

    Learn the Device Mapper framework (drivers/md/dm.c). Device mapper lets you build complex storage topologies by stacking block devices. dm-crypt (full disk encryption), dm-thin (thin provisioning), and LVM all use it. Writing a simple dm target is a great exercise — you implement a transform function that maps bio addresses from the virtual device to the underlying real device.

    If You’re Targeting Embedded or Automotive Systems

    Look at UFS (Universal Flash Storage) and eMMC drivers in drivers/scsi/ufs/ and drivers/mmc/. These are the storage interfaces on embedded SoCs, phones, and automotive infotainment systems. The MMC subsystem has its own host controller abstraction on top of the block layer, and understanding it opens up a huge class of embedded storage work.

    Resources Worth Reading

    • Linux Device Drivers, 3rd Edition (Corbet, Rubini, Kroah-Hartman) : free online, chapter 16 is specifically on block drivers. Note: it’s old (2.6 era), but the concepts are solid even if the specific APIs changed.
    • The kernel source itself under Documentation/block/ : especially blk-mq.rst and biodoc.rst
    • Jonathan Corbet’s LWN.net articles on the block layer : search “LWN block layer” and you’ll find years of excellent coverage of how the block layer evolved
    • The null_blk driver source for advanced blk-mq patterns

    Quick Reference: Block Driver API Cheat Sheet

    Function / MacroPurpose
    register_blkdev(major, name)Register a major number for your driver
    unregister_blkdev(major, name)Unregister on module exit
    alloc_disk(minors)Allocate a gendisk structure
    add_disk(gd)Make disk visible to the kernel
    del_gendisk(gd)Remove disk from the kernel
    put_disk(gd)Release gendisk reference
    set_capacity(gd, sectors)Set disk size in 512-byte sectors
    blk_mq_alloc_tag_set(ts)Allocate blk-mq tag set
    blk_mq_init_queue(ts)Create a request queue
    blk_cleanup_queue(q)Destroy a request queue
    blk_mq_start_request(req)Mark request as in-flight
    blk_mq_end_request(req, status)Complete a request
    blk_rq_pos(req)Get starting sector of a request
    rq_data_dir(req)Get direction: READ or WRITE
    rq_for_each_segment(bvec, req, iter)Iterate over request segments
    bio_data_dir(bio)Get bio direction: READ or WRITE
    bio_for_each_segment(bvec, bio, iter)Iterate over bio segments
    bio_endio(bio)Complete a bio (success)
    submit_bio(bio)Submit a bio to block layer
    kmap_atomic(page)Map a page into kernel virtual space
    kunmap_atomic(addr)Unmap after use

    Wrapping Up

    Block device drivers are where kernel development gets really interesting. You’re operating at the exact boundary between software and hardware — translating abstract kernel requests into concrete I/O operations. Every filesystem on every Linux system depends on block drivers working correctly, which means this is some of the most impactful kernel code you can write.

    The path forward is clear: start with the RAM disk driver we built here, get it compiling and running, then start reading the real kernel drivers. brd.c, then null_blk, then NVMe if you’re aiming for high-performance storage. Each one will teach you something the simpler ones don’t cover.

    The kernel community is also genuinely welcoming to new contributors. If you find a bug in a block driver or have a performance improvement, submitting a patch to the linux-block mailing list is a realistic goal — even for someone who’s been doing this for just a few months.

    Good luck, and keep reading dmesg.

    Have questions about a specific part of block driver development? Drop a comment below happy to go deeper on any of these topics.

    Frequently Asked Questions : Linux Block Device Drivers

    Q1. What is a block device driver in Linux? A block device driver is a kernel module that allows Linux to communicate with storage hardware like hard disks, SSDs, and SD cards by exposing them as fixed-size, randomly accessible block devices under /dev/.

    Q2. What is the difference between a block device and a character device in Linux? Block devices support random access and are buffered through the kernel’s page cache. Character devices stream data sequentially with no buffering. Storage devices use block drivers while serial ports and keyboards use character drivers.

    Q3. What is the bio structure in the Linux kernel? bio stands for Block I/O and is the fundamental data structure the kernel uses to represent a single I/O operation. It contains the target device, starting sector, data buffers as scatter-gather page vectors, and a completion callback function.

    Q4. What is blk-mq in Linux? blk-mq stands for Multi-Queue Block Layer and is the modern Linux block I/O framework that replaced the old single-queue design. It gives each CPU its own software queue and maps them to multiple hardware queues, enabling millions of IOPS for NVMe SSDs.

    Q5. How do I write a simple Linux block device driver? You allocate a gendisk structure, set up a blk-mq tag set and request queue, implement a queue_rq handler that processes read and write requests, register a major number with register_blkdev(), and call add_disk() to make the device visible to the kernel.

    Q6. What is gendisk in the Linux kernel? struct gendisk is the kernel structure that represents a physical or virtual disk. It holds the device name, major and minor numbers, capacity in sectors, partition information, and a pointer to the block_device_operations function table.

    Q7. What is a request queue in Linux block drivers? A request queue sits between the block layer and your driver. It holds pending I/O requests, manages the I/O scheduler, enforces hardware limits like max sectors and max segments, and dispatches ready requests down to your driver’s handler function.

    Q8. What is the difference between make_request and request queue style drivers? Request queue style buffers and schedules I/O before dispatching to your driver which is good for real spinning hardware. make_request style bypasses the scheduler entirely and sends every bio straight to your function which is ideal for RAM disks, virtual devices, and stacked drivers.

    Q9. How does Linux handle disk partitions in block drivers? When you call add_disk(), the kernel automatically reads the partition table and creates all partition device nodes for you. The block layer translates partition-relative sector offsets to absolute disk offsets transparently so your driver never needs to handle any partition logic itself.

    Q10. What is the I/O scheduler in Linux and how does it affect block drivers? The I/O scheduler reorders and merges block requests to improve throughput and reduce seek time on spinning disks. Common schedulers today include mq-deadline, BFQ, and none. For fast NVMe storage none is usually best. Your driver influences scheduling behavior through queue limits and flags you set during initialization.

    Q11. How do I debug a Linux block device driver? Use pr_info and pr_err with dmesg for basic logging. Use blktrace to record every block I/O event with timestamps. Use QEMU combined with GDB for proper breakpoint-level debugging without risking your real system. Enable CONFIG_BLK_DEBUG_FS to expose detailed blk-mq internals under /sys/kernel/debug/block/.

    Q12. What are the most common mistakes in block device driver development? The most common mistakes are forgetting to call blk_mq_start_request(), getting sector-to-byte arithmetic wrong, sleeping inside atomic context, failing to complete every bio, using the wrong cleanup order in the module exit function, and ignoring flush and FUA requests on hardware with write caches.

    Q13. What kernel source files should I study to learn block driver development? Start with drivers/block/brd.c for the RAM disk reference driver, then move to drivers/block/loop.c for the loopback driver, then drivers/block/null_blk/ for advanced blk-mq patterns, and finally drivers/nvme/host/ when you are ready to see a full DMA-based production driver.

    Q14. Can I format and mount a custom block device driver like a real disk? Yes. Once your driver is loaded and the device node appears under /dev/, you can run mkfs.ext4 on it, mount it to any directory, and read and write files normally through it. The kernel file system layer is completely unaware it is talking to a custom driver.

    Q15. What should I learn after mastering Linux block device drivers? The natural next steps are the kernel DMA API for real hardware data transfers, the Device Mapper framework for building stacked drivers like dm-crypt and LVM, and the UFS and eMMC subsystems if you are targeting embedded or automotive storage platforms.

    For detailed understanding of Platform Devices and Drivers on Linux, refer to the official Linux documentation on Platform Devices and Drivers .

    If you’re interested in going beyond theory and building a real-world implementation, check out this Complete Linux Block Device Driver Project that covers both kernel-level driver development and userspace interaction. It walks you step-by-step through creating a functional block driver, handling I/O requests, and building a userspace program to communicate with the kernel module. This is perfect for beginners who want hands-on experience with Linux device drivers.

  • Linux Character Driver from Scratch (Beginner to Pro)

    Learn how to build a Linux Character Driver from scratch with this beginner-friendly guide. Step-by-step tutorial covering kernel modules, file operations, device files, and real-world driver examples.

    If you’ve ever wanted to understand how Linux actually talks to hardware, learning a Linux Character Driver is one of the best places to start.

    This guide is not just theory. We’ll go step by step, from zero to a working driver, and explain things like you’re sitting next to me with a coffee asking real questions.

    By the end, you’ll:

    • Understand what a Linux Character Driver is
    • Know where it’s used in real systems (UART, GPIO, etc.)
    • Build a complete driver from scratch
    • Write a user-space program to interact with it
    • Learn how real production drivers are structured

    What is a Linux Character Driver?

    A Linux Character Driver is a type of device driver that communicates with hardware one byte (character) at a time.

    Think of it like reading a book letter by letter instead of jumping pages.

    Examples:

    • UART (serial communication)
    • Keyboard input
    • GPIO pins
    • Sensors

    These are all handled using character device drivers in Linux.

    Character vs Block Drivers

    Let’s make this super simple.

    Imagine you’re reading data like you read content in real life.

    Character Driver (One by One Data)

    A Linux Character Driver works like reading a message letter by letter.

    You don’t jump around. You go in order.

    Example:

    Think of:

    • Typing on keyboard
    • Reading from a serial port
    • Getting sensor data

    All of these send data continuously and sequentially.

    That’s why they use a character device driver in Linux

    Real Devices:

    • /dev/ttyS0 (UART)
    • /dev/input/event0 (keyboard/mouse)
    • /dev/gpiochip0 (GPIO)

    Block Driver (Data in Chunks)

    A Block Driver works like reading a book where you can:

    • Jump to page 10
    • Then page 50
    • Then page 2

    No need to go in order.

    Example:

    Think of:

    • Hard disk
    • SSD
    • USB storage

    You can directly access any part of data.

    That’s why they use block device drivers

    Real Devices:

    • /dev/sda (hard disk)
    • /dev/mmcblk0 (SD card)

    Simple Comparison

    FeatureCharacter DriverBlock Driver
    Data AccessSequentialRandom
    Data TypeStream (byte-by-byte)Blocks (chunks)
    ExampleUART, GPIOHard disk
    SpeedUsually slowerFaster (optimized)
    BufferingMinimalHeavy buffering

    Easy Analogy (Best Way to Remember)

    • Character Driver → Like listening to a song live 🎧
      You hear it as it plays (no jumping)
    • Block Driver → Like YouTube video 📺
      You can skip anywhere

    Golden Rule

    Ask this question:

    👉 “Do I need to access data randomly or sequentially?”

    • Sequential → Linux Character Driver
    • Random → Block Driver

    In real linux driver development beginner journey:

    • First drivers you learn → Character Drivers
    • Advanced storage systems → Block Drivers

    Because character drivers are:

    • Easier to write
    • Closer to hardware
    • Great for learning linux kernel programming basics

    If data flows like a stream → Character Driver
    If data is accessed like storage → Block Driver

    Where Are Character Drivers Used?

    A Linux Character Driver isn’t just a textbook concept. It’s used everywhere Linux needs to handle stream-based, byte-by-byte communication with hardware.

    Think of any device where data flows continuously rather than in chunks. That’s your signal that a character device driver in Linux is probably involved.

    Let’s break down the most common real-world use cases.

    UART Driver

    Used for serial communication between devices.

    GPIO Driver

    Used to control pins (LED, buttons).

    Sensors

    Temperature, pressure sensors send data continuously.

    So yes — when you asked earlier:

    “Is UART, GPIO implemented using character driver?”

    ==> Yes, most of the time : absolutely.

    Basic Architecture of Linux Character Driver

    High-Level Architecture

    Here’s the overall flow:

    User Space Application
            │
            ▼
    System Calls (open, read, write, close)
            │
            ▼
    VFS (Virtual File System)
            │
            ▼
    Character Driver (Your Code)
            │
            ▼
    Hardware Device
    

    Key Components Explained

    1. User Space

    This is where your application runs.

    Example:

    int fd = open("/dev/my_device", O_RDWR);
    write(fd, "Hello", 5);
    read(fd, buffer, 5);
    close(fd);
    

    These are system calls, not direct hardware access.

    2. System Calls Interface

    Linux provides standard APIs:

    • open()
    • read()
    • write()
    • close()

    These calls go through the kernel and reach your driver.

    3. VFS (Virtual File System)

    VFS acts as a bridge between system calls and drivers.

    It ensures:

    • Everything in Linux is treated as a file
    • Your driver is accessed via /dev/my_device

    4. Device File (/dev)

    Example:

    /dev/my_device

    Created using:

    • mknod (manual)
    • udev (automatic)

    It connects user space to your driver.

    5. Character Driver Core Structure

    Your driver mainly consists of:

    a) File Operations Structure

    This is the heart of the driver.

    struct file_operations fops = {
        .open = my_open,
        .read = my_read,
        .write = my_write,
        .release = my_close,
    };

    It tells the kernel:

    “When user calls read(), call my_read()”

    b) Major & Minor Number

    • Major Number → Identifies driver
    • Minor Number → Identifies device

    Example:

    Major: 240 → my driver
    Minor: 0   → device instance

    c) Device Registration

    alloc_chrdev_region(&dev, 0, 1, "my_device");
    

    Registers device with kernel

    d) cdev Structure

    struct cdev my_cdev;
    cdev_init(&my_cdev, &fops);
    cdev_add(&my_cdev, dev, 1);
    

    Links file operations with device

    e) Class & Device Creation

    class_create(THIS_MODULE, "my_class");
    device_create(my_class, NULL, dev, NULL, "my_device");
    

    Creates /dev/my_device

    Driver Entry & Exit

    Init Function

    static int __init my_init(void)
    {
        // register device
        return 0;
    }
    

    Exit Function

    static void __exit my_exit(void)
    {
        // cleanup
    }
    

    Registered using:

    module_init(my_init);
    module_exit(my_exit);

    Complete Flow (Step-by-Step)

    1. User runs program
    2. Calls open("/dev/my_device")
    3. VFS finds your driver
    4. Calls my_open()
    5. User calls write()
    6. Kernel calls my_write()
    7. Driver interacts with hardware
    8. Data flows back via read()

    Pro Tip

    “Character drivers are synchronous, stream-oriented, and accessed via file operations.”

    Linux Kernel Module Basics

    Before writing a driver, we need a kernel module.

    Simple Hello World Module

    #include <linux/module.h>
    #include <linux/kernel.h>
    
    static int __init hello_init(void) {
        printk(KERN_INFO "Hello Driver Loaded\n");
        return 0;
    }
    
    static void __exit hello_exit(void) {
        printk(KERN_INFO "Driver Removed\n");
    }
    
    module_init(hello_init);
    module_exit(hello_exit);
    
    MODULE_LICENSE("GPL");
    

    Compile

    make
    

    Insert Module

    sudo insmod hello.ko

    Remove Module

    sudo rmmod hello

    What is #include?

    #include <linux/module.h>
    #include <linux/kernel.h>
    

    In C, #include means:

    “Bring definitions and declarations from another file so I can use them.”

    1. #include <linux/module.h>

    What it is:

    This header is used for loadable kernel modules (LKM).

    A Linux character driver is actually a kernel module, so this is mandatory.

    What it provides:

    Module Macros

    module_init(my_init);
    module_exit(my_exit);
    

    These tell the kernel:

    • Which function to run when module is loaded
    • Which function to run when module is removed

    License Declaration

    MODULE_LICENSE("GPL");
    

    Important because:

    • Avoids kernel warnings
    • Enables access to some kernel features

    Author & Description

    MODULE_AUTHOR("Raj");
    MODULE_DESCRIPTION("Simple Character Driver");

    Simple Meaning:

    This header makes your C file behave like a kernel module

    2. #include <linux/kernel.h>

    What it is:

    This header provides kernel-level utilities and logging functions

    What it provides:

    printk() (Very Important)

    printk(KERN_INFO "Hello Kernel\n");
    

    This is like printf() but for the kernel.

    Log Levels

    KERN_INFO
    KERN_WARNING
    KERN_ERR
    

    Example:

    printk(KERN_ERR "Something went wrong\n");

    Difference Between Them

    Feature<linux/module.h><linux/kernel.h>
    PurposeModule handlingKernel utilities
    Needed forDriver lifecycleDebugging/logging
    Key Featuremodule_init()printk()

    static int __init hello_init(void) function

    static int __init hello_init(void) {
        printk(KERN_INFO "Hello Driver Loaded\n");
        return 0;
    }
    

    What is this function?

    This is the initialization function (entry point) of your kernel module (driver).

    It runs when you load the driver using:

    insmod driver.ko
    

    Line-by-Line Explanation

    1. static

    Meaning:

    • Limits the scope of this function only to this file

    Other files in the kernel cannot access it

    Why use it?

    • Avoid name conflicts
    • Good coding practice in kernel development

    2. int

    Meaning:

    • Function returns an integer value

    Important:

    • 0 → Success
    • Negative value → Failure

    Example:

    return -ENOMEM;  // Memory allocation failed
    

    3. __init

    What is this?

    A special kernel macro

    What it does:

    • Marks this function as initialization-only code
    • After driver loads → memory is freed automatically

    Saves kernel memory

    Important Rule:

    ❌ Never call an __init function after initialization
    (its memory is gone!)

    4. hello_init

    Function Name:

    • You can name it anything
    • Convention: drivername_init

    5. (void)

    Meaning:

    • Function takes no arguments

    6. { ... } (Function Body)

    a) printk(KERN_INFO "Hello Driver Loaded\n");

    This prints a message inside the kernel log

    • printk → Kernel version of printf
    • KERN_INFO → Log level (informational message)

    Where to see output?

    dmesg
    

    Example output:

    Hello Driver Loaded
    

    b) return 0;

    Tells kernel:

    “Driver loaded successfully”

    Full Flow

    1. You run:insmod driver.ko
    2. Kernel calls:hello_init()
    3. Message printed:Hello Driver Loaded
    4. Kernel accepts module (since return = 0)

    What if it fails?

    If you return:

    return -1;
    

    Then:

    • Driver will NOT load
    • Kernel shows error

    Real-World Use of hello_init

    In real drivers, this function is used to:

    • Register device (alloc_chrdev_region)
    • Initialize cdev
    • Create device file (/dev/...)
    • Allocate memory
    • Setup hardware

    static void __exit hello_exit(void) function

    static void __exit hello_exit(void) {
        printk(KERN_INFO "Driver Removed\n");
    }
    

    What is this function?

    This function runs when you remove/unload the driver:

    rmmod driver
    

    So:

    hello_init() = when driver loads
    hello_exit() = when driver unloads

    Line-by-Line Explanation

    1. static

    Meaning:

    • Function is only visible inside this file

    Prevents conflicts with other kernel code

    2. void

    Meaning:

    • Function does not return anything

    Unlike init, kernel doesn’t expect success/failure here
    (you must clean up properly no matter what)

    3. __exit

    What it is:

    A kernel macro similar to __init

    What it does:

    • Marks function as exit/cleanup code
    • Used only when module is removed
    • If driver is built into kernel (not module) → this code is ignored

    Important:

    If built-in:

    Exit function may never run

    4. hello_exit

    Function name (can be anything)

    Convention:

    drivername_exit

    5. (void)

    No parameters

    6. Function Body

    printk(KERN_INFO "Driver Removed\n");

    Prints message to kernel log

    Check using:

    dmesg

    Output:

    Driver Removed

    Full Flow

    1. You run:rmmod driver
    2. Kernel calls:hello_exit()
    3. Cleanup happens
    4. Message printed:Driver Removed

    Real-World Importance

    In real drivers, this function is critical

    You must clean everything you created in init():

    Example Cleanup Tasks:

    device_destroy(...)
    class_destroy(...)
    cdev_del(...)
    unregister_chrdev_region(...)
    kfree(...)
    

    If you don’t clean properly:

    • Memory leaks
    • Device conflicts
    • Kernel crash (serious bug)

    Analogy

    Think of it like:

    “Shutdown procedure of your driver”

    If you turned ON things in init(),
    you MUST turn them OFF here.

    How It Connects

    You register it using:

    module_exit(hello_exit);
    

    This tells kernel:

    “Call this function when module is removed”

    Pro Tip (Interview Level)

    Always say:

    “Whatever is allocated in init must be freed in exit”

    What is a Device File in Linux?

    In Linux, everything is a file.

    Your driver becomes usable through:

    /dev/my_device

    This is called a device file in Linux.

    Core Components of a Linux Character Driver

    Now we move into real Linux driver development for beginners.

    Key parts:

    • dev_t → device number
    • cdev → character device structure
    • file_operations → driver functions

    File Operations Structure (Very Important)

    This is the heart of your driver.

    struct file_operations fops = {
        .open = my_open,
        .read = my_read,
        .write = my_write,
        .release = my_close,
    };
    

    This connects user-space calls to kernel functions.

    What is struct file_operations?

    It is a structure of function pointers defined by the kernel.

    It tells the kernel:
    “When a user performs a file operation, call these functions.”

    Big Picture

    When user runs:

    fd = open("/dev/my_device", O_RDWR);
    write(fd, "Hi", 2);
    read(fd, buf, 2);
    close(fd);
    

    Kernel maps them like this:

    User CallDriver Function
    open()my_open()
    read()my_read()
    write()my_write()
    close()my_close()

    Line-by-Line Breakdown

    struct file_operations fops

    Declares a variable fops of type file_operations

    This structure is defined in:

    #include <linux/fs.h>
    

    .open = my_open

    When user calls open() → kernel calls:

    my_open()
    

    Typical use:

    • Initialize device
    • Allocate resources
    • Check permissions

    .read = my_read

    When user calls read() → kernel calls:

    my_read()
    

    Typical use:

    • Send data from kernel → user
    • Use copy_to_user()

    .write = my_write

    When user calls write() → kernel calls:

    my_write()
    

    Typical use:

    • Receive data from user → kernel
    • Use copy_from_user()

    .release = my_close

    Called when user runs close()

    my_close()
    

    Note:

    • release = close (kernel naming)

    How It Works Internally

    1. You register your driver (cdev_add)
    2. Kernel stores pointer to fops
    3. When user performs operations:
      • Kernel looks into fops
      • Calls the corresponding function

    Example Function Prototypes

    int my_open(struct inode *inode, struct file *file);
    
    ssize_t my_read(struct file *file, char __user *buf, size_t len, loff_t *offset);
    
    ssize_t my_write(struct file *file, const char __user *buf, size_t len, loff_t *offset);
    
    int my_close(struct inode *inode, struct file *file);
    

    Simple Analogy

    Think of file_operations like:

    📞 A contact list for the kernel

    • open → call this number
    • read → call this number
    • write → call this number

    Important Notes

    You don’t need to implement all functions

    Example:

    struct file_operations fops = {
        .read = my_read,
    };
    

    Only read is supported

    If function is missing

    • Kernel may return error (-ENOSYS)
    • Operation fails

    Must Register This

    cdev_init(&my_cdev, &fops);
    

    This connects your driver with fops

    Real Driver Flow

    User → open() → my_open()
    User → write() → my_write()
    User → read() → my_read()
    User → close() → my_close()

    Full Linux Character Driver Example

    Now let’s build a complete character driver example in Linux.

    #include <linux/module.h>
    #include <linux/fs.h>
    #include <linux/cdev.h>
    #include <linux/uaccess.h>
    
    #define DEVICE_NAME "my_char_dev"
    
    static dev_t dev_num;
    static struct cdev my_cdev;
    
    char kernel_buffer[1024];
    
    static int my_open(struct inode *inode, struct file *file) {
        printk("Device Opened\n");
        return 0;
    }
    
    static int my_close(struct inode *inode, struct file *file) {
        printk("Device Closed\n");
        return 0;
    }
    
    static ssize_t my_read(struct file *file, char __user *buf, size_t len, loff_t *off) {
        copy_to_user(buf, kernel_buffer, len);
        return len;
    }
    
    static ssize_t my_write(struct file *file, const char __user *buf, size_t len, loff_t *off) {
        copy_from_user(kernel_buffer, buf, len);
        return len;
    }
    
    static struct file_operations fops = {
        .owner = THIS_MODULE,
        .open = my_open,
        .read = my_read,
        .write = my_write,
        .release = my_close,
    };
    
    static int __init driver_init(void) {
        alloc_chrdev_region(&dev_num, 0, 1, DEVICE_NAME);
        cdev_init(&my_cdev, &fops);
        cdev_add(&my_cdev, dev_num, 1);
    
        printk("Driver Loaded\n");
        return 0;
    }
    
    static void __exit driver_exit(void) {
        cdev_del(&my_cdev);
        unregister_chrdev_region(dev_num, 1);
    
        printk("Driver Unloaded\n");
    }
    
    module_init(driver_init);
    module_exit(driver_exit);
    
    MODULE_LICENSE("GPL");
    

    Create Device File

    sudo mknod /dev/my_char_dev c <major> <minor>
    

    User Space Program

    Now let’s interact with the driver.

    #include <stdio.h>
    #include <fcntl.h>
    #include <unistd.h>
    
    int main() {
        int fd = open("/dev/my_char_dev", O_RDWR);
    
        write(fd, "Hello Driver", 12);
    
        char buf[100];
        read(fd, buf, 12);
    
        printf("Data: %s\n", buf);
    
        close(fd);
        return 0;
    }
    

    How It Works End-to-End

    1. User program calls write()
    2. Kernel calls my_write()
    3. Data stored in kernel buffer
    4. read() fetches it back

    This is a complete Linux device driver examples

    Why Exit Function is Important?

    You asked earlier:

    Why do we need exit function?

    Because kernel modules must clean up resources.

    Without cleanup:

    • Memory leaks
    • Device conflicts
    • System instability

    So always use:

    module_exit(driver_exit);

    Real Production Driver Structure

    In real embedded Linux driver development, drivers are more complex:

    • Use platform_driver
    • Device Tree (DTS)
    • Interrupt handling
    • DMA
    • Hardware registers

    Debugging Linux Drivers

    Essential for real work.

    Use:

    dmesg

    Add logs:

    printk(KERN_INFO "Debug Message\n");

    Advanced:

    • ftrace
    • kgdb

    Common Mistakes Beginners Make

    • Forgetting copy_to_user
    • Not checking return values
    • Memory leaks
    • Wrong device permissions

    Linux Driver Interview Questions

    You’ll definitely face these:

    Q1: What is character driver?

    Ans : Sequential data transfer driver

    Q2: What is file_operations?

    Ans : Structure linking user calls to kernel

    Q3: Difference between user and kernel space?

    Ans : Security and access level separation

    Best Practices

    • Always validate user input
    • Use snprintf instead of sprintf
    • Follow kernel coding style
    • Keep driver modular

    Advanced Topics (Next Step)

    Once you’re comfortable:

    • Interrupt handling
    • Platform drivers + DTS
    • SPI/I2C drivers
    • Kernel synchronization

    Final Thoughts

    Learning a Linux Character Driver is like opening the door to kernel-level programming.

    At first, it feels confusing:

    • Kernel space
    • File operations
    • Device numbers

    But once you build one working driver, everything clicks

    FAQ : Linux Character Driver

    1.What is a Linux Character Driver?

    A Linux Character Driver is a type of device driver that allows communication between user space and hardware devices one byte at a time (stream-based data transfer). These drivers are commonly used for devices like UART, keyboards, GPIO, and sensors.

    2.How does a Linux Character Driver work?

    A Linux Character Driver works through a layered architecture:

    • User application calls open(), read(), write()
    • System calls reach the kernel via VFS (Virtual File System)
    • Kernel invokes driver functions defined in file_operations
    • Driver interacts with hardware

    3.What is file_operations in a character driver?

    file_operations is a structure that maps user-space system calls to driver functions.

    Example:

    • open() → my_open()
    • read() → my_read()
    • write() → my_write()

    It acts as the core interface between user space and kernel space.

    4.What is the difference between Character Driver and Block Driver?

    FeatureCharacter DriverBlock Driver
    Data AccessByte-by-byteBlock (chunks)
    ExampleUART, GPIOHard Disk
    BufferingMinimalUses cache
    Access TypeSequentialRandom

    5.What are major and minor numbers?

    • Major Number → Identifies the driver
    • Minor Number → Identifies the device instance

    These numbers help the kernel route operations to the correct driver.

    6.What is /dev in Linux Character Drivers?

    /dev is a directory where device files are created.

    Example:

    /dev/my_device
    

    This file acts as the entry point for user applications to interact with the driver.

    7.What is printk() in Linux drivers?

    printk() is used for kernel-level logging, similar to printf() in user space.

    Example:

    printk(KERN_INFO "Driver Loaded\n");
    

    You can view logs using:

    dmesg
    

    8.What is __init and __exit in Linux drivers?

    • __init → Marks initialization function (freed after loading)
    • __exit → Marks cleanup function (used during module removal)

    These help optimize memory usage in the kernel.

    9.How do you load and unload a character driver?

    Load driver:

    sudo insmod driver.ko
    

    Unload driver:

    sudo rmmod driver
    

    Check logs:

    dmesg
    

    10.What is a kernel module in Linux?

    A kernel module is a piece of code that can be loaded/unloaded into the kernel dynamically. A Linux Character Driver is typically implemented as a kernel module.

    11.Where are Linux Character Drivers used?

    They are used in real-world scenarios like:

    • UART communication
    • GPIO control
    • Sensor interfacing
    • Embedded systems
    • Serial devices

    12.Do I need hardware to learn character drivers?

    No. You can start with a virtual character driver (dummy driver) and simulate read/write operations without real hardware.

    13.What are common mistakes beginners make?

    • Forgetting cleanup in __exit
    • Not handling copy_to_user() properly
    • Incorrect major/minor number handling
    • Missing error checks in init function

    14.Is Linux Character Driver development hard?

    Initially, it may feel complex, but with step-by-step practice:

    • Start with a simple module
    • Learn file_operations
    • Build a dummy driver

    It becomes much easier over time.

    15.What is the difference between read() and write() in drivers?

    • read() → Kernel → User space (sending data)
    • write() → User space → Kernel (receiving data)

    16.Can I build a production-level driver with character drivers?

    Yes. Many real-world drivers (UART, I2C user interfaces, debug interfaces) are built using character drivers.

    For detailed understanding of Platform Devices and Drivers on Linux, refer to the official Linux documentation on Platform Devices and Drivers .

  • Understanding PID Control Explained: The Complete Beginner’s Guide to How It Actually Works

    Learn how PID control works Proportional, Integral, and Derivative explained simply with real examples, tuning methods, and code. Perfect for beginners.

    If you’ve ever wondered how a car cruise control stays locked at exactly 100 km/h on a hilly road, or how a drone hovers perfectly still in a gusty breeze, or how your home thermostat keeps the temperature from swinging wildly the answer to all three is the same thing: a PID controller. And once you understand it, you’ll start seeing it everywhere.

    This guide is about understanding PID control explained in plain language. Whether you’re a hobbyist building your first Arduino project, an engineering student preparing for interviews, or a professional who wants to finally nail the intuition behind something you’ve been using for years this is for you.

    What Is PID Control? Start Here Before Anything Else

    PID stands for Proportional, Integral, and Derivative. It’s a control loop mechanism a feedback-based algorithm that continuously calculates an error value as the difference between a desired setpoint and a measured process variable, then applies a correction based on three terms.

    Imagine you’re driving a car and you want to maintain 80 km/h. Your eyes are checking the speedometer (that’s measurement), your brain compares what it sees to what you want (that’s error calculation), and your foot adjusts pressure on the accelerator (that’s the control output). You’re already doing PID in your head without knowing it.

    The PID controller just does this automatically, much faster than a human can, and with mathematical precision. It reads a sensor, compares the reading to a target (called the setpoint), computes an error, and drives an actuator a motor, a heater, a valve, a servo to reduce that error as fast as possible without overshooting.

    PID control is used in robotics, industrial automation, HVAC systems, drones, chemical plants, audio equipment, and even financial algorithms. One study estimated over 90% of industrial control loops use some form of PID control. That should tell you how fundamental this is.

    The History Behind PID: Where It Came From and Why It Survived

    PID control wasn’t invented overnight. The roots go back to the early 1900s. Elmer Sperry is often credited with early feedback control work on ship steering gyroscopes. But the formal mathematical framework for what we now call PID was developed by Nicolas Minorsky in 1922, who studied automatic ship steering for the U.S. Navy.

    In the 1930s and 40s, Taylor Instrument Companies introduced pneumatic PID controllers for industrial process control. These were entirely mechanical air pressure changed based on error, and that pressure drove valves. Remarkably, the underlying logic was identical to what we implement digitally today.

    By the 1980s, digital PID controllers became standard as microprocessors got cheap enough for industrial use. Today, every major PLC (Programmable Logic Controller) platform has PID blocks built in. Every embedded platform Arduino, STM32, Raspberry Pi has open-source PID libraries. The algorithm has been around for over a century and it’s still the go-to tool because it works, it’s simple to implement, and engineers understand how to tune it.

    The Three Terms Explained: P, I, and D One at a Time

    Proportional Control (P): React to What’s Happening Right Now

    The proportional term is the simplest. It produces an output proportional to the current error. If the error is large, the output is large. If the error is small, the output is small.

    Think of it like this: you’re trying to park a car in a tight spot. The farther away you are from the target position, the harder you press the reverse pedal. As you get closer, you ease off. That’s proportional action.

    Mathematically: P output = Kp x error

    Where Kp is the proportional gain. A higher Kp means a more aggressive response. The main limitation of pure proportional control is that it almost always leaves a steady-state error the system gets close but never quite reaches the setpoint. This is why we need the other two terms.

    Integral Control (I): Remember the Past and Fix Accumulated Error

    The integral term looks at the history of the error. It accumulates the error over time. If the error has been sitting at a small positive value for a long time, the integral term keeps building up, adding more corrective force until the system is actually driven to the setpoint.

    Think of a room that’s slightly colder than you want. The heater is on but not quite powerful enough to hit the target. The integral term in the thermostat notices the room has been too cold for ten minutes, adds that up, and pushes the heater harder until it actually hits the target.

    Mathematically: I output = Ki x (sum of all past errors x time)

    The integral term eliminates steady-state error. But it comes with its own problem: integral windup. If the system has been in error for a long time, the integral can accumulate a huge value and cause the system to overshoot badly when it finally can respond. Anti-windup clamping is the standard fix.

    Derivative Control (D): Predict the Future and Slow Down Before Overshooting

    The derivative term reacts to the rate of change of the error, not the error itself. If the error is rapidly decreasing, the derivative term applies a braking force it slows the correction before the system reaches the setpoint, preventing overshoot.

    Think of driving toward a stop sign. A smart driver starts braking before reaching the line. The derivative term is that braking — it detects that you’re approaching the target fast and applies reverse force to prevent overshoot.

    Mathematically: D output = Kd x (rate of change of error)

    The practical challenge with the derivative term is noise sensitivity. Almost all real sensors have some noise, and the derivative amplifies it, causing the actuator to chatter. That’s why many real-world implementations use a derivative filter or just run a PI controller instead.

    The PID Equation: Putting All Three Terms Together

    The full PID control equation is:

    u(t) = Kp x e(t)  +  Ki x integral[e(t)dt]  +  Kd x de(t)/dt

    • u(t) is the control output sent to the actuator
    • e(t) is the error at time t (setpoint minus measured value)
    • Kp, Ki, Kd are the gain parameters you tune
    • The integral term accumulates past errors to eliminate steady-state offset
    • The derivative term applies a braking force based on how fast the error is changing

    In a digital system, this becomes a discrete-time approximation computed every fixed time step (the sample period). The quality of your PID implementation depends a lot on how consistently you run the loop. Use hardware timers or RTOS tasks with fixed periods — never delay() in your production PID code.

    How a PID Controller Works in a Real System: Step by Step

    Let’s trace through a complete PID control loop on a real example: controlling the speed of a DC motor using a microcontroller and an encoder.

    1. Measure: The encoder reads the current motor speed. Let’s say it measures 850 RPM.
    2. Calculate error: Setpoint is 1000 RPM. Error = 1000 – 850 = 150 RPM.
    3. Compute P term: With Kp = 0.5, P output = 0.5 x 150 = 75.
    4. Compute I term: Integral has accumulated. Say integrated value = 20, Ki = 0.1, so I output = 2.
    5. Compute D term: Error improved from 180 to 150 RPM this cycle. Rate = -3000 RPM/s. With Kd = 0.001, D = -3 (small brake).
    6. Sum: Total output = 75 + 2 + (-3) = 74. This maps to a PWM duty cycle that increases motor voltage.
    7. Wait for next sample period (10ms), read encoder again, repeat.

    After several cycles, the motor converges on 1000 RPM and holds it there, even if load changes try to drag it down. That’s PID working in real time.

    PID Tuning Methods: How to Actually Find the Right Gains

    Manual Tuning: The Trial-and-Error Method

    • Set Ki and Kd to zero. Start with only proportional control.
    • Increase Kp until the system responds well and starts to oscillate. Back off Kp by about 50%.
    • Add Ki slowly until steady-state error is eliminated. Watch for overshoot.
    • Add Kd carefully if still seeing too much overshoot. Filter the derivative if the system chatters.

    Ziegler-Nichols Method: The Classic Engineering Approach

    Developed in 1942, this method gives you a systematic starting point:

    1. Set Ki and Kd to zero.
    2. Increase Kp until the system oscillates steadily. This is the Ultimate Gain (Ku).
    3. Note the oscillation period — the Ultimate Period (Tu).
    4. Apply Z-N formulas: Kp = 0.6 x Ku, Ki = 2 x Kp / Tu, Kd = Kp x Tu / 8.

    This gives an aggressive controller with ~25% overshoot. You’ll still need to fine-tune, but you’ll be in the right ballpark. Caveat: pushing a system to the edge of instability isn’t always safe or acceptable.

    Step Response / FOPDT Method: Model the System First

    Apply a step input open-loop and record the output response. Extract three parameters: Process gain K (how much does output change per unit input), Dead time L (how long before output starts responding), Time constant T (time to reach 63% of final value). These describe a First Order Plus Dead Time (FOPDT) model. Published formulas like IMC-based tuning or Cohen-Coon convert K, L, T directly into PID gains without needing to push the system to oscillation.

    Common PID Tuning Problems and How to Recognize Them

    • Slow and sluggish response: Kp too low. Increase it. If still slow, Ki may also be too low.
    • Oscillating around the setpoint: Kp too high. Back it off. If persists, Ki may also be too high.
    • Large overshoot: Kp too high or Kd too low. Reduce Kp first. If still overshooting, add/increase Kd.
    • Steady-state error: Ki is what you need. Increase it until error is eliminated, watching for overshoot.
    • Chattering actuator: Derivative amplifying sensor noise. Add a low-pass filter to the sensor or the derivative calculation.
    • Integral windup: After long error periods, system massively overshoots. Fix with anti-windup clamping.

    Types of PID Controllers: Position vs Velocity Form

    When you implement a PID controller in code, you have two main options:

    Position Form PID: The standard form. The output at any time is the direct sum of P, I, and D terms, representing the absolute actuator position/value. Works fine for most applications. Challenge: if the controller restarts mid-operation, the output can jump suddenly because the integral was reset.

    Velocity (Incremental) Form PID: Computes the change in output (delta) at each step rather than the absolute value. Naturally bumpless — if the controller switches on or the setpoint changes, there’s no sudden jump. Preferred in industrial applications for motor drives, valve positioners, or any system where sudden output changes cause mechanical stress.

    PID Control in the Real World: Industry Applications

    Temperature Control

    Ovens, autoclaves, injection molding machines, chemical reactors, soldering stations, 3D printer hotends — all use temperature PID loops. Temperature systems are typically slow (high thermal mass), have significant dead time, and often don’t need the derivative term at all. A PI controller is usually sufficient and preferred to avoid amplifying thermocouple noise.

    Motor Speed and Position Control

    Servo drives, CNC machines, robotic joints — all use PID for speed control and often cascaded PID (inner speed loop, outer position loop) for precise positioning. Motor control loops run at high frequency (1 to 10 kHz is common), making discrete-time implementation details critical. Sample time jitter can cause noticeable degradation in control quality.

    Drone Flight Control (Attitude Control)

    Every commercial drone uses PID control to maintain attitude (roll, pitch, yaw) and altitude. The gyroscope measures angular rate, the accelerometer measures tilt, and PID loops on each axis drive individual motor speeds to maintain stability. Flight controller firmware like Betaflight exposes PID gains directly. Drone PID tuning is a rich subculture with communities dedicated to finding optimal gains for specific airframe geometries.

    Automotive Systems

    Cruise control is the textbook example, but modern cars have PID loops all over: electronic throttle body control, antilock brake systems (ABS), electronic stability control, fuel injection timing, turbocharger wastegate control, and active suspension. Safety-critical PID implementations go well beyond basic gains — they include gain scheduling, state machines, saturation limits, and extensive diagnostic monitoring.

    HVAC and Building Automation

    Heating, ventilation, and air conditioning systems use PID to control temperature, humidity, CO2 levels, and pressure differentials. Building automation controllers often have dozens of PID loops running simultaneously. The thermal inertia of buildings means these loops have very slow dynamics — the integral term does most of the heavy lifting.

    Limitations of PID Control: When It’s Not Enough

    • Nonlinear systems: PID is a linear controller. For highly nonlinear systems, gain scheduling (different Kp/Ki/Kd at different operating points) is a common fix.
    • Large dead time: If there’s a long delay between control action and measured response, the integrator accumulates a lot of error before it can see the result. Smith Predictor or model predictive control handle this better.
    • Coupled multi-variable systems: Multiple interacting inputs and outputs can cause PID loops to fight each other. Multi-variable control strategies or decoupling networks are needed.
    • Time-varying systems: If the system dynamics shift over time (wear, fouling, changing loads), fixed-gain PID eventually drifts out of optimal tuning. Adaptive PID adjusts gains automatically but adds significant complexity.

    Advanced PID Concepts Worth Knowing

    Cascade (Nested) PID Control

    Instead of one controller, you have two — an outer loop and an inner loop. The output of the outer loop becomes the setpoint for the inner loop. Classic example: a temperature control system for a chemical reactor. The outer loop controls reactor temperature (slow dynamics). Its output becomes the setpoint for an inner loop that controls heating fluid flow (faster dynamics). Key rule: the inner loop must be at least 3 to 5 times faster than the outer loop for the approach to work properly.

    Feed-Forward Control

    PID is purely reactive it responds to errors after they’ve happened. Feed-forward is predictive. If you know a disturbance is coming, you can add a feed-forward term to compensate before the error even develops. In practice, feed-forward and PID feedback are used together: feed-forward handles known predictable disturbances, PID handles everything else. This gives much faster disturbance rejection than feedback alone.

    Anti-Windup Strategies

    • Clamping: Hard limit on the integral accumulator. Simple but can be abrupt.
    • Back-calculation: When output saturates, feed the difference back to unwind the integrator. Smoother than clamping.
    • Conditional integration: Only accumulate integral when within a certain range of the setpoint.

    Gain Scheduling

    For nonlinear systems, define multiple sets of PID gains and switch between them based on operating point. A simple implementation might have three gain sets: low, medium, high. A sophisticated version uses continuous interpolation between gain sets. Gain scheduling is widely used in aircraft flight controllers and automotive powertrain control.

    Implementing PID in Code: A Practical Example

    Here’s a clean, production-quality PID implementation in pseudocode. This pattern works in C, Python, or any procedural language:

    struct PID {     float Kp, Ki, Kd;     float setpoint;     float integral;     float prev_error;     float output_min, output_max;     float dt;     float prev_derivative; };  float pid_compute(PID *pid, float measurement) {     float error = pid->setpoint – measurement;      // Proportional     float P = pid->Kp * error;      // Integral with clamping anti-windup     pid->integral += error * pid->dt;     pid->integral = clamp(pid->integral,         pid->output_min / pid->Ki,         pid->output_max / pid->Ki);     float I = pid->Ki * pid->integral;      // Derivative with first-order filter     float raw_deriv = (error – pid->prev_error) / pid->dt;     float alpha = pid->N * pid->dt / (1.0f + pid->N * pid->dt);     float D_filt = alpha * raw_deriv + (1.0f – alpha) * pid->prev_derivative;     float D = pid->Kd * D_filt;      pid->prev_error = error;     pid->prev_derivative = D_filt;      return clamp(P + I + D, pid->output_min, pid->output_max); }

    Key design points in this implementation:

    • The integral is clamped before multiplying by Ki cleaner than clamping the raw accumulator
    • Derivative uses a first-order IIR low-pass filter controlled by N (higher = less filtering = more noise sensitivity)
    • Output is clamped to physical actuator limits
    • dt must be accurate — measure from actual system clock, don’t assume

    PID in Arduino: Getting Started Quickly

    The fastest way to start experimenting with PID is on an Arduino using Brett Beauregard’s well-tested PID library. Install it through the Arduino Library Manager and you’ll have a clean, anti-windup-ready implementation in minutes:

    #include <PID_v1.h>  double setpoint = 100; double input = 0; double output = 0; double Kp = 2.0, Ki = 5.0, Kd = 1.0;  PID myPID(&input, &output, &setpoint, Kp, Ki, Kd, DIRECT);  void setup() {     myPID.SetMode(AUTOMATIC);     myPID.SetOutputLimits(0, 255); }  void loop() {     input = readSensor();     myPID.Compute();     analogWrite(pwmPin, output);     delay(10);  // 100 Hz loop }

    Brett’s library handles anti-windup, derivative filter, and consistent sample timing internally. Read his blog series ‘Improving the Beginner’s PID’ — it’s one of the best engineering blog posts ever written about practical PID implementation.

    PID Tuning Tips from Experience That Textbooks Usually Skip

    • Always know your sample rate first. Before thinking about gains, make sure your PID loop runs at a consistent, appropriate frequency. For temperature: 1 to 10 Hz. For motor speed: 100 to 1000 Hz. For power converters: 10 to 100 kHz.
    • Fix your sensor before tuning. A noisy sensor will make your PID look like it’s misbehaving when it’s actually working fine. Filter your sensor reading first.
    • Check for mechanical problems before blaming the PID. Backlash, sticky actuators, and compliance look exactly like PID tuning problems but no amount of gain adjustment will fix them.
    • Understand your actuator limits. If your heater or motor is already saturated, PID can’t help. Make sure the actuator is sized for the job first.
    • Start with PI, add D only if needed. For most everyday applications — temperature, level, flow — a well-tuned PI controller performs excellently.
    • Document your tuning process. Write down what you changed and what happened. Without notes you’ll end up going in circles.

    Frequently Asked Questions About PID Control

    What’s the difference between PID and on-off control?

    On-off control switches the actuator fully on or fully off based on whether the measurement is above or below the setpoint. It causes constant oscillation around the setpoint and wear on the actuator. PID produces a proportional output that varies continuously, allowing it to balance precisely at the setpoint without constant switching.

    What’s the difference between PID and state-space control?

    PID is an input-output controller it works with the error signal only and doesn’t need an internal model of the system. State-space control uses an explicit mathematical model of the system’s internal states and can optimize performance in ways PID cannot. State-space methods are more powerful for complex multi-variable systems, but require much more modeling work. PID wins on simplicity, robustness to model mismatch, and ease of field tuning.

    What’s a good first project to learn PID hands-on?

    Temperature control of a heating element with a thermocouple and SSR, or a DC motor speed controller with encoder feedback. Temperature control is slow (forgiving of timing errors), intuitive, and cheap to set up. Motor control is faster and teaches more about discrete-time implementation. Either will teach you more in two hours of hands-on work than a week of reading theory.

    PID Control in Embedded Systems: Special Considerations

    • Fixed sample period: Use a hardware timer interrupt or RTOS periodic task to trigger PID computation. Never use delay() or sleep() — these are imprecise and will corrupt your integral and derivative.
    • Overflow and saturation: Check your data types. Use 32-bit or 64-bit accumulators for the integral. Clip the integral and output explicitly to their allowed ranges.
    • Initialization: On startup, initialize integral to zero and previous error to the current measurement to avoid derivative spikes on the first computation.
    • Mode switching: Implement bumpless transfer when switching between manual and automatic control.
    • Fault handling: A production PID controller needs watchdog monitoring, sensor failure detection, and safe output defaults.

    The Big Picture: Why PID Control Still Matters in 2025 and Beyond

    With machine learning and neural networks transforming engineering, you might wonder if PID control is becoming obsolete. The short answer is no — and the reason is instructive.

    Neural network controllers and reinforcement learning agents can learn optimal control policies for complex nonlinear systems. But deploying such a controller in a safety-critical industrial plant, medical device, or automotive system brings huge challenges: the controller is a black box (can’t be analyzed or certified easily), it requires enormous training data, it can fail unpredictably on out-of-distribution inputs, and regulatory frameworks like ISO 26262 and IEC 61508 currently have no established certification pathway for neural network controllers in safety-critical applications.

    PID, by contrast, is fully analyzable. You can prove stability mathematically. The behavior is predictable and explainable. It’s certifiable. And it works. For the vast majority of industrial, automotive, and embedded control applications, the incremental performance gain from a sophisticated AI controller doesn’t justify the engineering, certification, and maintenance overhead.

    What is changing is how PID tuning is done. Machine learning is being used to automatically identify system models, run rapid auto-tuning, and implement adaptive gain scheduling. Neural networks are handling highly nonlinear dynamics while PID loops handle the linear inner control loops. The two approaches are increasingly complementary rather than competitive.

    Summary: What You Should Now Understand About PID Control

    A PID controller is a feedback control algorithm with three terms: Proportional (reacts to current error), Integral (corrects accumulated past error), and Derivative (anticipates future error based on trend). Each term has a gain you tune to achieve the desired balance of speed, accuracy, and stability.

    • Proportional gives you fast response but leaves steady-state error.
    • Integral eliminates steady-state error but can cause overshoot and windup.
    • Derivative reduces overshoot and improves damping but amplifies noise.
    • A well-tuned PID combines all three for fast, accurate, stable control.

    Its limitations nonlinear systems, large dead time, multi-variable coupling are solvable with extensions like cascade control, feed-forward, and gain scheduling. For most practical control problems, a well-implemented PID is not just adequate — it’s the right tool for the job.

    Now go build something. The best way to internalize this is to run a real loop, watch a real response graph, and tune until it behaves the way you want. That experience will teach you more than any article ever can.

    Recommended Resources for Going Deeper

    • Brett Beauregard’s ‘Improving the Beginner’s PID’ blog series : best practical PID implementation guide ever written.
    • Karl Astrom and Richard Wittenmark : ‘Computer-Controlled Systems’ — authoritative textbook on discrete-time control theory.
    • Franklin, Powell, Emami-Naeini : ‘Feedback Control of Dynamic Systems’ — classic undergraduate control systems text.
    • MATLAB Control System Toolbox documentation : excellent worked examples for frequency-domain analysis and PID design.
    • Arduino PID Library (Brett Beauregard) : GitHub source is well-commented and worth reading to understand implementation choices.
    • Betaflight PID tuning guides : if you’re into drones, the Betaflight community has extremely practical real-time PID tuning guides.

    If you are completely new to drones altogether, start with this guide on Types of Drones Explained: Your Complete Beginner’s Guide for 2026 first, then come back here it will make everything below click faster.

  • Flight Physics Basics Explained: How Airplanes Really Fly (And Why It’s Cooler Than You Think)

    A beginner’s complete guide to lift, drag, thrust, weight, Bernoulli’s principle, Newton’s laws, angle of attack, and everything else that keeps a 900,000-pound metal tube in the sky.

    Picture this. You’re sitting in seat 24B, pressed back as the engines roar. The ground blurs outside the window, and then somehow hundreds of tonnes of metal just lifts off the Earth. You’ve seen it a thousand times. You’ve done it yourself. But if someone asked you to explain exactly how it works, most people go quiet.

    That’s not a knock on anyone. Flight physics basics are one of those things that sound simple on the surface “wings push air down, plane goes up” but the real answer is layered, fascinating, and way more intuitive than the textbooks make it sound.

    In this guide, we’re going deep. Not PhD-dissertation deep deep like the kind of conversation you’d have with an engineer friend who actually explains things without making you feel dumb. By the time you’re done reading, you’ll understand the four forces of flight, why Bernoulli’s principle matters, how Newton’s laws apply to aircraft, what angle of attack actually means, and why commercial jets stay up at 35,000 feet without falling out of the sky.

    Fun fact: Flight physics isn’t magic. It’s physics figured out piece by piece over 120 years, starting with two bicycle mechanics from Ohio who refused to believe humans couldn’t fly.

    Let’s start from the beginning.

    1. Why Does Anything Fly? The Big Picture of Aerodynamics for Beginners

    Before getting into forces and equations, let’s frame the problem correctly. For something to fly really fly, not just fall slower — it needs to overcome gravity. That’s the whole game.

    Gravity pulls every object downward with a force equal to mass times gravitational acceleration (about 9.8 m/s²). For a Boeing 747 at max takeoff weight (around 412,000 kg), that’s roughly 4 million Newtons of downward force pinning it to the ground.

    To get airborne, the aircraft needs to generate an equal or greater upward force. That upward force is called lift. And generating enough lift consistently, controllably, efficiently — is what the entire science of aerodynamics for beginners is really about. According to NASA’s Glenn Research Center Guide to Aerodynamics, aerodynamics affects everything from large airliners to kites — it is simply the study of forces and motion of objects moving through air.

    Definition: Aerodynamics is the study of how air moves around objects and what forces that movement creates. It’s a branch of fluid dynamics — because air behaves like a fluid when objects move through it at speed.

    Air Is Not Nothing

    Here’s something people underestimate: air has mass. At sea level, a cubic meter of air weighs about 1.225 kg. That might not sound like much, but when wings are pushing through thousands of cubic meters of air per second, those interactions add up to millions of Newtons of force.

    The key insight in understanding how do airplanes fly is that air resists being moved. When a wing moves through air, the air doesn’t politely step aside. It gets pushed, compressed, accelerated, and deflected — and it pushes back. All of those pushes and pulls, shaped correctly, sum up to lift.

    What Makes a Wing Different from a Flat Board?

    A flat board held at the right angle will generate some lift. A properly shaped wing called an airfoil does it far more efficiently. The shape matters enormously, and that’s where two of the most important concepts in flight physics enter: Bernoulli’s principle and Newton’s third law. We’ll look at both properly in a moment.

    2. The Four Forces of Flight: Lift, Drag, Thrust, and Weight

    Every aircraft — from a paper airplane to the Space Shuttle — experiences four fundamental forces during flight. These are the core of flight physics basics explained in a way that actually sticks. As NASA explains, the four forces of flight — lift, weight, thrust, and drag — make an object move up and down, and faster or slower, with the amount of each force compared to its opposing force determining how an object moves through the air.

    ForceDirectionRole
    LiftUpward, perpendicular to flight pathCounters weight. Generated mainly by wings.
    WeightDownward, toward Earth’s centerAlways present. Result of gravity acting on aircraft mass.
    ThrustForward, along flight pathGenerated by engines or propellers. Overcomes drag.
    DragBackward, opposing forward motionAir resistance. Created by shape, friction, and lift itself.

    Lift vs. Weight: The Vertical Battle

    When lift equals weight, the aircraft maintains altitude. When lift exceeds weight, it climbs. When weight exceeds lift, it descends. Pilots manage this balance constantly — not just by pointing the nose up or down, but by adjusting speed, flap settings, and engine power.

    One thing people get wrong: an aircraft doesn’t need to be nose-up to climb. If the engines produce enough thrust and the wings generate surplus lift, a plane can climb while appearing relatively level. Conversely, an aircraft can descend with its nose slightly raised if flying slowly and losing lift.

    Thrust vs. Drag: The Horizontal Battle

    Thrust is what moves the aircraft forward. Without forward motion, wings can’t generate lift (in conventional fixed-wing aircraft). So thrust is indirectly responsible for keeping the plane up.

    Drag is the enemy of efficiency. There are two main types. Induced drag is created as a byproduct of generating lift — it’s unavoidable. Parasite drag is everything else: friction, fuselage shape, landing gear, antennas, rivets. Aircraft designers spend enormous effort reducing parasite drag while managing induced drag through smart wing design. The SKYbrary Aviation Safety article on Lift offers an excellent technical breakdown of how these forces interact in real aircraft operations.

    Key insight: When an aircraft is in straight, level, unaccelerated flight, all four forces are balanced: lift = weight, thrust = drag. Pilots call this state “trimmed flight.”

    Equilibrium, Climbs, and Descents

    In reality, aircraft are almost never in perfect balance — they’re constantly making small adjustments. Autopilot systems in modern commercial jets make these corrections hundreds of times per second. Understanding that flight is dynamic, not static, is one of the first mental shifts that changes how you think about aerodynamics.

    3. How Wings Generate Lift: Bernoulli’s Principle and Newton’s Laws Together

    This is probably the most misunderstood part of flight physics, and the internet has a bad habit of oversimplifying it. Let’s fix that.

    Most school textbooks explain lift using the Bernoulli principle flight explanation alone. The story: the top of a wing is curved, so air traveling over it has farther to go than air along the flat bottom. To “keep up,” the upper air must travel faster. Faster-moving air has lower pressure (Bernoulli’s principle). Lower pressure on top, higher pressure below, pushes the wing upward. Lift!

    This isn’t exactly wrong — Bernoulli’s principle is real and pressure differences do create lift. But it’s incomplete. The “equal transit time” assumption (that top and bottom air must arrive at the trailing edge simultaneously) is actually false. Air over the top of a wing arrives significantly earlier than air below — the separation is real, but it’s not explained by equal transit time.

    The Bernoulli Principle: What It Actually Says

    Daniel Bernoulli was an 18th-century Swiss mathematician who discovered a fundamental relationship between fluid velocity and pressure. As Britannica explains in its overview of Bernoulli’s theorem, the principle states that the total mechanical energy of a flowing fluid — comprising pressure energy, gravitational potential energy, and kinetic energy — remains constant. In practical terms: where a fluid speeds up, pressure decreases, and where it slows down, pressure increases.

    Air flowing over the curved upper surface of a wing does speed up — not because it needs to “catch up,” but because the wing’s geometry directs it through a path where the airflow naturally accelerates. This acceleration reduces pressure on top. The higher-pressure air below pushes up. That pressure difference is a real, measurable component of the lift drag thrust weight equation.

    But here’s what the Bernoulli-only story misses: it doesn’t fully account for how much lift is actually generated, especially at high angles of attack. That’s where Newton comes in.

    Newton’s Third Law and the Deflection of Air

    Newton’s third law states that for every action, there is an equal and opposite reaction. When a wing moves through air, it deflects air downward. That’s the action. The reaction is an equal upward force on the wing. That upward force is lift.

    This is not a competing explanation to Bernoulli — it’s complementary. The FAA’s official Glider Flying Handbook (Chapter 3) puts it clearly: Newton’s third law describes the overall interaction between atmosphere and wing — as air deflects downward due to interaction with the wing, the wing experiences an upward lifting reaction — while Bernoulli’s principle looks at the effect of air changing speed as it moves past the wing. Together, these models provide a valid and complete explanation of lift.

    Mental model: Bernoulli explains the pressure distribution around the wing. Newton explains why the air gets deflected and why that deflection means the wing must be pushed up. Both are right. Both are needed.

    Modern aerodynamicists use computational fluid dynamics (CFD) software that models all these effects simultaneously to predict lift with extreme precision. For understanding how wings generate lift, just know: the wing’s shape and angle together cause air to move in ways that create more pressure below than above, and that pressure difference lifts the aircraft.

    The Role of Wing Shape: Airfoil Design

    Not all airfoils are equal. The shape of a wing’s cross-section — its camber, thickness, and chord length — dramatically affects how much lift it generates, at what speed, and how efficiently.

    • Camber: the curvature from leading to trailing edge. More camber means more lift at low speeds — which is why flaps (which increase effective camber) help during takeoff and landing.
    • Chord length: the straight-line distance from leading to trailing edge. Longer chord means more wing area interacting with air.
    • Thickness: thicker airfoils tolerate higher angles of attack before stalling; thinner airfoils suit high-speed supersonic flight.
    • Span: distance from wingtip to wingtip. Longer wings reduce induced drag — hence the long, slender wings on fuel-efficient jets like the Boeing 787.

    Fighter jets use thin, often symmetric airfoils for high-speed maneuverability. Commercial jets use thick, cambered airfoils for efficiency at subsonic cruise speeds. Gliders use extremely high-aspect-ratio wings to maximize lift-to-drag ratios and stay airborne for hours.

    4. Angle of Attack: The Most Important Variable You’ve Never Heard Of

    If there’s one concept in flight physics basics explained properly that changes how you understand flying, it’s angle of attack. Not pitch angle, not nose position — angle of attack. They’re different things, and the difference really matters.

    What Is Angle of Attack?

    The angle of attack (AoA) is the angle between the chord line of a wing (the straight line from leading edge to trailing edge) and the relative wind — the direction air is actually coming from as seen by the aircraft.

    When a pilot pulls back on the controls, they increase the angle of attack. The wing hits the incoming air at a steeper angle, deflects more air downward, and creates more lift. But only up to a point. The FAA’s Pilot’s Handbook of Aeronautical Knowledge — Chapter 5 covers this in detail, including how the FAA now promotes angle of attack indicators as a key safety tool to reduce loss-of-control accidents.

    Critical distinction: Pitch angle (how high the nose is pointed) and angle of attack are NOT the same thing. An aircraft can have a low pitch angle but a high angle of attack if it’s descending rapidly. Or a high pitch angle but low angle of attack if climbing at speed.

    The Lift Curve: More AoA Means More Lift… Until It Doesn’t

    As angle of attack increases from zero, lift increases in a nearly linear fashion. More AoA means more air deflected downward, means more lift. This is the good part.

    But at a certain critical angle — typically around 15 to 20 degrees for most subsonic aircraft — something bad happens. The airflow over the top of the wing can no longer follow the wing’s contour. It separates, becomes turbulent and chaotic, and stops generating lift. This is called a stall.

    A stall has nothing to do with the engine quitting. It’s purely an aerodynamic event — the wing stops making lift because angle of attack is too high. A stall can happen at any airspeed, any attitude, any power setting. It’s purely a function of exceeding the critical angle of attack.

    This is why stall training is one of the most fundamental parts of pilot education, and why commercial jets have angle of attack indicators and stick shakers — physical warnings that shake the control column to tell pilots they’re approaching the stall boundary.

    Low-Speed Flight and High-Lift Devices

    At low speeds, wings generate less lift. To compensate during takeoff and landing, pilots extend flaps, slats, and other high-lift devices. These increase the wing’s effective camber and area, allowing it to generate more lift at lower airspeeds — but they also increase drag, which is acceptable close to the ground at low speeds.

    5. Newton’s Laws of Motion Applied to Aircraft: All Three of Them

    We touched on Newton’s third law, but Newton’s laws of flight show up across every aspect of aviation. Let’s go through all three with concrete aircraft examples — because this is where aerodynamics stops being abstract and starts making real-world sense.

    Newton’s First Law: Inertia and Straight-Line Flight

    An object in motion stays in motion in a straight line at constant velocity unless acted on by an unbalanced force. For aircraft: in a perfect vacuum with no gravity and no air resistance, a plane would fly straight forever at the same speed without any thrust.

    Reality is messier. Gravity constantly pulls the aircraft down. Drag constantly slows it. So pilots must continuously apply thrust and manage control surfaces to counteract these forces. The autopilot does this automatically on modern airliners, applying hundreds of tiny adjustments per second.

    Newton’s Second Law: Force, Mass, and Acceleration

    Force equals mass times acceleration (F = ma). This is the most quantitatively useful law for engineers.

    In level flight, the net force in every direction is zero — no acceleration because the four forces are balanced. The moment any force becomes unbalanced, the aircraft accelerates in that direction. Pilots use this constantly during maneuvers.

    This law also explains why heavier aircraft need longer runways. More mass requires more force (thrust) to reach takeoff speed. With fixed engine thrust, more mass means slower acceleration and a longer ground roll before the wings generate enough lift to become airborne.

    Newton’s Third Law: Action-Reaction Throughout Aviation

    Every action has an equal and opposite reaction. We covered how wings deflect air down to create upward lift. But this law appears everywhere in aviation:

    • Propeller thrust: a propeller accelerates air backward. That airflow pushes the aircraft forward.
    • Helicopter rotors: blades deflect air downward to generate lift. The torque reaction spins the helicopter body in the opposite direction — which is why helicopters need a tail rotor.
    • Rocket propulsion: rockets expel hot gas backward at enormous velocity. The reaction accelerates the rocket forward — even in space where there’s no air to push against.

    Myth buster: A jet engine doesn’t “push against air.” It accelerates mass backward. The reaction pushes the engine forward. In space, rockets work the same way — they carry their own oxidizer since there’s no atmospheric oxygen to burn.

    6. How Engines Work: Generating Thrust in Different Ways

    Lift gets the aircraft up. Thrust keeps it moving. Without forward motion in a conventional fixed-wing aircraft, there is no lift. Understanding how engines generate thrust completes the picture of how does an aircraft stay up from a full systems perspective.

    Piston Engines and Propellers

    The Wright Brothers’ Flyer used a piston engine driving a propeller. Piston engines burn fuel in cylinders to drive pistons, which rotate a crankshaft, which turns a propeller. The propeller is just a rotating wing — it generates thrust the same way a wing generates lift, by accelerating air backward.

    Piston engines dominate general aviation. They’re simple, relatively lightweight, and efficient at low altitudes. But they lose efficiency rapidly at high altitude because thinner air provides less oxygen to burn fuel.

    Gas Turbine Engines: Turboprops, Turbofans, and Turbojets

    Commercial aviation runs on gas turbines. These work on the Brayton cycle: compress air, mix with fuel, ignite, expand rapidly through a turbine. The turbine drives the compressor (and in turboprops, the propeller). Exhaust provides additional thrust.

    The turbofan dominates modern commercial jets. It has a large fan at the front that moves enormous amounts of air. Some goes through the combustion chamber (the core). Most bypasses it entirely (bypass flow). The ratio of bypass to core flow is the bypass ratio.

    High bypass ratio engines (like the GE9X at over 10:1) are far more fuel-efficient at subsonic cruise speeds and significantly quieter. Low bypass ratio engines, used in military fighters, trade efficiency for raw thrust at supersonic speeds.

    The Thrust Equation

    Thrust is fundamentally about momentum change: Thrust = mass flow rate × (exit velocity − inlet velocity). To maximize thrust, you either increase how much air you move or how fast you accelerate it. High-bypass turbofans move a lot of air at moderate velocity — efficient and quiet. Turbojets move less air at very high velocity — powerful but fuel-hungry.

    7. Drag: The Force Nobody Wants But Everybody Gets

    Drag is the aerodynamic force that opposes forward motion through air. Understanding drag determines fuel burn, range, top speed, and aircraft design. Reducing drag while maintaining lift is the central engineering challenge in aviation.

    Parasite Drag

    Parasite drag is generated by the aircraft’s physical presence in the airstream, regardless of what the wings are doing. It has two main components.

    Form drag comes from the aircraft’s shape. A blunt nose creates far more form drag than a streamlined one — which is why aircraft have pointed noses, streamlined fuselages, and retractable landing gear.

    Skin friction drag comes from air molecules sliding along the aircraft’s surface. As described in the FAA Pilot’s Handbook of Aeronautical Knowledge summary, the boundary layer between the wing and the free-stream airflow is only about as wide as a playing card — but aircraft designers still remove protrusions and use flush-mount rivets to reduce friction, because every bit of skin friction drag costs fuel over millions of flight hours.

    Parasite drag increases with the square of airspeed. Double the speed, quadruple the parasite drag. This is why supersonic flight consumes disproportionately more fuel.

    Induced Drag

    Induced drag is created as a direct consequence of generating lift. It’s unavoidable whenever a wing is making lift. When a wing generates lift, the pressure difference between top and bottom causes air to curl around the wingtips from below to above, creating swirling vortices. These wingtip vortices tilt the lift vector slightly backward — and that backward tilt is induced drag.

    Induced drag increases as airspeed decreases. At low speeds during takeoff and landing, induced drag is dominant. At high cruise speeds, parasite drag takes over. SKYbrary’s article on Bernoulli’s principle provides a detailed technical look at how pressure distributions across the wing surface contribute to both lift and the induced drag penalty that comes with it.

    Real-world application: The winglets on modern commercial jets aren’t just aesthetic. They reduce the strength of wingtip vortices, cutting induced drag by 3–5%. Over a fleet of hundreds of aircraft flying millions of hours, that’s an enormous fuel saving — and the math pencils out quickly for airlines.

    The Total Drag Curve and Minimum Drag Speed

    Because parasite drag increases with speed and induced drag decreases with speed, there’s a speed at which total drag is minimized. This is called L/D max — the speed of maximum lift-to-drag ratio. Flying at L/D max gives the aircraft its best glide ratio (critical in engine-out emergencies) and is often close to the most fuel-efficient cruise speed.

    8. Stability and Control: How Aircraft Stay Straight

    An aircraft doesn’t just need to fly. It needs to fly predictably and return to stable flight when disturbed by turbulence or pilot inputs. This is where stability and control come in — two related but distinct concepts in flight physics basics.

    Axes of Rotation: Roll, Pitch, and Yaw

    Aircraft rotate around three axes, each controlled by different surfaces:

    • Pitch: nose up or nose down, controlled by the elevator. Pitching changes the angle of attack.
    • Roll: banking left or right, controlled by ailerons near the wingtips. Rolling tilts the lift vector, causing the aircraft to turn.
    • Yaw: nose left or right, controlled by the rudder on the vertical tail. Important during turns and crosswind landings.

    In a coordinated turn, the pilot uses ailerons (roll) and rudder (yaw) together while adding back pressure on the elevator (pitch) to maintain altitude. Three-axis control happening simultaneously — which is why flight simulators are genuinely hard to fly realistically.

    Longitudinal Stability: Why the Tail Exists

    The horizontal stabilizer — the small wing on the tail — produces downward lift. This sounds counterintuitive. Why generate downward force?

    Because the aircraft’s center of lift is typically behind its center of gravity, creating a nose-down pitching moment. The horizontal tail counters this by producing a downward force that creates a nose-up moment. It’s like a see-saw where the tail pushes down to keep everything level.

    This design also creates positive longitudinal stability. If the nose pitches up due to a gust, the changing aerodynamic forces naturally tend to push it back down. The aircraft self-corrects — a property called static longitudinal stability.

    Fly-by-Wire: When Computers Take Over

    Some aircraft — the F-16 and many airliners like the Airbus A320 family — are designed to be aerodynamically unstable. Left to themselves, they would tumble out of control. Computers making thousands of corrections per second make them appear perfectly stable to the pilot.

    An aerodynamically unstable aircraft is inherently more maneuverable. Military aircraft exploit this for extreme agility. Commercial fly-by-wire systems use envelope protection — the computers simply won’t allow the aircraft to exceed structural or aerodynamic limits regardless of what the pilot does.

    9. High-Speed Flight: Transonic Flight, Compressibility, and the Sound Barrier

    Everything above applies comfortably to subsonic flight. But at speeds approaching and exceeding Mach 1, new physical effects emerge that fundamentally change the aerodynamics. This is where flight physics basics explained gets genuinely mind-bending.

    What Is the Speed of Sound and Why Does It Matter?

    The speed of sound at sea level and 15°C is about 343 m/s (roughly 1,235 km/h). At altitude, where air is colder, it’s lower — around 295 m/s at 35,000 feet. Sound travels as pressure waves through air. When an aircraft approaches the speed of sound, it’s approaching the speed at which it can “warn” the air ahead of it that it’s coming.

    At subsonic speeds, pressure waves propagate ahead of the aircraft, letting air start adjusting. As the aircraft approaches Mach 1, these waves bunch up. At exactly Mach 1, the aircraft keeps pace with its own pressure waves — they pile up at the nose, creating a shock wave.

    Transonic Flight and the Drag Rise

    Most commercial jets cruise at Mach 0.78 to 0.85. Even at these speeds, air over the curved wing surfaces accelerates to local supersonic speeds — creating pockets of supersonic flow that terminate in shock waves. This is the transonic regime.

    These shock waves cause a dramatic increase in drag — wave drag. Early jets pushing into this regime experienced severe drag increases and control problems. This is what people called the “sound barrier” — not a physical wall, but a barrier of rapidly increasing drag that early aircraft couldn’t overcome.

    The solution was swept wings. By sweeping the wings back, designers reduced the component of airspeed perpendicular to the leading edge, delaying the onset of local supersonic flow. Almost every commercial jet and military aircraft uses swept wings for this reason.

    Supersonic Flight: Shock Waves and Sonic Booms

    Once an aircraft exceeds Mach 1, it flies faster than its own pressure waves. It creates a cone-shaped shock wave — the Mach cone. This shock wave carries enormous energy and, when it reaches the ground, is heard as a sonic boom — a continuous phenomenon as long as the aircraft is supersonic, not a one-time event.

    Fascinating fact: The Concorde cruised at Mach 2.04 — twice the speed of sound — at 60,000 feet. The airframe heated to over 120°C from aerodynamic friction. Its distinctive drooping nose extended for takeoff and landing visibility, then retracted for the needle-nosed shape needed to minimize supersonic drag.

    10. Atmosphere and Altitude: How the Air Changes Everything

    Aircraft don’t fly in a uniform medium. The atmosphere changes dramatically with altitude, affecting every aspect of flight performance. This is why what keeps a plane in the air at sea level involves different engineering considerations than what keeps it flying at 40,000 feet.

    The Atmosphere in Layers

    Commercial aviation takes place in the troposphere (ground to about 36,000 feet) and the lower stratosphere (above 36,000 feet). The boundary between them is the tropopause.

    In the troposphere, temperature decreases with altitude at about 2°C per 1,000 feet. Weather happens here. Above the tropopause, temperature stabilizes. Commercial jets often cruise just above or at the tropopause to escape weather turbulence and get the efficiency benefits of cold, still air.

    Density Altitude: The Number Pilots Really Care About

    Air density decreases with altitude. Less dense air means fewer air molecules per cubic meter — which means wings generate less lift for a given speed, and engines produce less thrust because there’s less oxygen to burn. As the NASA Technical Report on Aerodynamics (NASA SP-367) explains, air density is a very important factor in lift, drag, and engine power output, and it depends on both temperature and local pressure — not just altitude alone.

    Density altitude is the altitude your aircraft performs as if it were at, corrected for temperature and pressure. On a hot day at a high-elevation airport, the density altitude can be thousands of feet higher than actual elevation. Takeoffs from Denver (elevation ~5,400 feet) on a hot summer day require significantly longer runways and more speed than sea-level departures on a cool day.

    Density altitude accidents are tragically common in general aviation. Pilots who don’t account for performance degradation in hot, high conditions attempt takeoffs their aircraft can’t complete.

    Cruise Altitude: Why 35,000 Feet?

    Commercial jets cruise at high altitudes for three reasons. First, thinner air means less parasite drag, allowing high speeds with less thrust. Second, engines are more efficient in cold, thin air. Third, weather is more predictable above the troposphere.

    But altitude has limits. Above a certain point, the stall speed (minimum speed for controlled flight) approaches the maximum operating speed (above which structural damage could occur). The range between these narrows until there’s no margin left — the aerodynamic ceiling, typically around 40,000–45,000 feet for commercial jets.

    11. Takeoff and Landing: Flight Physics in the Most Critical Phases

    Takeoff and landing are when flight physics becomes most consequential. Most accidents occur in these phases, not during cruise. Understanding why helps explain everything from runway length calculations to approach procedures.

    Takeoff Physics

    During the takeoff roll, the aircraft accelerates down the runway. Wings start generating lift as soon as there’s airflow — but not enough to lift off until rotation speed (Vr) is reached. At Vr, the pilot pulls back, increasing angle of attack, generating enough lift to become airborne.

    The critical speed is V1 — the decision speed. Before V1, if an engine fails, the pilot aborts the takeoff. After V1, even with an engine failure, the aircraft must continue — there’s no longer enough runway to stop. Calculating V1, Vr, and V2 (initial climb speed) for every takeoff, accounting for weight, runway length, elevation, temperature, and wind, is a precise science governed by FAA regulations and performance standards.

    Landing Physics

    Landing is, in one sense, a controlled stall near the ground. The pilot gradually reduces speed on approach, keeping the aircraft just above its stall speed, then flares (raises the nose) just before touchdown to reduce descent rate. The flare increases angle of attack, generating a brief moment of extra lift that slows the descent for a gentler touchdown.

    Crosswind landings are a beautiful demonstration of multi-axis control. The pilot simultaneously uses rudder to align the nose with the runway centerline, ailerons to counteract sideways drift, and elevator to control descent rate — all while the wind is trying to push the aircraft sideways.

    Autoland systems on modern commercial jets can land automatically in near-zero visibility. Cat III ILS approaches allow landings where the pilot literally cannot see the runway until the wheels are almost on it.

    12. Stalls, Spins, and How Pilots Handle Them

    Stalls deserve a deeper look — understanding them is one of the most important safety concepts in aviation, and one that’s frequently misunderstood by non-pilots.

    Aerodynamic Stalls

    A stall occurs when the critical angle of attack is exceeded. Airflow over the wing separates, turbulence replaces smooth laminar flow, and lift drops dramatically. The aircraft begins to descend.

    In training, student pilots learn to recognize approaching stall symptoms: decreasing airspeed, mushy controls, buffeting (shaking caused by turbulent airflow hitting the tail), and the stall warning horn or stick shaker. Recovery is counterintuitive: reduce the angle of attack (lower the nose), add power, and as airspeed recovers, climb.

    The counterintuitive part: when stalling and losing altitude, the instinct is to pull back harder. But that increases angle of attack further, deepening the stall. The correct recovery is to push forward — trust the physics, lower the nose, recover flying speed.

    Accelerated Stalls and Overbanked Turns

    The critical angle of attack doesn’t change — but the speed at which you reach it does. In a steep turn, the wing must generate more lift to maintain altitude. Without enough speed, the wing can stall at a much higher speed than in level flight — an accelerated stall.

    In a 60-degree bank turn, the aircraft needs twice its normal lift. Stall speed increases by about 41%. In a 75-degree bank, the stall speed doubles — and most aircraft aren’t stressed to handle four times their weight in lift forces consistently. This is covered in detail in the FAA’s aviation aerodynamics documentation, which explains how load factor increases rapidly as bank angle increases, with stall speed rising in proportion to the square root of the load factor.

    Spins: A Stall Gone Wrong

    If one wing stalls before the other — which can happen if the aircraft is yawing at the moment of stall — the aircraft enters a spin. One wing generates much more lift than the other, creating a rolling and yawing motion pulling the aircraft into a rapidly rotating descent.

    Spin recovery is a specific procedure: reduce power, apply full opposite rudder to stop the rotation, push forward to reduce angle of attack, then pull out of the resulting dive. In most commercial aviation, spin training isn’t required — aircraft are designed and certified with systems that prevent the conditions leading to spins.

    13. The Future of Flight Physics: Electric Aviation, eVTOL, and What’s Next

    The physics of flight don’t change — lift is still generated the same way it was in 1903. But the technologies used to create lift, generate thrust, and control aircraft are evolving faster than at almost any point in aviation history.

    Electric Propulsion and Its Limitations

    Electric motors are dramatically simpler than turbines, have fewer moving parts, and can be distributed around an aircraft in ways that enable entirely new designs. Small electric aircraft are already flying. The challenge is energy density: the best lithium-ion batteries store roughly 1/50th the energy per kilogram of jet fuel. This limits electric aircraft to short ranges and small sizes — for now.

    Hybrid electric systems (a gas turbine generating electricity that powers electric motors) are a near-term solution that may enable efficiency gains for regional aircraft. But truly electric commercial aviation for long-haul routes awaits battery technology improvements that haven’t happened yet.

    eVTOL: Electric Vertical Takeoff and Landing

    The eVTOL category is one of the most dynamic in aviation right now. Companies like Joby Aviation, Archer, Lilium, and Wisk are developing aircraft that use multiple electric rotors — some tilting, some fixed — to take off vertically like a helicopter and cruise horizontally like a fixed-wing aircraft.

    In hover mode, these aircraft support their weight entirely with rotor-generated thrust. In cruise mode, wing-generated lift takes over and the rotors tilt forward to provide thrust. The transition between these modes is one of the most complex aerodynamic challenges in modern eVTOL design.

    Hypersonic Flight

    At speeds above Mach 5, conventional aerodynamics breaks down. Air in front of the aircraft is heated to plasma temperatures by shock waves. Scramjet engines (supersonic combustion ramjets) can theoretically work at these speeds, but controlling and sustaining hypersonic flight remains one of the hardest engineering challenges in existence. Space planes, future long-haul transport concepts, and military vehicles are all areas where hypersonic research is accelerating rapidly.

    14. Frequently Asked Questions About Flight Physics

    What is the simplest explanation of how airplanes fly?

    A plane generates lift by moving wings through air. The wing’s shape and angle cause air to push the wing upward with more force than the aircraft’s weight. Engines generate thrust to keep the aircraft moving forward, which keeps the wings generating lift. Four forces — lift, weight, thrust, and drag — interact to determine whether the aircraft climbs, descends, or maintains level flight.

    Is Bernoulli’s principle enough to explain lift?

    No. Bernoulli’s principle explains part of lift — the pressure difference between upper and lower wing surfaces. But Newton’s third law (the wing deflects air downward, creating an upward reaction force) is equally important. Real lift requires both effects simultaneously, and neither alone fully predicts the numbers that aerodynamicists actually calculate. For a deeper dive, SKYbrary’s Bernoulli’s Principle article provides a rigorous technical breakdown used by aviation safety professionals worldwide.

    Can a plane fly upside down?

    Yes, many aircraft can fly inverted. Aerobatic aircraft use symmetric airfoils that generate lift equally right-side-up or upside-down — the pilot simply adjusts angle of attack. Even non-aerobatic aircraft can briefly fly inverted if the pilot maintains the correct angle of attack, though engines and fuel systems may not function normally in that orientation.

    Why does a plane need to maintain speed to fly?

    Because wings need airflow over them to generate lift. Without relative airflow — which comes from the aircraft moving forward through air — there’s no pressure difference, no air deflection, and no lift. In a conventional fixed-wing aircraft, the minimum speed for controlled flight is the stall speed. Below that speed, the angle of attack becomes too high and the wing stops generating lift.

    What actually happens during turbulence?

    Turbulence is chaotic, irregular airflow caused by terrain, thunderstorms, jet streams, and clear-air turbulence. When an aircraft flies through it, the aircraft experiences rapid, irregular changes in aerodynamic forces on its wings and fuselage — which manifest as bumping and jolting. Modern aircraft are structurally stressed to handle loads far beyond what turbulence can realistically impose.

    Safety note: Commercial aircraft are stress-tested to loads up to 3.75g positive and -1.5g negative — nearly four times the aircraft’s weight. Turbulence, while uncomfortable, rarely approaches these limits.

    How does a pilot control which direction the plane goes?

    Through three sets of control surfaces: ailerons (on the wings, control roll), elevator (on the tail, controls pitch), and rudder (on the vertical tail, controls yaw). In modern commercial jets, fly-by-wire computers translate pilot inputs into precise surface movements while applying envelope protection to prevent pilots from inadvertently exceeding structural or aerodynamic limits.

    Conclusion: Flight Physics Basics Are More Intuitive Than You Think

    Here’s the thing about flight physics basics explained properly: once you understand the core concepts, they stop being mysterious and start being logical. Of course wings create lift by manipulating pressure and deflecting air. Of course more speed means more lift up to the point where the airflow can’t follow the wing. Of course engines need to work harder to overcome drag that grows with the square of airspeed.

    The Wright Brothers didn’t have computers, CFD software, or a century of aviation research. They had careful observation, systematic testing, and a genuine understanding of the forces at work. They built a wind tunnel in their bicycle shop and methodically worked through wing designs until they found what worked.

    The physics they were working with is exactly what we’ve covered here. The four forces of flight. Bernoulli’s principle creating pressure differences. Newton’s laws governing every acceleration and reaction. Angle of attack as the primary variable controlling lift. Compressibility effects as speeds increase. Stability as the aircraft’s tendency to return to equilibrium.

    Whether you’re an aviation enthusiast who wanted to understand what happens when you board a plane, a student starting your aviation journey, or someone genuinely curious about physics — you now have a solid foundation. The window seat will never look quite the same, and the next time you feel those engines spool up for departure, you’ll know exactly what’s about to happen and why.

    Final thought: Flight is not magic. It’s physics applied with extraordinary precision, refined over 120 years, to achieve something that once seemed impossible. And every commercial flight you take is proof that humans got very, very good at it.

    Related Topics to Explore Next

    • How jet engines work a detailed breakdown
    • Pilot training basics: what student pilots learn first
    • Aircraft stability and control systems explained
    • The history of aviation: from the Wright Brothers to modern jets
    • How autopilot systems work on commercial aircraft
    • Understanding weather and turbulence from a physics perspective
    • Electric aviation and the future of sustainable flight

    References and Further Reading

    1. NASA Glenn Research Center — Guide to Aerodynamics — Comprehensive beginner’s guide to aerodynamics from NASA’s official research division.
    2. NASA — What Is Aerodynamics? (Educational Resource) — NASA’s accessible explanation of the four forces of flight and how they interact.
    3. FAA — Pilot’s Handbook of Aeronautical Knowledge, Chapter 5: Aerodynamics of Flight — The official FAA handbook chapter covering all aspects of flight aerodynamics, used by student pilots and flight instructors.
    4. FAA — Glider Flying Handbook, Chapter 3: Aerodynamics of Flight (PDF) — FAA official resource explaining Newton’s laws and Bernoulli’s principle as complementary explanations of lift.
    5. SKYbrary Aviation Safety — Bernoulli’s Principle — Technical breakdown of Bernoulli’s principle as it applies to aerofoil lift, from the EUROCONTROL-managed aviation safety reference.
    6. SKYbrary Aviation Safety — Lift — Authoritative overview of how lift is generated on an aircraft, covering wing design, pressure differentials, and the relationship between lift and the other forces of flight.
    7. Encyclopaedia Britannica — Bernoulli’s Theorem — Academic reference covering the history and physics of Bernoulli’s principle from the 1738 original discovery to modern applications.
    8. NASA SP-367 — Introduction to the Aerodynamics of Flight (Technical Report, PDF) — NASA’s foundational technical publication on flight aerodynamics, covering fluid flow, lift, drag, stability, and high-speed effects.
    9. The Physics Classroom — Bernoulli’s Equation — Clear, educational explanation of Bernoulli’s equation and fluid dynamics for students and curious readers.

    If you are completely new to drones altogether, start with this guide on Types of Drones Explained: Your Complete Beginner’s Guide for 2026 first, then come back here it will make everything below click faster.

  • Drone Anatomy for Programmers Explained: The Complete Beginner’s Guide to Understanding Every Component

    Learn drone anatomy for programmers explained from scratch motors, ESCs, flight controllers, sensors, MAVLink, and PID loops all explained in plain language so your code actually makes sense.

    If you have ever stared at a drone and thought “I want to program this thing, but I have no idea what I am looking at” this guide is for you.

    Most tutorials online assume you either already know hardware or do not care about it. Neither of those is helpful if you want to actually write code that controls a physical flying machine. You need to understand the drone’s body before you can talk to it intelligently. Think of it like learning API docs before you start writing integrations. You would not call endpoints blindly without knowing what data goes in and what comes out.

    Drone anatomy for programmers explained properly means understanding not just the names of parts, but why those parts exist, how they communicate, and what your code is actually telling them to do. That is what this article covers from the ground up.

    Why Programmers Need to Understand Drone Hardware

    Here is the thing most drone programming tutorials skip: you can copy-paste flight code all day and still produce a drone that flies erratically, crashes, or simply does not do what you intended. The reason is almost always a disconnect between the programmer and the physical machine.

    When you write drone.move_forward(speed=50), something physical is happening. Motors are spinning at different speeds. A sensor is correcting for wind drift. A PID controller is making micro-adjustments 400 times per second. If you do not know what those layers look like, debugging is basically guesswork.

    Understanding drone hardware components for developers is not about becoming a mechanical engineer. It is about knowing your interface. You do not need to build a motor from scratch, but you do need to understand that a motor has a maximum RPM, that it responds to PWM signals, and that asking it to do too much will cause brownouts or overheating.

    This is the same reason good backend developers understand database internals even when using an ORM. The abstraction is useful, right up until it is not.

    Drone Anatomy for Programmers

    The Big Picture: Drone System Architecture

    Before diving into individual parts, zoom out and look at the overall system. A drone is essentially a distributed embedded system. Multiple sensors feed data into a central flight controller, which makes decisions and sends commands to motors via speed controllers. Optionally, a companion computer runs your higher-level code and talks to the flight controller through a communication protocol.

    Here is a simplified view of the data flow:

    Sensors → Flight Controller → ESCs → Motors → Physical Motion

    And in parallel:

    Your Code → Companion Computer → MAVLink/Serial → Flight Controller → ESCs → Motors

    Every component in that chain matters. Drop any one of them and the drone either does not fly or flies unpredictably. As someone writing code for drones, you sit in the middle of that chain, and understanding every node makes you a dramatically better programmer.

    1. The Frame: The Skeleton Your Code Lives On

    The frame is the physical structure that holds everything together. Most programmers ignore it completely, but the frame actually affects your code in surprising ways.

    Frame Configuration and Motor Layout

    Drones most commonly come in three configurations: tricopter (3 motors), quadcopter (4 motors), hexacopter (6 motors), and octocopter (8 motors). The vast majority of drones developers work with are quadcopters, and those come in two standard layouts: X configuration and + configuration.

    In X configuration, the drone’s nose points between two arms. In + configuration, one arm points straight forward. This changes which motor combination the flight controller uses for forward pitch, and it also changes how your telemetry data maps to physical orientation when you are debugging flight logs.

    When you work with a flight controller or autopilot system like ArduPilot or PX4, you have to tell it the frame type during configuration. Get this wrong in your setup code and the drone will flip on takeoff.

    Frame Size and Its Coding Implications

    Frame size is measured in millimeters diagonally between motors, so a 250mm quad has motors 250mm apart corner to corner. Larger frames carry heavier payloads including bigger cameras, more sensors, or companion computers. They also have more rotational inertia, which means the PID tuning parameters you use in your flight controller configuration need to be different.

    If you are writing code that auto-tunes PID values, or if you are configuring an existing autopilot, frame size is one of the inputs you need. It is not just a hardware detail.

    2. Motors: What Your ESC Commands Actually Do

    Motors are where electrical signals become physical rotation. For programmers, understanding motors is about understanding the relationship between your commands and actual angular velocity.

    Brushless DC Motors: How They Work

    Almost every serious drone uses brushless DC (BLDC) motors. Unlike brushed motors, BLDC motors do not have physical contact between the rotating and stationary parts. Instead, the speed controller electronically commutates the three-phase power to spin the motor.

    What this means for your code is that you never directly command a motor. You command an ESC, which interprets your signal and applies the appropriate voltage phasing to the motor. The motor’s actual behavior is one abstraction layer below your code.

    KV Rating: The Spec That Matters for Developers

    Motor KV rating tells you how many RPM the motor spins per volt of input with no load. A 2300KV motor on a 3S battery (11.1V nominal) spins at roughly 25,000 RPM unloaded.

    Why does this matter to you as a programmer? Two reasons.

    First, when you are doing thrust calculations or simulations, KV directly feeds into your motor model. If you are writing a physics-based simulation or a software-in-the-loop (SITL) test environment, you need this number.

    Second, KV affects how quickly the motor responds to throttle changes. Higher KV motors react faster, which matters for control loop tuning. If your PID parameters were written for a low-KV motor and you swap to a high-KV motor, your code will become unstable without retuning.

    Motor Direction: CW and CCW

    On a quadcopter, motors spin in alternating directions. Two spin clockwise (CW) and two spin counterclockwise (CCW). This is not arbitrary. The opposing torque forces cancel out, preventing the drone from spinning uncontrollably on its yaw axis.

    In code, when you issue a yaw command, the flight controller speeds up all the CW motors slightly and slows down all CCW motors (or vice versa), creating a net torque that rotates the airframe. If your motor order or direction is wrong in the flight controller configuration, yaw commands will do unexpected things. Diagnosing this almost always comes back to motor mapping.

    3. ESCs: The Interface Between Code and Motors

    The Electronic Speed Controller (ESC) is arguably the most important hardware interface for drone programmers to understand. Your flight controller sends signals to ESCs, and ESCs translate those signals into the three-phase AC power that spins brushless motors.

    ESC Protocols: The Language Your Code Uses

    This is where drone hardware gets genuinely interesting from a programming perspective. ESCs do not just accept a generic signal. They accept specific protocols, and the protocol you use has real implications for your system’s performance.

    PWM (Pulse Width Modulation): The oldest and most universal protocol. A 1ms pulse means minimum throttle, a 2ms pulse means maximum, and everything in between is proportional. The issue is refresh rate, typically limited to 50Hz, which means the ESC only receives a new command 50 times per second. For a control loop running at 400Hz, that is a severe bottleneck.

    OneShot125 and OneShot42: These are faster versions of PWM. OneShot125 runs pulses between 125 and 250 microseconds (8x faster than PWM). OneShot42 is even faster. They sync the ESC update rate to the flight controller’s loop rate, dramatically reducing latency.

    DSHOT: This is a fully digital protocol, and it is the modern standard. Unlike PWM which uses pulse timing and is vulnerable to noise and drift, DSHOT sends actual binary packets. DSHOT300, DSHOT600, and DSHOT1200 refer to the bitrate in kbits/second. With DSHOT, you also get bidirectional communication meaning the ESC can send RPM telemetry back to the flight controller, which is extremely useful for RPM-based filtering and control.

    KISS and BLHeli protocols: These are ESC firmware-level protocols that add configuration and telemetry capabilities. ESC configuration (like motor direction, timing, and demag settings) can be done programmatically if you implement these protocols in your software.

    For a programmer choosing a protocol: use DSHOT if your ESC and flight controller both support it. The digital reliability and bidirectional telemetry are worth it.

    ESC Firmware and What You Can Actually Configure

    Modern ESCs run firmware like BLHeli_32 or AM32 that you can flash and configure via USB or via a pass-through from the flight controller. If you are building a drone automation system, knowing that ESC firmware parameters like motor timing and PWM frequency are configurable via software is useful. ESC timing affects motor efficiency and heat, and some autopilot configurations involve pushing ESC parameter changes during runtime.

    Current, Voltage, and Protecting Your Hardware in Code

    ESCs have a continuous current rating and a burst rating. Exceeding continuous ratings for extended periods will cause thermal shutdown or permanent damage. As a drone programmer, this means your code should respect throttle ramp rates and not issue abrupt full-throttle commands, especially during complex maneuvers.

    When you write automated flight scripts, smooth throttle transitions are not just about comfortable flight, they are about hardware longevity. Hard throttle spikes also cause voltage spikes that can corrupt flight controller data or trigger brownout detection.

    4. Flight Controller: The Brain You Program Against

    The flight controller (FC) is the embedded computer that runs the real-time control algorithms keeping your drone stable. This is the most important piece of hardware to understand deeply because most of your code either runs on it or talks to it.

    What the Flight Controller Actually Does

    Every control loop cycle, the flight controller reads sensor data, runs stabilization algorithms, and outputs motor commands. This happens at rates between 1kHz and 32kHz on modern hardware. At the same time, it manages communication with your ground control station, RC receiver, GPS, and any companion computer you have connected.

    Popular flight controllers include the Pixhawk series (which runs ArduPilot or PX4 firmware), Betaflight boards (popular in FPV racing), and various custom boards. Each has different capabilities and different programming interfaces.

    Betaflight, ArduPilot, and PX4: What the Difference Means for Your Code

    This is something beginners frequently get confused about. The flight controller is hardware, but the firmware running on it defines your programming interface.

    Betaflight is optimized for manual FPV flying with extremely fast loop times. Its CLI (Command Line Interface) is accessible via serial and can be scripted. Betaflight is not really designed for autonomous flight it has limited GPS and waypoint capability. Programming against Betaflight usually means configuring its parameters, not running complex autonomous missions.

    ArduPilot is the workhorse of autonomous drone programming. It runs on Pixhawk hardware and supports full GPS-based autonomous missions, guided mode control, MAVLink communication, and Python scripting via DroneKit. If you are writing code to make a drone navigate a complex route, avoid obstacles, or run automated inspection tasks, you are probably using ArduPilot.

    PX4 is ArduPilot’s main competitor in the autonomous space. It has a more modern software architecture, excellent ROS (Robot Operating System) integration, and is popular in research settings. The MAVSDK library lets you control PX4-based drones in Python, C++, Swift, and Java.

    Choosing between ArduPilot and PX4 is often an ecosystem decision. ArduPilot has a larger community and more vehicle types. PX4 is more developer-friendly in terms of code architecture if you want to modify the firmware itself.

    PID Controllers: The Algorithm at the Heart of Stability

    You will hear PID everywhere in drone programming. PID stands for Proportional, Integral, Derivative, and it is the control algorithm that keeps the drone stable. When you command a 30-degree pitch angle and the drone only achieves 28 degrees, the PID controller calculates the error (2 degrees), adjusts motor speeds to correct it, and keeps doing this hundreds of times per second.

    As a programmer, you will interact with PID parameters in several ways. You will configure them in your flight controller settings, you might implement your own PID loops for position control in your companion computer, and you will need to understand them to debug unstable flight behavior.

    The three parameters are:

    P (Proportional): How aggressively the drone corrects errors. Too high causes oscillation. Too low causes sluggish response.

    I (Integral): Corrects for persistent offset errors like steady wind drift. Too high causes slow oscillation. Too low means the drone never fully reaches its target.

    D (Derivative): Dampens corrections to prevent overshoot. Too high causes high-frequency vibration. Too low causes wobbling.

    PID tuning is part science, part art. Tools like Betaflight’s Blackbox logging and PX4’s Flight Review let you analyze flight data and adjust parameters algorithmically. There are also autotune functions in ArduPilot that can run flight maneuvers and calculate optimal PID values automatically.

    Flight Modes and What They Mean for Your Code

    Flight controllers support multiple flight modes that define how they interpret commands. This is critical to understand before writing any control code.

    Acro (Rate) Mode: Your commands directly set rotation rates. Full pitch stick means spin at X degrees per second. No stabilization. Highest precision but hardest to fly. Most FPV pilots use this.

    Angle (Self-Level) Mode: Your commands set a target angle, not a rate. Release the stick and the drone levels itself. Good for beginners and payload drones.

    Altitude Hold Mode: The flight controller uses barometric pressure to maintain a constant altitude. Forward/backward commands still work, but the drone does not climb or descend unless you specifically command it.

    Loiter/Position Hold Mode: GPS-based position hold. Release all sticks and the drone hovers in place. GPS drift can cause slow wandering, which your position control code needs to handle.

    Guided Mode (ArduPilot) / Offboard Mode (PX4): This is the mode your code uses for autonomous control. In Guided/Offboard mode, the flight controller takes movement commands from an external computer via MAVLink or uORB. This is the gateway to writing code that actually makes autonomous decisions.

    5. Sensors: The Data Your Code Reads and Trusts

    A drone is a sensor-dense machine. Understanding each sensor type, its refresh rate, its error characteristics, and how the flight controller fuses its data is essential for writing reliable autonomous code.

    Inertial Measurement Unit (IMU)

    The IMU is the most fundamental sensor. It contains an accelerometer and a gyroscope in a single chip. The accelerometer measures linear acceleration (including gravity), and the gyroscope measures angular velocity.

    The flight controller reads the IMU at very high rates, often 1kHz or more, and runs a complementary or Kalman filter to estimate the drone’s attitude (roll, pitch, yaw orientation). Without the IMU, the drone cannot stabilize itself at all.

    What this means for your code: IMU data is your most immediate sensor reading, but it accumulates error over time (gyroscope drift) and is noisy in the short term. When you read attitude data from the flight controller, understand it has already been filtered and fused. If you are building custom state estimation, you need to implement your own filter on top of raw IMU data.

    Temperature affects IMU accuracy. Consumer-grade drones usually do IMU calibration at room temperature. In cold weather operations, expect more drift and potentially more aggressive PID oscillations until the IMU warms up.

    Barometric Pressure Sensor

    The barometer measures atmospheric pressure to estimate altitude. It is accurate to roughly 10-20cm in calm conditions but is extremely sensitive to prop wash (airflow from the motors blowing into the barometer) and wind gusts.

    Flight controllers typically have foam covers over the barometer to reduce prop wash effects. In your code, when you are doing altitude-critical operations like landing on a platform or flying at a fixed height indoors, barometer-based altitude is often not reliable enough. You need to fuse it with other sensors.

    GPS: Position Data Your Autonomous Code Depends On

    The GPS module gives you latitude, longitude, altitude, and speed. Most drones use an external GPS module mounted on a mast above the frame to get it away from electromagnetic interference from the power system.

    GPS accuracy is typically 1-3 meters CEP (Circular Error Probable) with a standard GPS. RTK (Real-Time Kinematic) GPS can get you to centimeter-level accuracy using correction signals from a base station. If you are writing code for precision landing, surveying, or agricultural spraying, RTK GPS is often necessary.

    GPS has latency. There is a delay between physical movement and the GPS position update, typically 100-200ms. In high-speed autonomous flight code, you need to account for this lag or your position corrections will always be slightly behind reality. Kalman filter implementations in autopilots do this through GPS-IMU fusion, but custom position controllers need to handle it explicitly.

    GPS spoofing and jamming are real concerns for drone security. If you are writing code for critical applications, GPS sanity checking (comparing GPS position with optical flow or other position sensors) adds a layer of protection.

    Optical Flow Sensor

    An optical flow sensor is basically a downward-facing camera that measures how fast ground features are moving beneath the drone. Combined with a rangefinder for altitude, it gives precise horizontal velocity measurements that GPS cannot provide.

    Optical flow is invaluable for indoor flight where GPS is unavailable, and for precise hovering at low altitudes outdoors. The big limitation is that it needs a textured surface to work. Flying over water, sand, or featureless white surfaces gives the optical flow sensor nothing to track, and position estimates degrade rapidly.

    In your code, optical flow data typically comes in as velocity measurements in body frame (relative to where the drone is pointing). Transforming these into world-frame velocity requires knowing the drone’s current heading, which comes from the IMU.

    Rangefinder and Lidar

    Rangefinders measure distance to surfaces below the drone. Ultrasonic rangefinders work well indoors up to about 3-4 meters. Lidar (laser rangefinder) sensors are more accurate, work at greater ranges, and function better outdoors.

    For landing code, a rangefinder is practically essential. Using barometer altitude for precision landing introduces enough error that you can easily overshoot by 20-30cm, which is fine on grass but problematic on a landing pad or ship deck.

    Rangefinders are also used for terrain following, where the drone maintains a constant height above the ground rather than a constant barometric altitude. Writing terrain-following code requires reading rangefinder data in a tight control loop and adjusting throttle accordingly.

    Compass (Magnetometer)

    The compass measures the Earth’s magnetic field to determine the drone’s absolute heading. It is critical for GPS-based flight because the GPS tells you where you are but not which way you are facing.

    Compass calibration is one of the most common sources of problems in drone programming. Magnetic interference from the power system, motors, and ESCs can overwhelm the compass reading if the magnetometer is too close to these components, which is why GPS modules with integrated compasses are mounted on masts.

    In your flight code and configuration, always ensure compass offsets are calibrated before autonomous flights. ArduPilot’s automatic compass learning can help in some cases, but hard iron and soft iron calibrations done on the ground are generally more reliable.

    Airspeed Sensor (Fixed-Wing and VTOL)

    For fixed-wing drones and VTOL (Vertical Takeoff and Landing) aircraft transitioning to forward flight, an airspeed sensor that measures the pressure differential between pitot tube and static port gives true airspeed measurement. Ground speed from GPS and true airspeed together let you calculate wind speed and direction, which feeds into wind-aware path planning code.

    6. Power System: How Voltage and Current Affect Your Code

    The power system is easy to overlook from a programming perspective, but it has direct impacts on flight behavior, sensor reliability, and code stability.

    LiPo Batteries: Voltage Curves and What They Mean

    Lithium Polymer (LiPo) batteries are the standard for drone power. Each cell has a nominal voltage of 3.7V, a fully charged voltage of 4.2V, and a minimum safe voltage of around 3.5V per cell. A 4S battery (4 cells in series) has a nominal voltage of 14.8V.

    Here is the critical insight for programmers: a LiPo battery’s voltage drops under load. At full throttle, a 4S battery might read 14.8V at rest but drop to 13.5V under full load. This voltage sag is not just a hardware problem. It affects your motor performance estimates. If you have code that calculates available thrust based on voltage, you need to account for sag under load, not just resting voltage.

    More importantly, your flight controller monitors battery voltage and should trigger a low-battery warning or RTL (Return to Launch) failsafe at a configured threshold. Make sure your code handles these failsafes gracefully rather than assuming full power will always be available.

    Power Distribution Board (PDB) and Voltage Regulators

    The Power Distribution Board takes the battery voltage and distributes it to ESCs and other components. Many modern flight controller stacks integrate the PDB directly. The PDB also provides regulated 5V and 12V rails for the flight controller, servos, and peripherals.

    Your companion computer, if you have one, also needs power. Running a Raspberry Pi or NVIDIA Jetson from the drone battery requires a quality BEC (Battery Eliminator Circuit) that provides clean regulated power. Noise on the power rail can cause I2C and SPI sensor communication errors, which show up in your code as sporadic sensor readings or communication timeouts.

    Current Sensor and Power Monitor

    Most advanced flight controllers include a current sensor that measures how much current the battery is supplying in real time. Combined with voltage measurement, this gives you instantaneous power draw and cumulative mAh consumption.

    In your code, mAh consumed is your most reliable battery state metric. Voltage alone is noisy under load. Tracking mAh from a known capacity lets you estimate remaining flight time with much better accuracy. Implementations of battery-aware path planning typically use mAh budgets rather than voltage thresholds.

    7. Communication Interfaces: How Your Code Talks to the Drone

    This section is purely code-relevant. These are the actual interfaces your software uses.

    MAVLink: The Protocol of Drone Autonomy

    MAVLink (Micro Air Vehicle Link) is the communication protocol used by ArduPilot and PX4. It is a binary protocol that defines hundreds of message types for everything from requesting telemetry data to sending navigation commands to receiving sensor readings.

    When you write Python code using DroneKit or MAVSDK, you are sending and receiving MAVLink messages under the hood. Understanding MAVLink at the packet level is useful when debugging communication issues or when you need to implement custom message types.

    Key MAVLink message types you will frequently encounter:

    HEARTBEAT: Sent every second by both the ground station and the autopilot. Both sides need to see heartbeats to consider the connection active. Your code must send heartbeats or the autopilot will trigger a communication loss failsafe.

    COMMAND_LONG and COMMAND_INT: Used to send commands like DO_SET_MODE, NAV_TAKEOFF, NAV_WAYPOINT, NAV_LAND. COMMAND_INT uses integer coordinates (in degrees * 1e7) which avoids floating-point precision issues for GPS coordinates.

    SET_POSITION_TARGET_LOCAL_NED: Used in Guided/Offboard mode to send velocity, position, or acceleration setpoints in local North-East-Down frame. This is the bread and butter of custom autonomous navigation code.

    GLOBAL_POSITION_INT: Telemetry message containing current GPS position, altitude, and velocity. Your position monitoring loop reads this constantly.

    Serial Communication and Baud Rates

    Flight controllers have multiple UART serial ports. Each can be configured to run a different function: MAVLink telemetry, RC receiver input, GPS input, ESC telemetry, or Bluetooth/WiFi module connection.

    When connecting a companion computer to a flight controller, you typically use a serial connection at 921600 baud or higher for low-latency communication. Getting the baud rate and flow control settings right in your serial configuration is necessary before MAVLink can work reliably.

    ROS and MAVROS for Research Applications

    If you are working in a research environment, you will likely encounter ROS (Robot Operating System). ROS provides a publish-subscribe messaging infrastructure that connects different software nodes. MAVROS is a ROS package that acts as a bridge between ROS topics/services and MAVLink, allowing you to write drone control nodes in the familiar ROS paradigm.

    With MAVROS, you can subscribe to topics like /mavros/local_position/pose to get position data, publish to /mavros/setpoint_velocity/cmd_vel to command velocity, and use services like /mavros/set_mode to change flight modes. If you are doing drone swarms, sensor fusion research, or computer vision-based navigation, the ROS ecosystem has mature tools that integrate cleanly through MAVROS.

    SPI, I2C, and UART: Onboard Sensor Communication

    Inside the flight controller, sensors communicate with the main processor via SPI or I2C buses. The IMU typically uses SPI for its high data rate. GPS uses UART. The barometer and compass often use I2C.

    This matters if you are adding custom sensors to your drone. Attaching an I2C sensor to the flight controller’s I2C bus is straightforward if the sensor has a driver in ArduPilot or PX4. Writing a custom sensor driver requires implementing the appropriate bus protocol and integrating your readings into the flight controller’s sensor fusion pipeline, which is a non-trivial firmware modification.

    8. Radio Control and Telemetry

    RC Receivers: The Human Pilot Interface

    Even on autonomous drones, an RC receiver is typically present as a safety override mechanism. If your autonomous code behaves badly, a human pilot can take over manually.

    RC receivers communicate with flight controllers via several protocols:

    PPM (Pulse Position Modulation): Encodes all channels on a single wire sequentially. Simple but limited bandwidth.

    SBUS: A digital serial protocol used by Futaba and FrSky systems. Sends 16 channels at 100Hz. Requires signal inversion on some flight controllers.

    CRSF (Crossfire): Modern protocol from TBS. Full duplex, ultra-low latency, works over the same long-range radio link as the video feed on FPV systems.

    In your flight controller configuration code, you specify the RC protocol and which channels map to which functions (throttle, roll, pitch, yaw, flight mode switch, etc.).

    Telemetry Radios

    Telemetry radios give you a long-range bidirectional data link between your ground station software and the drone. The SiK radio modems at 915MHz (Americas) or 433MHz (Europe/Asia) are the most common. They connect to a UART on the flight controller and present as a serial port on your laptop, allowing QGroundControl or Mission Planner to communicate with the drone in real time.

    For developers, telemetry radios mean you can run DroneKit or MAVSDK commands from your laptop to a flying drone without a physical cable. The radio introduces latency (typically 50-200ms depending on configuration), which matters if you are writing tight control loops from the ground station. For mission uploads and monitoring, latency is not a significant issue.

    9. Companion Computers: Where Your Smart Code Runs

    For anything beyond basic waypoint missions, you need a companion computer. This is an additional onboard computer, separate from the flight controller, that runs your application code.

    Common Companion Computers

    Raspberry Pi 4 or 5: Affordable, good community support, runs full Linux. Plenty of community examples for drone use. Limited by relatively low performance for computer vision.

    NVIDIA Jetson Nano/Orin: The choice for GPU-accelerated inference. If your code does object detection, landing target recognition, or any neural network inference, Jetson hardware is worth the extra cost and weight.

    Intel NUC or similar x86 boards: Maximum compute power, but heavy and power-hungry. Used in large research drones.

    STM32 or ESP32 microcontrollers: For lightweight edge tasks like sensor interfacing or data logging where a full Linux environment is overkill.

    Companion Computer Communication Pattern

    The standard pattern is: companion computer connects to flight controller via UART or USB-serial, runs MAVROS or DroneKit, and issues high-level commands. The flight controller handles low-level stabilization and motor control.

    Your code on the companion computer should never assume it is the sole authority. The flight controller has its own failsafe logic that can override your commands. Design your code with this in mind: handle failsafe transitions gracefully, listen for mode changes that your code did not initiate, and always have a path to safe landing.

    10. Propellers: The Last Hardware Link Your Motor Commands Flow Through

    Propellers convert motor rotation into thrust. The relationship between propeller size, pitch, and motor KV determines how efficiently your drone converts electrical power into lift.

    Propeller Specifications and Thrust Calculations

    A propeller is described as diameter x pitch, for example 5×4.5 (5 inch diameter, 4.5 inch pitch). Pitch is the distance the propeller would theoretically move forward in one rotation in a solid medium. Higher pitch means more air moved per rotation but also more load on the motor.

    If you are writing a thrust model for simulation or for calculating maximum payload, you need to know propeller efficiency curves. These are measured in grams of thrust per watt of electrical power, and they vary with RPM and airspeed. Propeller databases like UIUC Propeller Data Site have measured performance data for common propellers that you can feed into your simulation models.

    Propeller Direction and Balance

    Propellers come in clockwise (CW) and counterclockwise (CCW) versions to match motor rotation direction. An imbalanced or wrong-direction propeller causes vibration that confuses IMU readings and shows up in your flight data as high-frequency noise.

    When you are debugging erratic flight behavior and the IMU logs show vibration in the 100-300Hz range, the first thing to check is propeller balance and direction. This is a hardware fix, but identifying it is a code/data analysis task.

    11. Putting It All Together: A Programmer’s Mental Model of a Drone

    Now let us assemble this into a coherent mental model you can use when writing code.

    When you call drone.takeoff(altitude=10) in DroneKit, here is what actually happens:

    1. DroneKit sends a COMMAND_LONG MAVLink message with the NAV_TAKEOFF command and altitude parameter to the flight controller over serial.
    2. The flight controller receives the command and enters auto-takeoff mode.
    3. The PID controller starts spinning up motors by increasing the throttle output.
    4. ESCs receive DSHOT packets from the flight controller with increasing throttle values.
    5. Motors spin up, spinning propellers that push air downward and generate lift.
    6. The barometer and GPS measure altitude increase. The IMU measures attitude.
    7. Sensor fusion feeds corrected altitude data back into the PID controller.
    8. The drone reaches 10 meters, the flight controller detects the target altitude, and transitions to hover state.
    9. DroneKit receives a COMMAND_ACK message confirming the command completed.
    10. Your code continues.

    That chain, from your Python line to actual flight, crosses serial communication, a real-time OS, sensor fusion, PID control, digital motor protocols, brushless motor physics, and aerodynamics. Every component in that chain is a potential failure point and a potential debugging location.

    12. Common Programming Mistakes That Come From Not Understanding Hardware

    Let me give you some specific examples of bugs that come from hardware ignorance, because these are the things that will actually cost you time.

    Forgetting to arm the motors before sending throttle commands. In ArduPilot, motors are always in an armed or disarmed state as a safety measure. Sending throttle commands to a disarmed drone does nothing. You must explicitly arm via MAVLink before the ESCs will respond.

    Sending commands in the wrong reference frame. MAVLink position commands can be in local NED (North-East-Down) frame, body frame (relative to where the drone is pointing), or global GPS frame. Sending a “move forward” command in body frame when the drone is pointing west means the drone moves west, not in the direction your human operator considers “forward.” Always be explicit about frames in your code.

    Ignoring EKF (Extended Kalman Filter) health. The EKF is the sensor fusion algorithm in ArduPilot/PX4. If GPS, compass, and barometer data are inconsistent (for example, if the drone launches before GPS gets a good lock), the EKF health flags will indicate a problem. Sending navigation commands when EKF health is bad leads to erratic flight. Your code should check EKF_STATUS_REPORT before starting autonomous missions.

    Not handling communication loss failsafes. If your companion computer crashes or your code throws an exception and stops sending heartbeats, the flight controller will trigger a failsafe after a few seconds, typically RTL (Return to Launch) or land. Design your code so that controlled shutdowns always include a graceful handoff back to the flight controller, not a hard crash that stops heartbeats suddenly.

    Overwhelming the serial bus with MAVLink requests. Requesting every available telemetry stream at maximum frequency is a common beginner mistake. Serial bandwidth is finite. Requesting GPS at 50Hz, attitude at 50Hz, battery status at 50Hz, and a dozen other streams simultaneously can saturate the link and cause command delivery failures. Be selective about which streams you enable and at what rate.

    13. Setting Up Your Development Environment

    For anyone who wants to start coding against this hardware immediately, here is the practical path.

    Software-in-the-Loop (SITL) Simulation

    Before you put code near real hardware, use SITL. Both ArduPilot and PX4 support SITL, which simulates the full flight controller, sensors, and vehicle physics in software. Your code talks to SITL exactly the same way it talks to real hardware.

    ArduPilot SITL can be run natively on Linux or in WSL2 on Windows. Pairing it with QGroundControl gives you a full ground station. DroneKit or MAVSDK code written against SITL runs unmodified on real hardware.

    Gazebo is the most common physics simulator to pair with PX4 SITL. It renders a full 3D environment, simulates wind, simulates camera sensors, and lets you test computer vision pipelines before flying real hardware.

    Logging and Analysis Tools

    ArduPilot Blackbox / .bin logs: Every ArduPilot flight generates a detailed binary log of every sensor reading, control output, and mode change at high frequency. Mission Planner and MAVExplorer can open these logs for analysis.

    PX4 ULog format: PX4’s logging format is similar. Flight Review at review.px4.io is a web tool that visualizes PX4 logs and automatically identifies common tuning problems.

    Blackbox Explorer for Betaflight: If you are working with FPV hardware running Betaflight, Blackbox Explorer decodes the flight controller’s onboard log and shows gyro data, PID outputs, and motor commands on a timeline.

    14. Where to Go From Here

    If you have read this far, you now have a solid conceptual foundation for drone anatomy from a programmer’s perspective. The logical next steps depend on what you want to build.

    If you want to write autonomous navigation code, start with ArduPilot SITL and the DroneKit Python library. Work through basic takeoff-fly-land missions, then add waypoints, then add sensor-based decisions.

    If you want to work on computer vision-based flight, get a Raspberry Pi or Jetson, set up MAVROS, and start with marker-based landing. It is a tractable first project that forces you to understand coordinate frames, camera calibration, and closed-loop visual control all at once.

    If you want to work on firmware-level code, PX4 is more approachable than ArduPilot for custom module development. Their developer documentation is excellent and the uORB message bus makes adding custom sensor drivers relatively clean.

    If you want to go deep on hardware interfacing, buy a Betaflight F4 or F7 flight controller, a cheap 5-inch quadcopter kit, and flash it yourself. Configuring ESC protocols, setting up telemetry, and tuning PIDs on real hardware teaches you things no simulator can replicate.

    Conclusion

    Drone anatomy for programmers explained properly is not about memorizing part names. It is about building a mental model of a complex embedded system so that every line of code you write is grounded in the physical reality it controls.

    You now know that a motor’s KV rating affects your PID tuning, that ESC protocol choice determines your control loop latency, that flight controller firmware defines your programming interface, that GPS latency needs to be compensated in fast autonomous code, that MAVLink is the language your software speaks to autopilots, and that sensor fusion health determines whether your navigation commands will work at all.

    Every one of those connections between software concepts and physical hardware will save you debugging time and make your code more reliable. The drone is not a black box anymore. It is a system you understand, and systems you understand are systems you can build on confidently.

    Quick Reference: Key Terms for Drone Programmers

    TermWhat It Means for Your Code
    KV RatingAffects thrust model and PID tuning sensitivity
    DSHOTDigital ESC protocol with RPM telemetry feedback
    PIDControl algorithm you configure and sometimes implement
    EKFSensor fusion health check before autonomous flight
    MAVLinkThe protocol your drone communication code speaks
    Guided/Offboard ModeThe flight mode that allows external code control
    SITLSoftware simulation environment for safe code testing
    RTK GPSCentimeter-accurate positioning for precision applications
    SBUS/CRSFRC receiver protocols for human override systems
    mAh ConsumedBetter battery state metric than voltage for flight planning

    This article covers drone hardware and software concepts for educational purposes. Always follow local regulations for drone operation and never fly autonomous drones without proper safety measures in place.

    If you are completely new to drones altogether, start with this guide on Types of Drones Explained: Your Complete Beginner’s Guide for 2026 first, then come back here it will make everything below click faster.